Back to Blog
Testing guide

What Is Exploratory Testing in Software Testing

Learn what exploratory testing is, common exploration types, and a step-by-step guide to executing exploratory testing.

Armish Shah
September 16, 2026
September 16, 2026
What Is Exploratory Testing in Software Testing

Testing guide

What Is Exploratory Testing in Software Testing

by:

Armish Shah

September 16, 2026

8

min

Share:

What Is Exploratory Testing in Software Testing | TestFiesta
On this page

Ready to take your testing to
the next level?

Sleek and intuitive workflows
Transparent pricing
Easy migration

Introduction

Manual and automated testing are essential for catching bugs and regressions and ensuring the core functionality of the product works as expected. But even when all tests pass, users can still run into unexpected bugs right away. That’s because both manual and automated tests are scripted, and they only check for issues that were written down ahead of time. Exploratory testing is different; it’s unscripted. 

What Is Exploratory Testing

Exploratory testing is an approach to software testing where testers simultaneously learn about the application, design test cases, and execute them. Unlike traditional scripted testing, which relies on pre-written, step-by-step test plans, exploratory testing encourages testers to rely on their intuition, domain knowledge, and critical thinking to discover defects that structured tests might miss.

Say you are testing the checkout. The scripted test adds an item, enters a valid card, and confirms the order is completed. It passes. In contrast, an exploratory tester adds the item, opens a second tab, removes it from the cart there, then returns to the first tab and pays. That test was not written because nobody thought of it until they were sitting in front of the product with two tabs open.

That said, exploratory testing can be as disciplined as any other intellectual activity, and its quality depends heavily on the tester’s skill. 

Exploratory Testing vs. Ad Hoc Testing

Both ad hoc and exploratory testing are two types of unscripted testing, but they are not the same. Ad hoc testing is informal, unplanned, and leaves no record of what was covered, making it unstructured and unaccountable. In contrast, exploratory testing is unscripted but structured and accountable, following a specific mission, a defined block of time, and detailed notes so you can track exactly what was tested and discovered.

When Should You Use Exploratory Testing

Exploratory testing pays off most where writing test cases first would be impossible or wasted, including the following cases.

  • When requirements are thin or still moving: If the requirements are thin, there is nothing to write detailed cases from. Exploring the feature is a better option in that case.
  • On brand-new features: Brand-new features should be explored after they are shipped because that allows the team to verify the functionality of what was actually shipped.
  • Around bug fixes and risky changes: Areas around risky changes and bugs should be explored because they are critical in nature.
  • Before a release, in the gaps: Automated suites cover the expected paths. A focused exploratory session covers the paths that nobody thought of.
  • On usability and real-world flows: A test case can confirm a button works. It cannot tell you that the flow takes eleven clicks, and the error sits below the fold. That’s something exploratory testing can confirm.

Types of Exploratory Testing

There are a few ways to perform exploratory testing, including:

1. Freestyle Exploratory Testing

Freestyle exploratory testing doesn’t have any rules, charter, or coverage target. It’s useful when you need to get familiar with an application quickly, verify another tester’s work, investigate a defect, or run a fast smoke check.

2. Scenario-Based Exploratory Testing

Scenario-based exploratory testing is built around realistic user scenarios. Testers mimic how people actually use the system, explore different paths within a scenario, and watch for breakdowns in the flow. It’s more structured than freestyle and well suited to new features with a clear user journey.

3. Strategy-Based Exploratory Testing

Strategy-based exploratory testing is guided by an overarching strategy, with testers applying established software testing techniques such as boundary value analysis, equivalence partitioning, risk-based testing, and error guessing. Experienced testers tend to be most effective here because the technique supplies structure while judgment decides where to aim it.

4. Session-Based Test Management (SBTM)

Session-based test management (SBTM) is a formal framework rather than a loose style. Testing is organized into time-boxed sessions with charters, reports, and debriefs. 

5. Pair Testing

Pair testing involves two people at one machine, one driving and one observing. It’s slower on raw coverage, but the observation catches what the driver misses.

6. Bug Hunts

Bug hunts refer to a focused group session, often including people from outside QA, aimed at one area for a fixed window. It’s beneficial because it gets fresh eyes on a product.

How to Do Exploratory Testing: Step by Step

The steps below follow session-based test management, the most widely used framework for running exploratory testing in a way you can report on. 

Step 1: Write a Testing Charter

A charter is a short statement of what the session is for. It sets direction without prescribing steps. Charters are created before testing starts, can be changed or updated at any time, and are often built from a specification, a test plan, or the results of earlier sessions. 

Step 2: Time-Box the Session

Set an explicit time limit before you begin, typically 60 to 90 minutes. Time-boxing prevents fatigue, keeps testing focused on the charter, and makes session results easier to schedule and compare across team members.

Step 3: Explore and Take Notes in Real Time

During the session, testers execute tests actively guided by the charter while maintaining the flexibility to follow unexpected leads, explore interesting side paths, and adapt based on real-time observations and critical judgment.

As you explore, record concise notes in real time to capture essential details without interrupting your cognitive flow. Key areas to document include coverage and paths, environment and setup, key decisions and questions, Anomalies, and observations.

Maintaining consistent, high-quality notes ensures the session is transparent and fully reproducible for the post-session debrief, striking a balance between lightweight logging and clear accountability.

Step 4: Investigate Anomalies Deeper

When you encounter unexpected behavior, edge cases, or potential defects during a session, pause to investigate and isolate the anomaly. Verify whether the behavior is consistently reproducible, determine the specific trigger conditions or environmental factors, and assess its severity. However, maintain a balance with your time box. 

If an issue requires prolonged root-cause analysis or extensive log diving, note the initial details and park it for dedicated investigation after the session so you don’t exhaust your remaining session time.

Step 5: Debrief and Document Findings

Once the time-box expires, hold a short debrief session (typically 5 to 15 minutes) with a lead, peer, or product owner. Review the session notes, charter coverage, time allocation (split across test execution, bug investigation, and setup), and key observations. 

Log all confirmed bugs into your tracking system with full reproduction steps, logs, and screenshots attached. Finally, evaluate whether any impactful exploratory paths or discoveries should be converted into automated regression test cases or future testing charters.

Advantages and Limitations of Exploratory Testing

Exploratory testing offers high flexibility and rapid bug discovery, though it requires skilled testers and disciplined documentation to maintain accountability. Here are some notable advantages and limitations of exploratory testing:

Advantages of Exploratory Testing

  • Finds unscripted defects that traditional test cases miss.
  • Requires zero upfront test preparation, ideal for rapidly changing features.
  • Adapts immediately in real-time to focus on newly uncovered risks.
  • Builds domain and product knowledge quickly to improve future scripted tests.
  • Leverages human intuition to evaluate usability and end-to-end user flows.
  • Provides high flexibility, allowing test charters to shift with daily priorities.

Limitations of Exploratory Testing

  • Lacks heavy documentation, which can reduce traceability and test reproducibility.
  • Relies heavily on individual tester skill, leading to inconsistent coverage across team members.
  • Prone to tester bias, as individuals often gravitate toward familiar product areas.
  • Difficult to quantify or prove test coverage without strict session logging.
  • Session metrics can easily skew due to reporting discrepancies or productivity variations.
  • Cognitively demanding, typically limiting testers to a few high-quality sessions per day.

Most of these limitations stem from documentation and management challenges rather than exploration itself, issues that proper tooling can easily resolve.

How TestFiesta Helps Turn Exploratory Testing Results Into Clarity

The hard part of exploratory testing is what happens after: proving what got covered, keeping findings attached to the work that produced them, and making sure good ideas from a session do not evaporate. TestFiesta can help.

Built-In Bug Tracking: TestFiesta has native bug tracking inside the platform, so a defect found mid-session is logged without leaving the test flow, with screenshots and logs attached. Every defect links to the exact test execution that found it, which keeps the context alive forever.

Organized Sessions: Flexible tagging covers cases, runs, users, milestones, and defects, so you can slice reports by feature, risk, sprint, or team without a rigid folder hierarchy. That is how a charter-per-area approach stays readable even after many sessions.

Permanent Coverage: When a session uncovers a path worth checking every release, AI test case creation generates structured cases with steps, expected results, and tags from your requirements or a prompt, and shared steps let you define reusable flows like login or checkout once and reference them everywhere. The discovery becomes a regression test instead of a note someone loses.

Manual and Automated Results Live Together: The automation API feeds automated results into the same platform, so exploratory findings and automated coverage appear in one view. Jira and GitHub integrations auto-map fields and keep requirements, bugs, and coverage aligned, so a bug found during exploration reaches the developer with full context attached.

Every feature is included at one flat price of $10 per user per month, with no tiers and no feature gates.

Streamline your QA workflow and stop letting valuable testing insights slip through the cracks.

With TestFiesta, you get an all-in-one platform built for modern testing teams.

Start your free trial today

FAQs

Is exploratory testing the same as manual testing?

No, exploratory testing is not the same as manual testing. Manual testing is often scripted and describes how a test is run by a person rather than a machine. Exploratory testing describes how a test is designed in the moment rather than in advance. Exploratory testing is a form of manual testing, but not all manual tests are exploratory.

Can exploratory testing be automated?

No, exploratory testing cannot be automated since it depends on a person deciding what to try next instead of relying on automation frameworks and scripts. However, certain tools can make exploratory testing easier. 

How do you measure the effectiveness of exploratory testing?

You can measure the effectiveness of exploratory testing through detailed session reports, which can include sessions per testing area, time spent on test design, bug investigation, and setup. 

Tool

Pricing

TestFiesta

Free user accounts available; $10 per active user per month for teams

TestRail

Professional: $40 per seat per month

Enterprise: $76 per seat per month (billed annually)

Xray

Free trial; Standard: $10 per month for the first 10 users (price increases after 10 users)

Advanced: $12 per month for the first 10 users (price increases after 10 users)

Zephyr

Free trial; Standard: ~$10 per month for first 10 users (price increases after 10 users)

Advanced: ~$15 per month for the first 10 users (price increases after 10 users)

qTest

14‑day free trial; pricing requires demo & quote (no transparent pricing)

Qase

Free: $0/user/month (up to 3 users)

Startup: $24/user/month

Business: $30/user/month

Enterprise: custom pricing

TestMo

Team: $99/month for 10 users

Business: $329/month for 25 users

Enterprise: $549/month for 25 users

BrowserStack Test Management

Free plan available

Team: $149/month for 5 users

Team Pro: $249/month for 5 users

Team Ultimate: Contact sales

TestFLO

Annual subscription (specific amounts per user band), e.g., Up to 50 users: $1,186/yr; Up to 100 users: $2,767/yr; etc.

QA Touch

Free: $0 (very limited)

Startup: $5/user/month

Professional: $7/user/month

TestMonitor

Starter: $13/user/month

Professional: $20/user/month

Custom: custom pricing

Azure Test Plans

Pricing tied to Azure DevOps services (no specific rate given)

QMetry

14‑day free trial; custom quote pricing

PractiTest

Team: $54/user/month (minimum 5 users)

Corporate: custom pricing

Black Box Testing

White Box Testing

Coding Knowledge

No code knowledge needed

Requires understanding of code and internal structure

Focus

QA testers, end users, domain experts

Developers, technical testers

Performed By

High-level and strategic, outlining approach and objectives.

Detailed and specific, providing step-by-step instructions for execution.

Coverage

Functional coverage based on requirements

Code coverage

Defects type found

Functional issues, usability problems, interface defects

Logic errors, code inefficiencies, security vulnerabilities

Limitations

Cannot test internal logic or code paths

Time-consuming, requires technical expertise

Aspect

Test Plan

Test Case

Purpose

Defines the overall testing strategy, scope, and approach for a project or release.

Validates that a specific feature or functionality works as expected.

Scope

Covers the entire testing effort, including what will be tested, resources, timelines, and risks.

Focuses on a single scenario or functionality in the broader scope.

Level of Detail

High-level and strategic, outlining approach and objectives.

Detailed and specific, providing step-by-step instructions for execution.

Audience

Project managers, stakeholders, QA leads, and development teams.

QA testers and engineers.

When It's Created

Early in the project, before testing begins.

After the test plan is defined and the requirements are clear.

Content

Scope, objectives, strategy, resources, schedule, environment details, and risk management.

Test case ID, title, preconditions, test steps, expected results, and test data.

Frequency of Updates

Updated periodically as project scope or strategy changes.

Updated frequently as features change or bugs are fixed.

Outcome

Provides direction and clarifies what to test and how to approach it.

Produces pass or fail results that indicate whether specific functionality works correctly.

Tool

Key Highlights

Automation Support

Team Size

Pricing

Ideal For

TestFiesta

Flexible workflows, tags, custom fields, and AI copilot

Yes (integrations + API)

Small → Large

Free solo; $10/active user/mo

Flexible QA teams, budget‑friendly

TestRail

Structured test plans, strong analytics

Yes (wide integrations)

Mid → Large

~$40–$74/user/mo)

Medium/large QA teams

Xray

Jira‑native, manual/
automated/
BDD

Yes (CI/CD + Jira)

Small → Large

Starts ~$10/mo for 10 Jira users

Jira‑centric QA teams

Zephyr

Jira test execution & tracking

Yes

Small → Large

~$10/user/mo (Squad)

Agile Jira teams

qTest

Enterprise analytics, traceability

Yes (40+ integrations)

Mid → Large

Custom pricing

Large/distributed QA

Qase

Clean UI, automation integrations

Yes

Small → Mid

Free up to 3 users; ~$24/user/mo

Small–mid QA teams

TestMo

Unified manual + automated tests

Yes

Small → Mid

~$99/mo for 10 users

Agile cross‑functional QA

BrowserStack Test Management

AI test generation + reporting

Yes

Small → Enterprise

Free tier; starts ~$149/mo/5 users

Teams with automation + real device testing

TestFLO

Jira add‑on test planning

Yes (via Jira)

Mid → Large

Annual subscription starts at $1,100

Jira & enterprise teams

QA Touch

Built‑in bug tracking

Yes

Small → Mid

~$5–$7/user/mo

Budget-conscious teams

TestMonitor

Simple test/run management

Yes

Small → Mid

~$13–$20/user/mo

Basic QA teams

Azure Test Plans

Manual & exploratory testing

Yes (Azure DevOps)

Mid → Large

Depends on the Azure DevOps plan

Microsoft ecosystem teams

QMetry

Advanced traceability & compliance

Yes

Mid → Large

Not transparent (quote)

Large regulated QA

PractiTest

End‑to‑end traceability + dashboards

Yes

Mid → Large

~$54+/user/mo

Visibility & control focused QA

Related Articles

Introduction

Testing as the last checkpoint is one of the most common practices in the traditional development processes. After a long sprint, testing usually takes a back seat and is pushed to the end, which results in poor, urgent testing and delayed regression cycles. 

Shift-left testing is a philosophy that focuses on improving testing and including it in the process from the get-go. In this guide, we’ll cover shift-left testing in detail, along with its four variants, how it fits into your sprint, which tools you need, and which mistakes to avoid. 

What Is Shift Left Testing

Shift-left testing refers to starting the testing activities as early as possible in the software development lifecycle rather than saving them for the end. The name “shift-left” comes from how development timelines are drawn. 

In the development chart, requirements sit on the left, production on the right, and testing has traditionally lived near the right edge (as visible in the picture below).
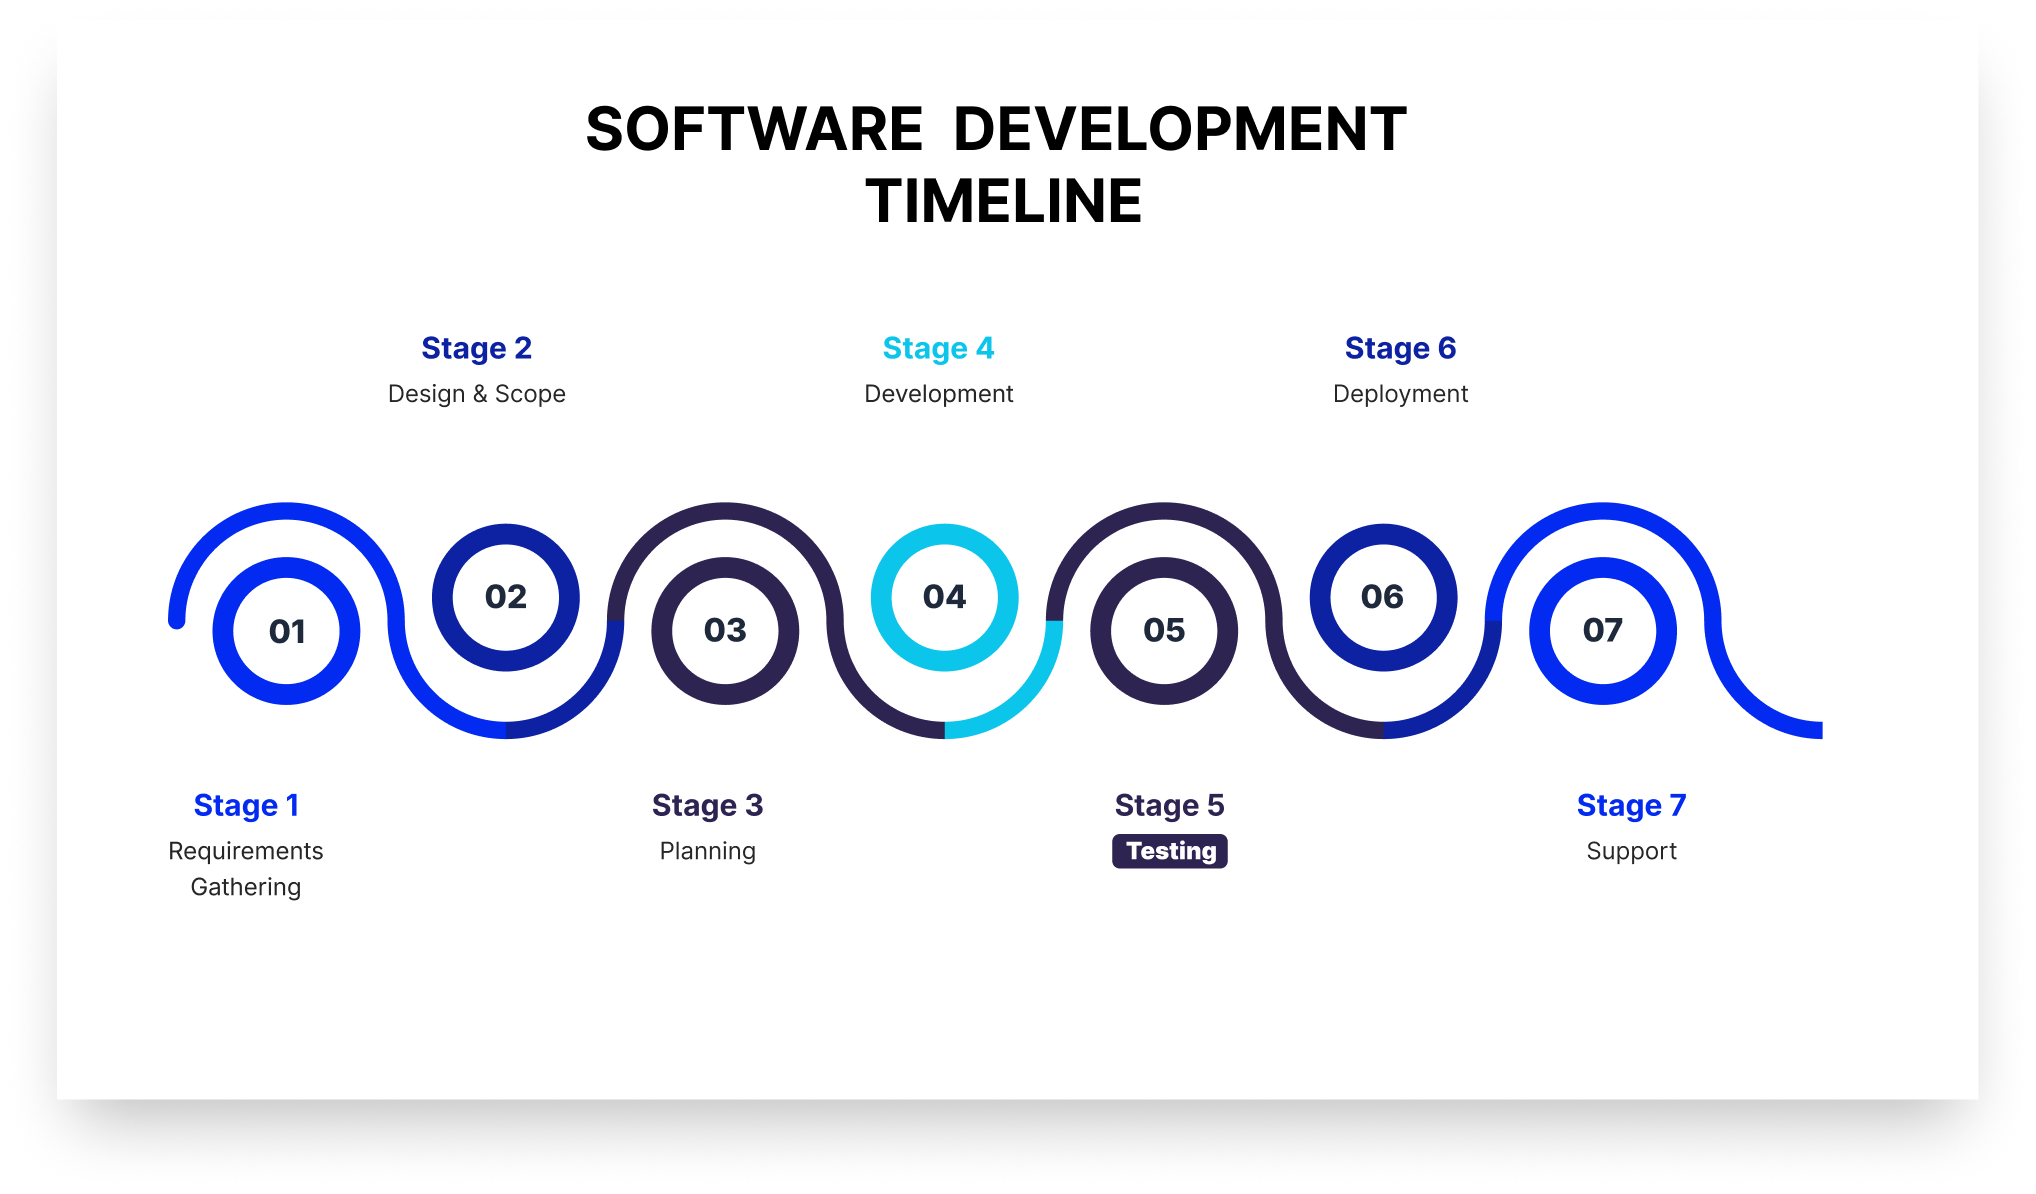
The software development timeline chart or the software development life cycle.

 “Shifting left” moves testing toward the beginning of that line, so it runs simultaneously with the other stages of the development process. 

A core benefit of shift-left testing is covers activities that prevent defects from being written at all. It reviews requirements for testability and defines acceptance criteria before a test is written. As a result, a defect caught in a requirements review never becomes code, saving time for developers. 

How Shift Left Testing Is Different From Traditional Testing

The difference between traditional testing and shift-left testing is not just about the tools you're using. It's more about how and when the QA will be involved in the product development. The table below shows the difference between shift-left testing and traditional testing in various aspects.

Traditional testing Shift left testing
When testing starts After development completes At requirements and design
Who owns quality The QA team Developers, QA, and security together
Feedback loop Days to weeks Minutes to hours
What triggers a test run A release candidate or handoff A commit or pull request
Defect discovery point Test phase or production Design, commit, or PR review
QA's primary role Finding defects Preventing them, plus deep exploratory work

The 4 Types of Shift Left Testing

Here are four common variants or types of shift-left testing that most agile teams follow:

1. Traditional Shift Left

Traditional shift-left testing moves testing down and slightly left on the V model (see the image below). 
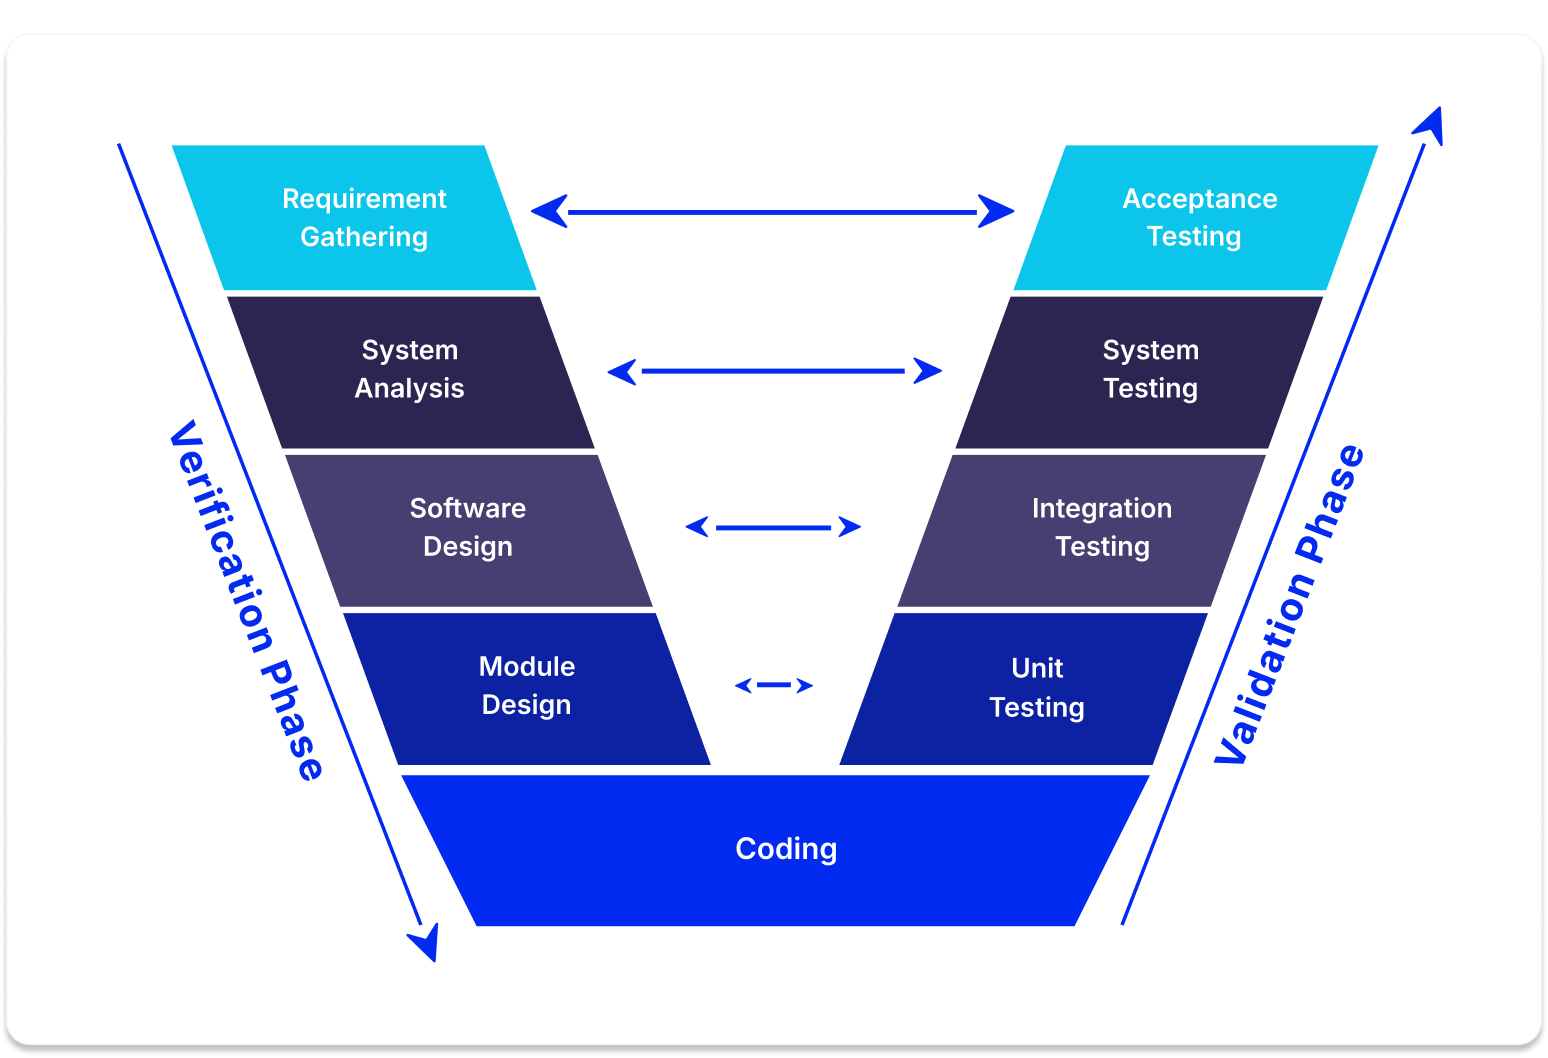
The V model in software testing

The V-Model is a step-by-step blueprint for building and testing software where every single development phase has a matching testing phase. It gets its name because the process bends upward after the coding stage, making the shape of the letter V.

It’s the type most people visualize when they talk about shift-left testing. For instance, if your team performs unit tests and integration tests early on, you’re doing traditional shift-left testing. 

2. Incremental Shift Left

In incremental shift-left testing, the testing project breaks into smaller increments, each with its own V model (see the picture below). 
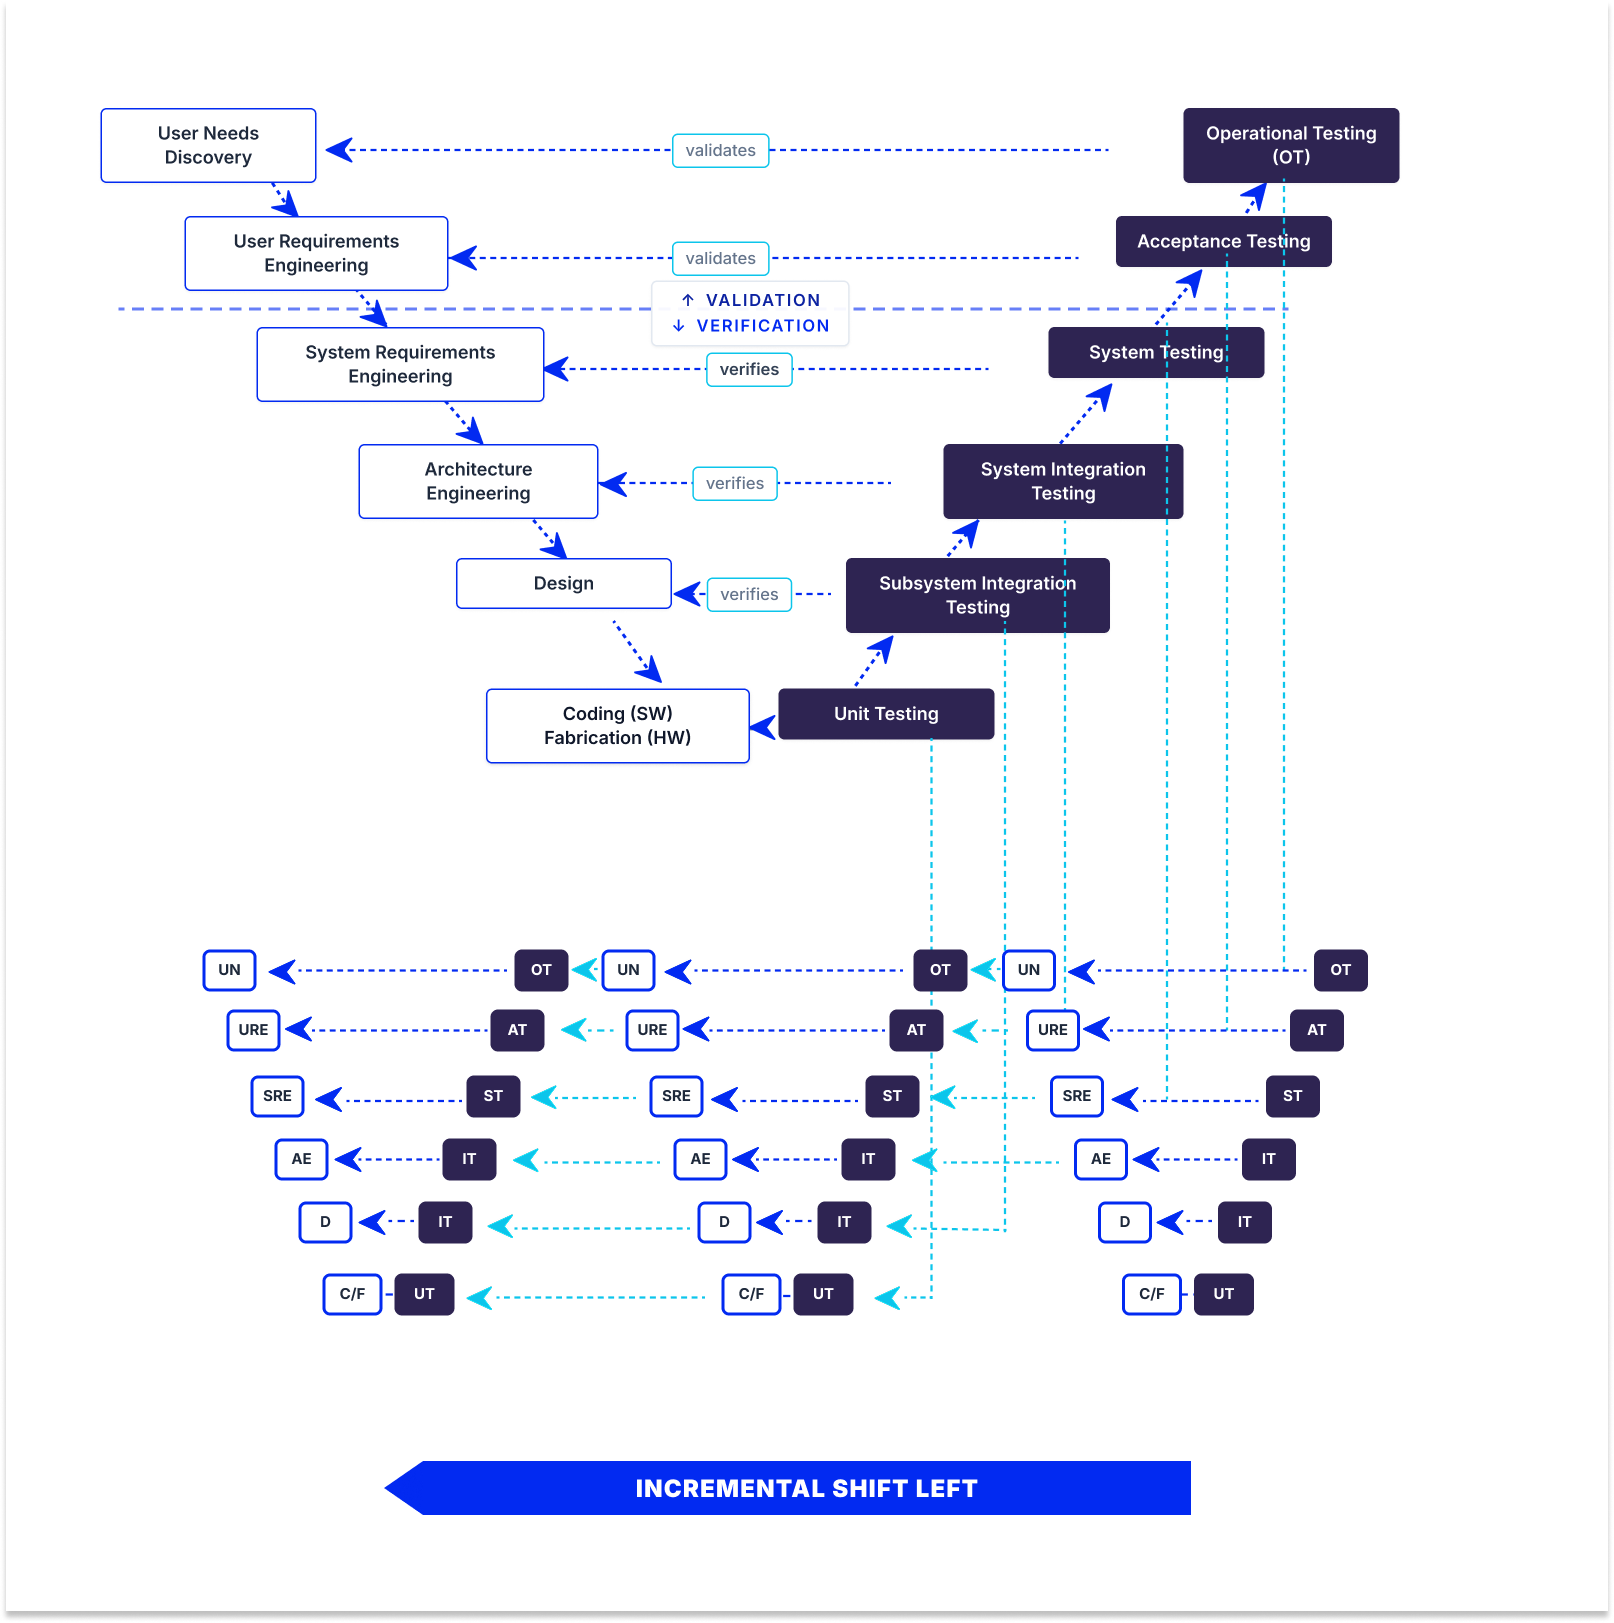
 Incremental shift-left testing where the V model breaks into smaller V models.

As a result, testing happens per increment rather than only once at the end. When each increment ships, developmental and operational testing shift left together. This is popular for large, complex systems with substantial hardware components, where you can’t test the whole system at once but can validate each subsystem as it’s built.

3. Agile/DevOps Shift Left

In Agile/DevOps shift-left testing, testing happens inside short sprints. Each sprint contains its own development and testing work. This means automated tests are triggered whenever there’s a code change in the CI/CD pipeline, so developers get the feedback the same day they change the code. 

4. Model-Based Shift Left

Model-based shift-left testing tests your model instead of code. It tests executable requirements, architecture, and design models, so testing begins almost immediately without waiting for code. The primary benefit of model-based shift-left testing is that you can catch requirements and expensive design defects. The catch is that model-based shift-left testing requires formal, executable models, which is why there is not a large adoption of this approach. 

Why DevOps Recommends Shift-Left Testing Principles

DevOps recommends shift-left testing principles for four reasons:

1. CI/CD pipelines require quality gates at every stage: A pipeline is a series of automated decisions about whether a change can proceed. If the only real check sits at the end, the pipeline isn’t deciding anything but only moving code toward one manual gate. Every stage needs its own criteria, including build, unit tests, static analysis, integration tests, and security scans.

2. Continuous deployment can’t wait for a manual QA cycle: If you deploy several times a day and your regression cycle takes three days, manual testing doesn’t work. If you stick to manual QA instead of automation, either deployment frequency drops to match testing or testing gets skipped. 

3. Shared quality ownership aligns with DevOps culture: DevOps dissolves the wall between development and operations. Leaving the “wall” of testing standing between development and QA reintroduces the same problem that DevOps tries to solve.

4. Faster feedback loops reduce context switching: A developer who gets a test failure immediately after pushing the change is still holding it fresh in their head, as opposed to someone who gets it later and has to find the context again.

How Does Automated Shift Left Testing Work

Automated shift-left testing relies on running fast and inexpensive checks early in the development process. It saves slow and expensive tests for later stages when code is more stable. 

The process starts at the pre-commit stage, where quick scans catch basic issues, such as formatting problems and leaked passwords. Next, when code is submitted for review, the system runs thorough unit tests and security checks within minutes. If anything fails at this review stage, the code cannot be merged into the main project. 

After merging, deeper integration checks and container scans run to ensure different parts of the system work together. Finally, comprehensive performance and end-to-end tests are run before the software is released to the public. Splitting tests into these distinct stages keeps the process fast so developers actually use it.

Mistakes to Avoid When Automating for Shift-Left Testing

When implementing automated shift-left testing, avoid these common pitfalls:

  • Writing tests after the fact: Tests written after code exists only confirm current behavior, including bugs, rather than validating requirements. Write tests from acceptance criteria to catch actual defects.
  • Slow test suites: Tests taking longer than 10 minutes force context switching as developers change tasks. Parallelize, stage tests, and trim low-value checks to keep runs fast.
  • Lack of ownership model: Clearly define who writes unit tests, maintains integration suites, and fixes broken pipelines. Without clear ownership, test suites decay and flaky tests get ignored.
  • Focusing on line coverage over defect escape rate: High line coverage does not guarantee meaningful assertions. Track the defect escape rate to measure true effectiveness.

Shift Left Testing Benefits

Adopting shift-left testing offers important organizational and operational benefits, including:

  • Lower defect cost: Bugs identified early in development are substantially cheaper and simpler to resolve than those discovered in production.
  • Faster release cycles: Continuous quality checks eliminate long stabilization periods prior to deployment.
  • Fewer production defects: Early checks catch architecture and requirements flaws before code reaches end users.
  • Shorter feedback loops: Developers address feedback immediately while context is still fresh.
  • Security cost reduction: Catching vulnerabilities during review avoids costly post-release incident response and patches.
  • Better collaboration: Early QA involvement fosters shared quality ownership across engineering teams.

Shift Left Testing Tools Worth Knowing in 2026

Effective shift-left testing relies on a modern toolkit tailored to every phase of the development lifecycle. Here are the top tools and frameworks essential for implementing shift-left testing in 2026:

Static Analysis and Secret Scanning

SonarQube: Analyzes source code for bugs and security vulnerabilities, enforcing quality gates directly on pull requests.

Semgrep: Lightweight static analysis using custom, code-like rules for fast feedback during development.

TruffleHog & Gitleaks: Scan repositories and commit histories via pre-commit hooks to catch secrets and API keys before they are pushed.

Unit and Integration Testing

JUnit, pytest & Jest: Essential unit testing frameworks for Java, Python, and JavaScript to build fast, automated test suites.

Testcontainers: Provides throwaway Docker instances for databases and services, removing shared-environment bottlenecks during integration tests.

API and Contract Testing

Postman & Newman: Enables teams to author API tests in a GUI and execute them automatically in CI/CD pipelines.

Pact: Facilitates consumer-driven contract testing to verify microservices independently without full deployments.

Dependency and Container Security

Snyk automatically scans third-party dependencies for vulnerabilities and opens automated pull requests for fixes.

Trivy: Fast open-source scanner for container images, filesystems, and infrastructure as code.

Trivy is an open-source scanner covering container images, filesystems, and infrastructure as code, fast enough to sit inside a build without slowing it down.

CI/CD Orchestration

GitHub Actions, GitLab CI & Jenkins: Automate and orchestrate pipeline stages, enforcing quality gates before code merges.

Shift Left vs. Shift Right Testing: What’s the Difference

Shift-left testing moves testing (left) earlier in the process, alongside or even before development. Shift-right testing moves testing (right) later into the process, into the production environment, with real data. 

The entire concept of shift-right testing is that some defects cannot be truly uncovered before real users hit real infrastructure, so it tests on actual traffic patterns, third-party behavior under load, and edge cases

TestFiesta Gives Your Shift Left Strategy Somewhere to Land

Shift-left testing aggregates results across multiple systems (CI unit tests, post-merge contract tests, PR security scans, and sprint exploratory sessions), often making release readiness difficult to track.

TestFiesta consolidates these sources into a single view by ingesting automated CI pipeline results alongside manual and exploratory test outcomes through its Automation API.

Reusable configurations allow test cases to execute across multiple browsers, devices, and environments without duplication, while shared steps centralize common workflows like login or checkout to streamline suite maintenance.

Built-in defect tracking connects failures directly to test executions. Integrations with Jira and GitHub automatically sync fields, update statuses, and create context-rich issues from failed runs.

Organizations use folders, tags, and custom fields to map automated run data. Pricing is a flat $10 per user per month with all features included.

Ready to Elevate Your Shift-Left Testing Strategy?

Streamline your quality workflow, centralize your test results, and empower your team to ship faster with confidence.

Start your free trial today

FAQs

Does shift-left testing mean developers replace QA engineers?

No, shift-left testing does not mean that developers replace QA engineers. It changes what QA spends time on. Repetitive testing is automated, and developers write tests alongside their code, while QA moves toward work that requires critical judgment, such as reviewing requirements for testability, designing test strategy, exploratory testing, and owning the quality signal. 

How do you measure whether shift-left testing is actually working?

To measure whether shift-left testing is actually working, you should track essential software testing metrics, including defect escape rate, the percentage of defects found in production rather than before release, mean time to detect, and pipeline duration, since a slow pipeline gets bypassed. 

What’s the difference between shift-left testing and test-driven development (TDD)?

Shift-left testing is a broad strategy that moves all quality activities, including requirements reviews, static analysis, and security scans, earlier in the development process. Test-driven development (TDD) is just one specific practice within that broader strategy, where you write a failing test before writing the code to pass it and refactor the results. Simply put, you can practice shift-left testing without using TDD, but you cannot do TDD without shifting left.
Testing guide
Best practices

Introduction

Manual and automated testing are essential for catching bugs and regressions and ensuring the core functionality of the product works as expected. But even when all tests pass, users can still run into unexpected bugs right away. That’s because both manual and automated tests are scripted, and they only check for issues that were written down ahead of time. Exploratory testing is different; it’s unscripted. 

What Is Exploratory Testing

Exploratory testing is an approach to software testing where testers simultaneously learn about the application, design test cases, and execute them. Unlike traditional scripted testing, which relies on pre-written, step-by-step test plans, exploratory testing encourages testers to rely on their intuition, domain knowledge, and critical thinking to discover defects that structured tests might miss.

Say you are testing the checkout. The scripted test adds an item, enters a valid card, and confirms the order is completed. It passes. In contrast, an exploratory tester adds the item, opens a second tab, removes it from the cart there, then returns to the first tab and pays. That test was not written because nobody thought of it until they were sitting in front of the product with two tabs open.

That said, exploratory testing can be as disciplined as any other intellectual activity, and its quality depends heavily on the tester’s skill. 

Exploratory Testing vs. Ad Hoc Testing

Both ad hoc and exploratory testing are two types of unscripted testing, but they are not the same. Ad hoc testing is informal, unplanned, and leaves no record of what was covered, making it unstructured and unaccountable. In contrast, exploratory testing is unscripted but structured and accountable, following a specific mission, a defined block of time, and detailed notes so you can track exactly what was tested and discovered.

When Should You Use Exploratory Testing

Exploratory testing pays off most where writing test cases first would be impossible or wasted, including the following cases.

  • When requirements are thin or still moving: If the requirements are thin, there is nothing to write detailed cases from. Exploring the feature is a better option in that case.
  • On brand-new features: Brand-new features should be explored after they are shipped because that allows the team to verify the functionality of what was actually shipped.
  • Around bug fixes and risky changes: Areas around risky changes and bugs should be explored because they are critical in nature.
  • Before a release, in the gaps: Automated suites cover the expected paths. A focused exploratory session covers the paths that nobody thought of.
  • On usability and real-world flows: A test case can confirm a button works. It cannot tell you that the flow takes eleven clicks, and the error sits below the fold. That’s something exploratory testing can confirm.

Types of Exploratory Testing

There are a few ways to perform exploratory testing, including:

1. Freestyle Exploratory Testing

Freestyle exploratory testing doesn’t have any rules, charter, or coverage target. It’s useful when you need to get familiar with an application quickly, verify another tester’s work, investigate a defect, or run a fast smoke check.

2. Scenario-Based Exploratory Testing

Scenario-based exploratory testing is built around realistic user scenarios. Testers mimic how people actually use the system, explore different paths within a scenario, and watch for breakdowns in the flow. It’s more structured than freestyle and well suited to new features with a clear user journey.

3. Strategy-Based Exploratory Testing

Strategy-based exploratory testing is guided by an overarching strategy, with testers applying established software testing techniques such as boundary value analysis, equivalence partitioning, risk-based testing, and error guessing. Experienced testers tend to be most effective here because the technique supplies structure while judgment decides where to aim it.

4. Session-Based Test Management (SBTM)

Session-based test management (SBTM) is a formal framework rather than a loose style. Testing is organized into time-boxed sessions with charters, reports, and debriefs. 

5. Pair Testing

Pair testing involves two people at one machine, one driving and one observing. It’s slower on raw coverage, but the observation catches what the driver misses.

6. Bug Hunts

Bug hunts refer to a focused group session, often including people from outside QA, aimed at one area for a fixed window. It’s beneficial because it gets fresh eyes on a product.

How to Do Exploratory Testing: Step by Step

The steps below follow session-based test management, the most widely used framework for running exploratory testing in a way you can report on. 

Step 1: Write a Testing Charter

A charter is a short statement of what the session is for. It sets direction without prescribing steps. Charters are created before testing starts, can be changed or updated at any time, and are often built from a specification, a test plan, or the results of earlier sessions. 

Step 2: Time-Box the Session

Set an explicit time limit before you begin, typically 60 to 90 minutes. Time-boxing prevents fatigue, keeps testing focused on the charter, and makes session results easier to schedule and compare across team members.

Step 3: Explore and Take Notes in Real Time

During the session, testers execute tests actively guided by the charter while maintaining the flexibility to follow unexpected leads, explore interesting side paths, and adapt based on real-time observations and critical judgment.

As you explore, record concise notes in real time to capture essential details without interrupting your cognitive flow. Key areas to document include coverage and paths, environment and setup, key decisions and questions, Anomalies, and observations.

Maintaining consistent, high-quality notes ensures the session is transparent and fully reproducible for the post-session debrief, striking a balance between lightweight logging and clear accountability.

Step 4: Investigate Anomalies Deeper

When you encounter unexpected behavior, edge cases, or potential defects during a session, pause to investigate and isolate the anomaly. Verify whether the behavior is consistently reproducible, determine the specific trigger conditions or environmental factors, and assess its severity. However, maintain a balance with your time box. 

If an issue requires prolonged root-cause analysis or extensive log diving, note the initial details and park it for dedicated investigation after the session so you don’t exhaust your remaining session time.

Step 5: Debrief and Document Findings

Once the time-box expires, hold a short debrief session (typically 5 to 15 minutes) with a lead, peer, or product owner. Review the session notes, charter coverage, time allocation (split across test execution, bug investigation, and setup), and key observations. 

Log all confirmed bugs into your tracking system with full reproduction steps, logs, and screenshots attached. Finally, evaluate whether any impactful exploratory paths or discoveries should be converted into automated regression test cases or future testing charters.

Advantages and Limitations of Exploratory Testing

Exploratory testing offers high flexibility and rapid bug discovery, though it requires skilled testers and disciplined documentation to maintain accountability. Here are some notable advantages and limitations of exploratory testing:

Advantages of Exploratory Testing

  • Finds unscripted defects that traditional test cases miss.
  • Requires zero upfront test preparation, ideal for rapidly changing features.
  • Adapts immediately in real-time to focus on newly uncovered risks.
  • Builds domain and product knowledge quickly to improve future scripted tests.
  • Leverages human intuition to evaluate usability and end-to-end user flows.
  • Provides high flexibility, allowing test charters to shift with daily priorities.

Limitations of Exploratory Testing

  • Lacks heavy documentation, which can reduce traceability and test reproducibility.
  • Relies heavily on individual tester skill, leading to inconsistent coverage across team members.
  • Prone to tester bias, as individuals often gravitate toward familiar product areas.
  • Difficult to quantify or prove test coverage without strict session logging.
  • Session metrics can easily skew due to reporting discrepancies or productivity variations.
  • Cognitively demanding, typically limiting testers to a few high-quality sessions per day.

Most of these limitations stem from documentation and management challenges rather than exploration itself, issues that proper tooling can easily resolve.

How TestFiesta Helps Turn Exploratory Testing Results Into Clarity

The hard part of exploratory testing is what happens after: proving what got covered, keeping findings attached to the work that produced them, and making sure good ideas from a session do not evaporate. TestFiesta can help.

Built-In Bug Tracking: TestFiesta has native bug tracking inside the platform, so a defect found mid-session is logged without leaving the test flow, with screenshots and logs attached. Every defect links to the exact test execution that found it, which keeps the context alive forever.

Organized Sessions: Flexible tagging covers cases, runs, users, milestones, and defects, so you can slice reports by feature, risk, sprint, or team without a rigid folder hierarchy. That is how a charter-per-area approach stays readable even after many sessions.

Permanent Coverage: When a session uncovers a path worth checking every release, AI test case creation generates structured cases with steps, expected results, and tags from your requirements or a prompt, and shared steps let you define reusable flows like login or checkout once and reference them everywhere. The discovery becomes a regression test instead of a note someone loses.

Manual and Automated Results Live Together: The automation API feeds automated results into the same platform, so exploratory findings and automated coverage appear in one view. Jira and GitHub integrations auto-map fields and keep requirements, bugs, and coverage aligned, so a bug found during exploration reaches the developer with full context attached.

Every feature is included at one flat price of $10 per user per month, with no tiers and no feature gates.

Streamline your QA workflow and stop letting valuable testing insights slip through the cracks.

With TestFiesta, you get an all-in-one platform built for modern testing teams.

Start your free trial today

FAQs

Is exploratory testing the same as manual testing?

No, exploratory testing is not the same as manual testing. Manual testing is often scripted and describes how a test is run by a person rather than a machine. Exploratory testing describes how a test is designed in the moment rather than in advance. Exploratory testing is a form of manual testing, but not all manual tests are exploratory.

Can exploratory testing be automated?

No, exploratory testing cannot be automated since it depends on a person deciding what to try next instead of relying on automation frameworks and scripts. However, certain tools can make exploratory testing easier. 

How do you measure the effectiveness of exploratory testing?

You can measure the effectiveness of exploratory testing through detailed session reports, which can include sessions per testing area, time spent on test design, bug investigation, and setup. 

Testing guide

Introduction

Security is often treated as the final gatekeeper in the development lifecycle, but waiting until the end is a recipe for disaster. From broken access control to supply chain vulnerabilities, modern applications face constant threats. 

If you’re wondering which tools actually move the needle, you’re in the right place. We’ll explore security testing in detail, including the seven main types of security testing, actionable strategies for CI/CD integration, and the tools that matter most for today’s engineering teams.

What Is Security Testing in Software

Security testing is the practice of checking an application for weaknesses that an attacker could exploit to steal data, gain access they should not have, disrupt service, or abuse functionality. It covers the code, the running application, the third-party components it depends on, and the infrastructure it runs on.

Unlike functional testing, where you verify expected behavior against a spec, security testing spends most of its time on unexpected behavior. The tester’s job is to send inputs the developer never planned for and see what breaks.

What Security Testing Actually Tests For

The specifics vary by application, but most security testing targets the same core categories of weakness:

  • Unauthorized access to data or functionality. Broken access control is the most common serious flaw in web applications. It shows up when a regular user can view another user’s records by changing an ID in the URL or calling an admin endpoint that the UI never exposed.
  • Injection flaws. SQL injection, command injection, and cross-site scripting (XSS) all happen when untrusted user input reaches a sensitive operation without proper handling. A search box that passes its value straight into a database query is a textbook example.
  • Authentication and session weaknesses. Weak password policies, missing rate limiting on login, session tokens that never expire, and predictable password reset links all give attackers a way in through the front door.
  • Vulnerable open-source dependencies. Modern applications pull in hundreds of third-party packages. If one of them has a known CVE and you are running the affected version, the vulnerability is yours regardless of how clean your own code is.
  • Sensitive data exposure. Weak or missing encryption, secrets committed to source control, and misconfigured storage buckets left readable by the public all fall here.
  • Logic flaws. These are the hardest to catch with tools because nothing is technically broken. A checkout flow that lets a user edit the discount field in the request and set it to 100 percent works exactly as coded. It’s just coded wrong.

The 7 Types of Security Testing and What Each One Catches

No single testing type covers all bugs. Here are seven types of security testing, along with what each one catches.

1. SAST: Static Application Security Testing

SAST tools analyze source code, bytecode, or binaries without running the application. They trace how data flows through the code and flag patterns that match known vulnerability classes, such as user input reaching a SQL query without sanitization.

What SAST catches: Injection flaws, hardcoded secrets, insecure cryptographic calls, and unsafe function use, all before the code is ever deployed.

Where SAST falls short: SAST cannot see runtime configuration, environment issues, or how components behave when connected. It also tends to produce false positives because it reasons about what code might do rather than observing what it actually does.

When to run SAST: In the Integrated Development Environment (IDE) and on every pull request (PR). This is the earliest possible point to catch a problem, which makes it the cheapest.

2. DAST: Dynamic Application Security Testing

DAST tools test the running application from the outside, the same way an attacker would. They crawl the app, send crafted requests, and analyze responses for signs of vulnerability. They have no access to source code.

What DAST catches: Server misconfigurations, missing security headers, authentication problems, and injection flaws that only appear when the full stack is running.

Where DAST falls short: DAST cannot tell you which line of code caused the problem, only that the problem exists. It also struggles with single-page apps and complex authentication flows unless configured carefully.

When to run DAST: Against a staging environment on a schedule or before release. It needs a deployed application to work.

3. IAST: Interactive Application Security Testing

IAST places an agent inside the running application and watches how code behaves as tests exercise it. It combines SAST’s visibility into code with DAST’s view of real runtime behavior.

What IAST catches: Vulnerabilities in code paths that your existing functional or integration tests actually reach, with precise line-level detail and far fewer false positives than SAST alone.

Where IAST falls short: IAST only sees the code that gets executed. If your test suite never touches a feature, IAST never looks at it. It also requires language-specific agents, so coverage depends on your stack.

When to run IAST: During QA and integration testing, where automated test suites already drive the application.

4. SCA: Software Composition Analysis

SCA scans your dependency manifest and lock files, identifies every third-party package and its version, and checks them against vulnerability databases. Many tools also flag license issues.

What SCA catches: Known CVEs in open-source libraries, outdated packages, and transitive dependencies you did not know you were pulling in.

Where SCA falls short: SCA only knows about disclosed vulnerabilities. A zero-day in a package you use will not show up until it is published. It also cannot tell you whether your application actually calls the vulnerable function.

When to run SCA: On every build. Dependency vulnerabilities are disclosed daily, so a clean scan last week means nothing today.

5. Penetration Testing

Penetration testing is a human-led attack simulation. A skilled tester, either internal or from a specialist firm, is given a scope and a time window and tries to compromise the application using the same techniques a real attacker would.

What penetration testing catches: Business logic flaws, chained vulnerabilities where several low-severity issues combine into a serious one, and anything that requires understanding what the application is for rather than just how it is built.

Where penetration testing falls short: It is expensive, point-in-time, and limited by the tester’s skill and the scope they were given. A pen test in March says nothing about code shipped in April.

When to run penetration testing: Before major releases, after significant architecture changes, and on a regular cadence (often annually) for compliance requirements.

6. API Security Testing

APIs are now the primary attack surface for most applications, and they fail differently from web UIs. There is no client-side validation to rely on, and object-level authorization flaws are easy to introduce and hard to spot in a UI walkthrough.

What API testing catches: Broken object-level authorization (one user accessing another user's resources by ID), excessive data exposure where endpoints return more fields than the client needs, missing rate limiting, and mass assignment flaws.

Where API testing falls short: Most API testing depends on having an accurate API specification. Undocumented or shadow endpoints are missed entirely.

When to run API testing: Alongside DAST and as part of API contract testing in the pipeline.

7. Vulnerability Scanning

Vulnerability scanning is the broadest and shallowest layer. Scanners check servers, containers, networks, and cloud configurations against databases of known weaknesses: unpatched software, open ports, default credentials, and insecure settings.

What vulnerability scanning catches: Infrastructure and configuration issues that sit underneath the application.

Where vulnerability scanning falls short: Scanners are signature-based. They find known issues and miss novel ones, and they do not understand your application logic at all.

When to run vulnerability scanning: Continuously against production infrastructure and on every container image before it ships.

The OWASP Top 10: Your Security Testing Starting Point

The Open Worldwide Application Security Project (OWASP) Top 10 is the most widely referenced list of web application security risks. It maps each category to specific Common Weakness Enumerations (CWEs), which makes it directly usable as a test planning checklist.

Here’s the OWASP Top 10 checklist:

  1. A01 Broken Access Control. A01 signals users accessing data or performing actions they should not. OWASP’s data shows an average of 3.73 percent of tested applications had at least one weakness in this category.
  2. A02 Security Misconfiguration. A02 refers to default settings, debug mode left on, open storage buckets, and missing security headers. 
  3. A03 Software Supply Chain Failures. A03 covers dependency confusion, malicious packages, and tampered build pipelines, not just outdated libraries. OWASP notes that it had the fewest occurrences in test data but the highest average exploit and impact scores.
  4. A04 Cryptographic Failures. A04 includes weak or missing encryption of sensitive data, both at rest and in transit.
  5. A05 Injection. A05 refers to SQL injection, command injection, and XSS. 
  6. A06 Insecure Design. A06 includes flaws baked into the architecture before a line of code is written. No amount of secure coding fixes a design that never considered threat modeling.
  7. A07 Authentication Failures. A07 refers to weak login, session handling, and identity management.
  8. A08 Software and Data Integrity Failures. A08 includes unverified updates, insecure deserialization, and CI/CD pipelines that trust code without verifying it.
  9. A09 Security Logging and Alerting Failures. A09 refers to problems where you were breached and never knew. Insufficient logging means incidents go undetected for months.
  10. A10 Mishandling of Exceptional Conditions. A10 refers to applications that fail open, leak stack traces, or behave unpredictably when they hit an edge case.

For a team starting security testing from scratch, the practical move is to map each category to the testing type that catches it. 

SAST and SCA cover A03, A04, A05, and A08. DAST and vulnerability scanning cover A02 and A07. API testing and penetration testing are your best bet for A01 and A06. A09 and A10 mostly come down to reviewing how the application logs and handles failure, which is closer to a design review than a scan.

Automated Security Testing: Shifting Left Without Slowing Down

Shifting left means running security checks as early in development as possible, when fixes are cheapest. In practice, that means wiring automated security testing into the pipeline so it runs without anyone having to remember to trigger it.

A workable pipeline in security testing QA automation layout looks like this:

Pre-commit and IDE: This happens on the developer’s local machine before they share their work. By running lightweight security checks here, developers can fix issues immediately, similar to how a spell-checker catches a typo while you are typing a sentence. This prevents bad code from ever leaving the developer’s laptop.

Pull Request (PR): A PR is the process of submitting code to be merged into the main project branch. At this stage, the team performs a deeper analysis. Because the code is about to become part of the shared application, running full security scans here acts as a gatekeeper, ensuring no new vulnerabilities are introduced into the core codebase.

Build: This is the automated assembly process where the code is compiled, packaged, and turned into a runnable application. Since this stage creates the actual artifacts (like container images) that will be deployed, it is the right time to check that those packages themselves and the infrastructure code defining how they run are secure.

Staging: This is an environment that mirrors the real, live environment as closely as possible. Since the application is actually running here, it allows for more sophisticated security testing that requires a live, functional stack, such as testing how the app behaves when an attacker sends it unexpected requests.

Production: This is the live, user-facing environment. Because this is the “real world,” security testing here focuses on continuous monitoring, constantly scanning the live infrastructure for new threats or configuration issues that might have appeared since the last deployment.

Security Testing Tools Worth Knowing in 2026

This list includes some of the most recommended tools for security testing in 2026, grouped by what they do.

SAST: Static Application Security Testing

Best tools for SAST are:

  • Semgrep: Fast, open-source, and ideal for custom pattern-based checks.
  • CodeQL: GitHub’s powerful semantic analysis engine; treats code as a database.
  • Checkmarx / Veracode: Established enterprise platforms offering broad coverage and reporting.

DAST (Dynamic Application Security Testing)

Best tools for DAST include:

  • ZAP: Highly popular, open-source scanner with strong automation capabilities.
  • Burp Suite: Industry standard for manual penetration testing, with automated scanning in the Professional version.

SCA (Software Composition Analysis)

Most recommended tools for SCA include:

  • Snyk: Developer-centric tool that integrates into workflows and can automate dependency fix requests.
  • Trivy: All-in-one scanner for containers, filesystems, and infrastructure-as-code.

IAST (Interactive Application Security Testing)

Expert-recommended tools for IAST include:

  • Contrast Security / Checkmarx IAST: These require installing a runtime agent within the application to monitor code behavior.

TestFiesta Brings Your Security Testing Evidence Into a Consolidated Room

The most common problem with security testing is not finding vulnerabilities. It is proving, at release time, that the ones that mattered got fixed and retested. 

Security findings tend to live in five different places: a SAST dashboard, a DAST report PDF, a pen test spreadsheet from the vendor, and retest evidence somewhere in Slack. When a stakeholder asks whether the release is safe to ship, nobody can answer from one screen.

TestFiesta gives security testing the same structure as every other test type, so the evidence lives alongside your functional and regression results instead of in a separate silo.

  • Security test cases live next to functional ones. Write test cases for each OWASP category, tag them by risk area, and group them into the same test runs and milestones your team already uses. Custom tags mean you can filter a run down to just the A01 access control checks or just the API authorization tests when someone asks.
  • Automated results feed in through the API. TestFiesta’s automation API accepts results from your pipeline, so automated and manual test outcomes sit in one consolidated view. Custom fields are built for mapping data from automated tests, so you can capture the details you need alongside each result.
  • Findings become tracked defects with full traceability. A failed security check becomes a defect linked to the exact test and execution that found it. Attach screenshots, logs, and files. Assign it to a developer, and when they push a fix, reassign it to QA for verification. The defect record shows the whole chain from discovery to retest.
  • Jira and GitHub stay in sync. For teams that track engineering work elsewhere, defects sync to Jira or GitHub issues with the test context attached, so developers see what failed and how to reproduce it without leaving their tracker.
  • Reporting covers security tests like everything else. Because security tests are tagged and tracked alongside functional ones, they appear in the same reports, without stitching together exports from five tools.

Don’t let critical security insights get lost across fragmented tools and separate dashboards.

Break down testing silos by bringing your results into a single, cohesive view.

Sign up for a free trial today

FAQs

Can automated security testing replace penetration testing?

No, automated security testing catches known vulnerability patterns quickly and repeatedly, which is exactly what you want in a pipeline. It does not catch business logic flaws, chained vulnerabilities, or anything that requires understanding what the application is for. Penetration testing covers that gap. 

How often should security testing be performed?

It depends on the testing type. SAST and SCA should run on every pull request or build, since new code and new CVEs arrive daily. DAST should run against staging on every deploy or at least weekly. Penetration testing is typically done before major releases and on an annual cadence for compliance, though high-risk applications warrant more frequent testing.

What’s the difference between SAST and DAST, and which one should I start with?

SAST analyzes source code without running it and finds issues early, with line-level detail but more false positives. DAST tests the running application from the outside and finds runtime and configuration issues, but cannot point to the line of code responsible. If you are starting from scratch, start with SAST plus SCA on pull requests. They are the cheapest to set up, run earliest, and cover the widest range of OWASP categories. Add DAST once you have a stable staging environment to point it at.

Testing guide
Best practices

Ready for a Platform that Works

The Way You Do?

Stop fighting your tools. Start shipping with confidence. TestFiesta adapts to your workflow, not the other way around.

Welcome to the fiesta!