Back to Blog
Testing guide
Best practices

What Is a CI/CD Pipeline: Definition, Stages, Failure Modes

Learn what a CI/CD pipeline is, how the eight stages work, common failure modes to avoid, and why automation is essential for scaling your software delivery.

Armish Shah
August 11, 2026
September 4, 2026
What Is a CI/CD Pipeline: Definition, Stages, Failure Modes

Testing guide

What Is a CI/CD Pipeline: Definition, Stages, Failure Modes

by:

Armish Shah

September 4, 2026

8

min

Share:

What Is a CI/CD Pipeline: Definition, Stages, Failure Modes | TestFiesta
On this page

Ready to take your testing to
the next level?

Sleek and intuitive workflows
Transparent pricing
Easy migration

Introduction

Software delivery shouldn’t feel like a high-stakes guessing game. Yet, for many teams, the journey from “code complete” to “production ready” is challenging and hinges on manual processes prone to human error and bottlenecked by outdated documentation. CI/CD pipeline automates this process with faster release cycles, earlier bug detection, and reduced human error. This guide strips away the jargon to explain what a CI/CD pipeline actually does, why it’s the only way to scale, and how you can audit your current setup.

What Is a CI/CD Pipeline

A CI/CD (Continuous Integration and Continuous Delivery/Deployment) pipeline is the automated sequence of steps that moves a code change from a developer’s side to running software in production. A CI/CD pipeline builds it, tests it, scans it, packages it, and deploys it automatically, on every change, in the same order, every time.

The CI, Continuous Integration, gives you confidence the change is safe: the code compiles, the tests pass, and security scans come back clean. The CD delivers the result, either to a state where it’s ready to deploy (Continuous Delivery) or all the way to production automatically (Continuous Deployment).

Continuous Integration vs. Continuous Delivery vs. Continuous Deployment

Although almost always used in combination with each other, all Continuous Integration, Continuous Delivery, and Continuous Deployment have different meanings. 

Continuous Integration (CI): In CI, every code change is automatically built and tested against the shared branch. The goal is fast feedback: if your change breaks something, you find out in minutes. The key practice is frequency. Small changes merged often beat large changes merged rarely, because small changes are easier to review, easier to revert, and far less likely to conflict with someone else’s work.

Continuous Delivery (CD): In Continuous Delivery, every change that passes CI is automatically packaged into an artifact that could go to production at any time. A human still decides when to push the button. The goal is keeping the codebase permanently deployable, so a release becomes a business decision instead of a technical event. For teams with compliance requirements or fixed release windows, this is usually the practical end state.

Continuous Deployment (CD): In Continuous Deployment, every change that passes the full pipeline ships to production automatically, with no human approval gate. The goal is eliminating release ceremonies entirely. This takes more than technical maturity. It requires high test confidence, strong observability, fast rollback, and organizational trust in the pipeline itself.

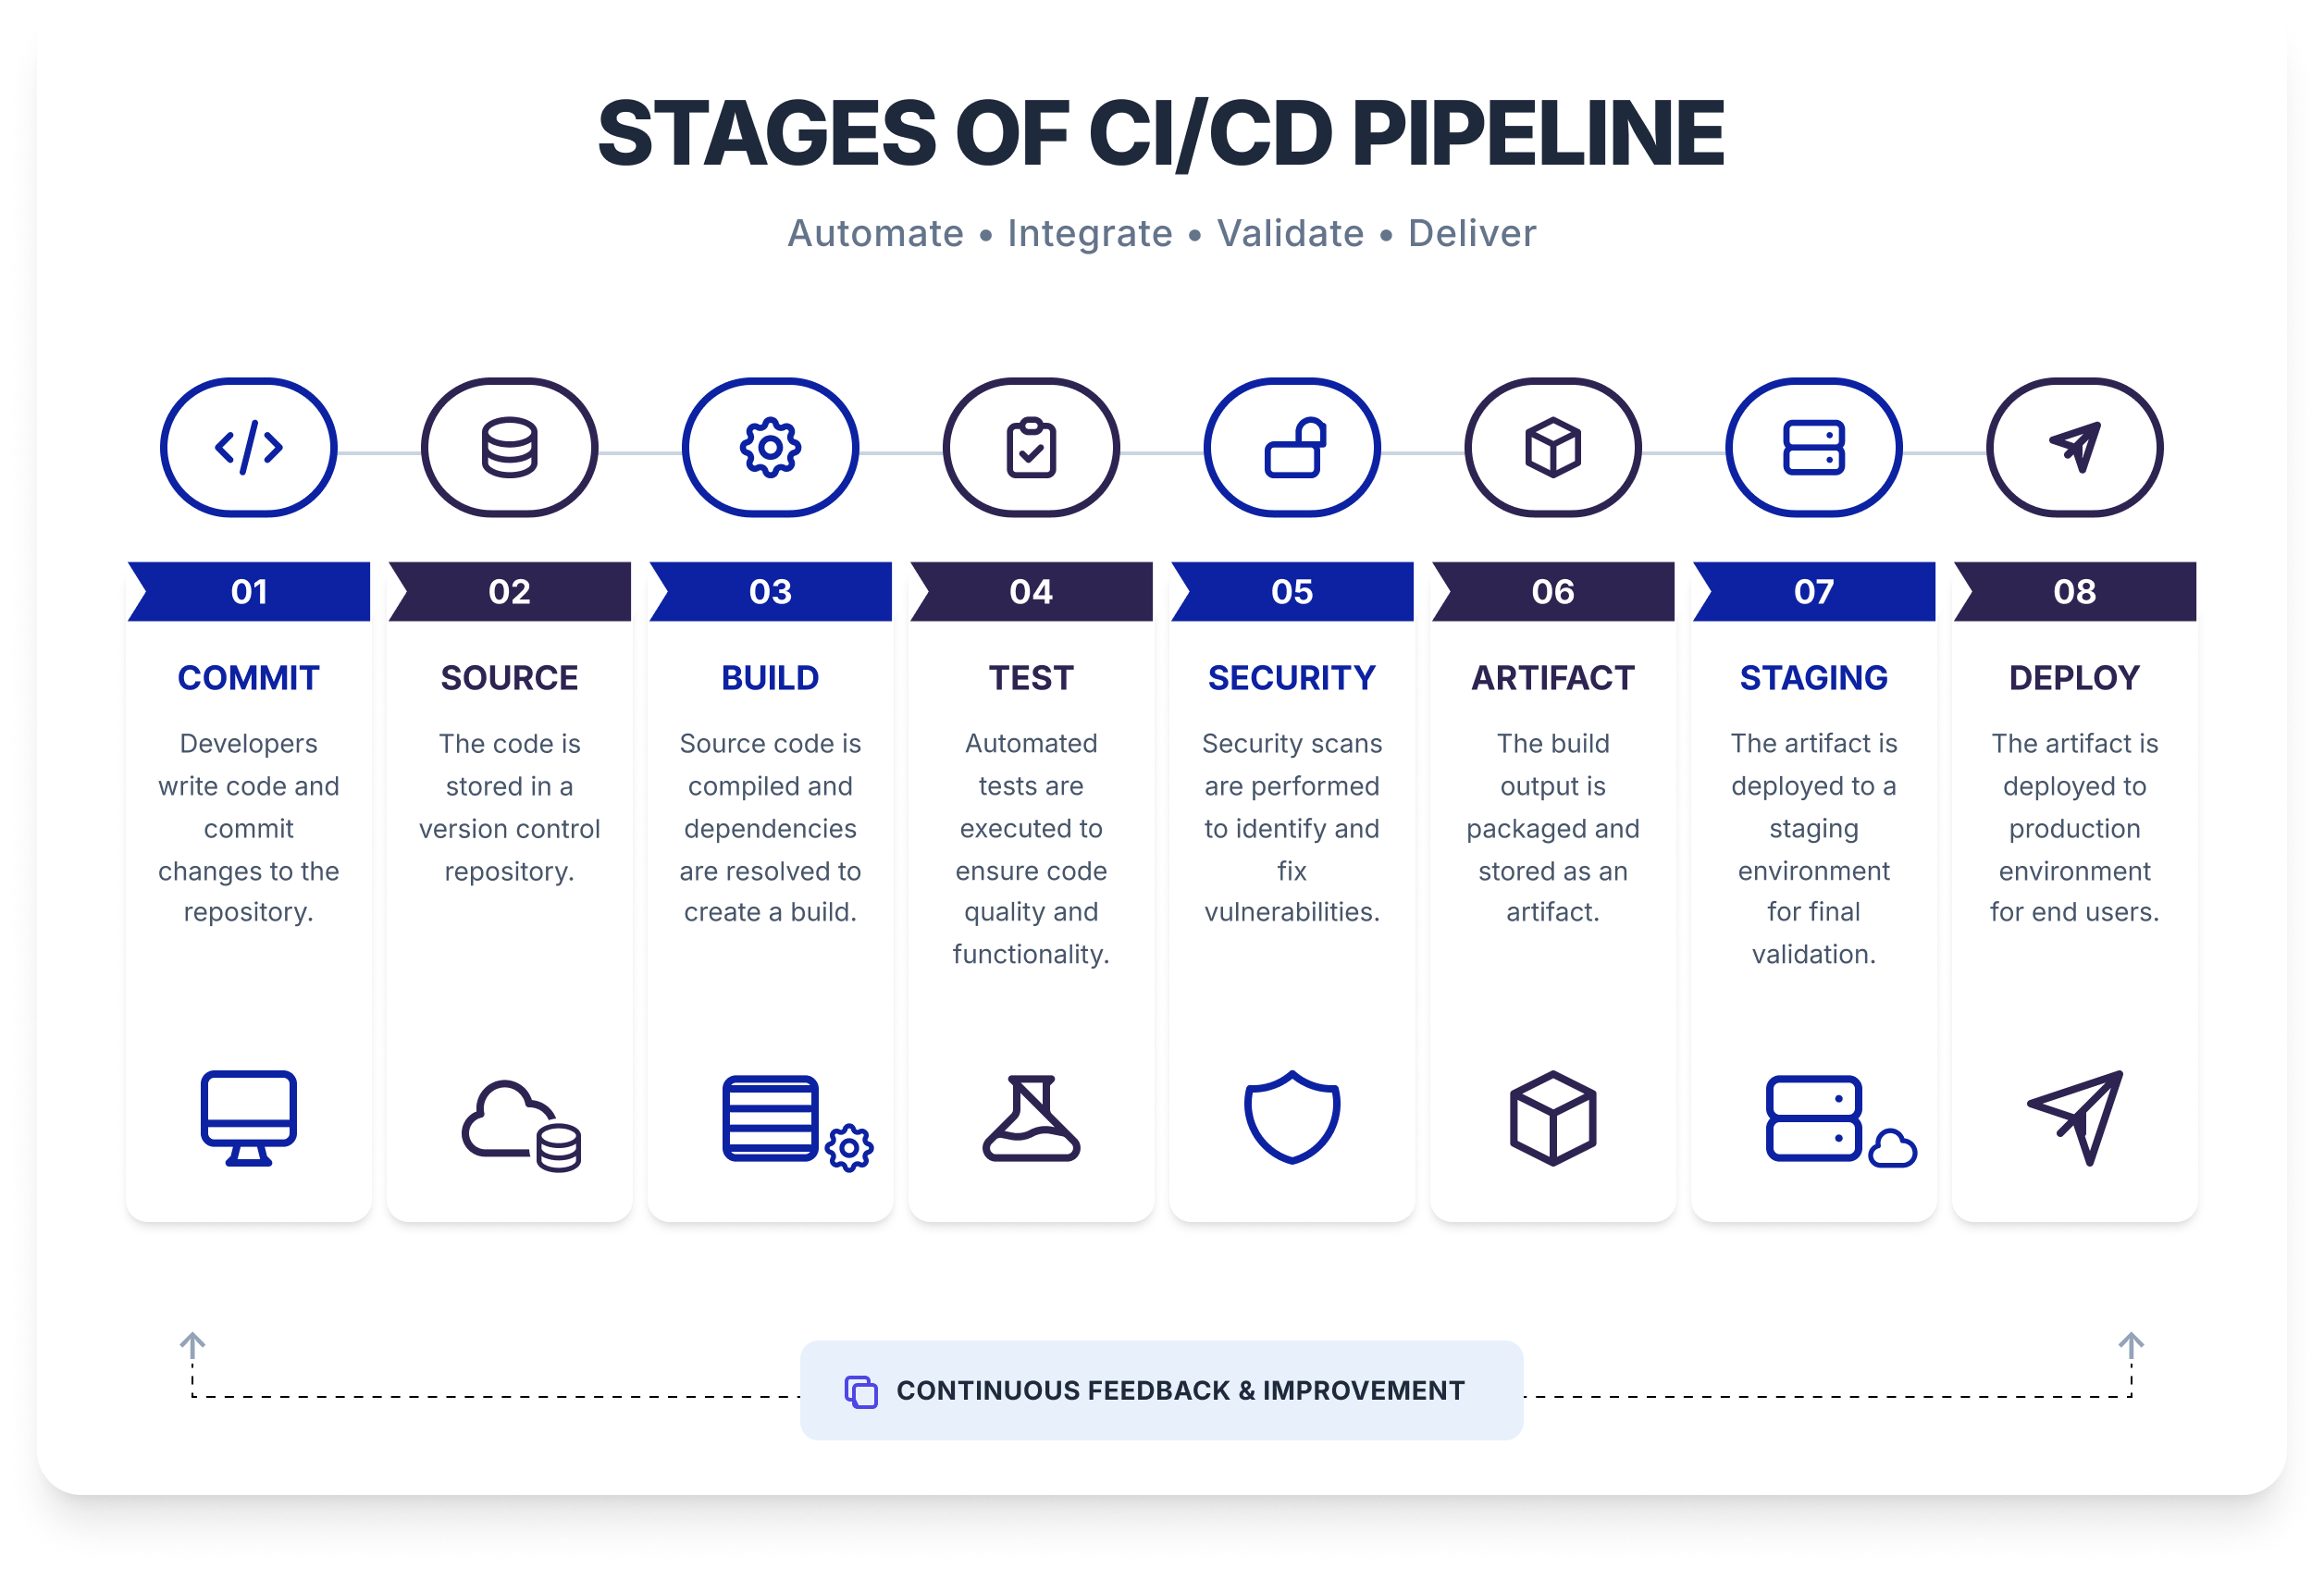
The 8 Stages of a CI/CD Pipeline

A pipeline is a quality gauntlet. Code has to survive every stage before it reaches production, and if any stage fails, the pipeline stops immediately, and the developer gets notified. 

Stage 1: Commit

The Commit stage is the beginning of the CI/CD lifecycle. It kicks off when developers push code from their local environments into a shared version control system, such as Git. During this phase, you can run pre-commit scripts, like linters, syntax checkers, or security scans, to identify basic issues before integration. 

Stage 2: Source

Everything starts at the source, be it a git push, a pull request, or a merge to main, which fires a webhook that kicks off the pipeline. The source stage checks out the code, validates branch rules, and sets up environment variables for everything downstream.

Stage 3: Build

In the build stage, the focus shifts to transforming source code into ready-to-use artifacts like binaries, libraries, or container images. This process handles code compilation, dependency resolution, and application packaging, such as creating .jar files for Java or building Docker images. Beyond assembly, the build phase verifies code quality by checking for syntax errors, maintaining consistent formatting, and scanning for security vulnerabilities in dependencies. 

Stage 4: Test

Tests run in order from fastest to slowest. Unit tests go first: milliseconds each, pure functions, no I/O. Integration tests come second, touching real databases, real queues, real HTTP. End-to-end tests run last, walking full user journeys through a testing pyramid. E2E tests are slow and expensive, which is exactly why they run at the end.

The fail-fast principle does the heavy lifting here. If 847 unit tests fail in 45 seconds, the 30-minute E2E suite never runs, and nobody’s time or compute gets wasted on a change that was already broken.

Stage 5: Security

Security means four checks: SAST (static code analysis) on every pull request, dependency scanning on every build, container image scanning before any environment promotion, and secrets scanning to catch a token someone accidentally committed. The economics are hard to argue with. A vulnerable dependency flagged in CI is a version bump and a re-run. The same vulnerability discovered after deployment means emergency patching, customer notification, and, depending on your industry, regulatory reporting.

Stage 6: Artifact

This stage involves packaging the verified, security-scanned output into an immutable artifact. Usually, that’s a container image tagged with the exact commit SHA, pushed to a central registry. From this point on, that same artifact gets promoted through staging and production without ever being rebuilt.

Stage 7: Staging

In this stage, developers deploy the artifact to a test environment that mirrors production as closely as you can manage, which is staging. Then run three kinds of checks: smoke tests confirming critical endpoints respond, acceptance tests covering 10 to 20 key user journeys, and a performance check against a baseline your team has defined, such as flagging any response time that drifts well past what production normally serves.

Stage 8: Production and Deployment 

In the last stage, the artifact moves from staging to production using a zero-downtime strategy. Rolling deployments update instances gradually. Blue/green runs two environments and switches traffic between them, which makes rollback nearly instant. Canary testing sends a small slice of traffic, often 1 to 5 percent, to the new version first, then expands in phases as the metrics hold.

CI/CD Pipeline Failure Modes to Watch Out for

CI/CD pipelines can degrade over time, that too silently. Here’s what to look out for:

  • Pipeline drift. Stages add tests. Tests add fixtures. Fixtures add I/O. Each individual change is small and defensible, but the aggregate effect over a year of normal product work is that pull request (PR) feedback time doubles. Without a metric on pipeline duration, the slowdown is invisible until CI starts taking forever. The fix: Track pipeline duration as a first-class metric alongside your DORA metrics, and alert when median PR check time crosses 10 minutes. 
  • Flaky test tolerance. A flaky test is a test that fails on one run and passes on another. It teaches engineers exactly one behavior: click “rerun.” Once that habit forms, real failures go through the rerun reflex first, and the pipeline’s signal degrades into noise. The fix is to detect flakes systematically and quarantine them out of required checks until they’re actually fixed. 
  • Configuration aging. Pipeline YAML ages badly. Versions get pinned, then drift, then break when something upstream changes. Security patches lag. Cache invalidation logic falls behind the build graph. None of this shows up as a failing pipeline today. It shows up as a 90-minute incident at critical times. The fix: Treat the pipeline file as production code. Review it, version it, monitor it. A pipeline config that hasn’t been reviewed in six months probably has a few silent problems in it right now.

TestFiesta Plugs the Gap Your Pipeline Leaves Open

A CI/CD pipeline automates the path from commit to production, but it only ever runs the tests that exist. It can’t tell you which critical paths have never been tested, which test cases are missing coverage, or whether the tests that are passing actually validate the right behavior.

That gap between tests passed and the right things being tested is exactly where TestFiesta lives. It’s the test management layer that gives your team visibility into what the pipeline is actually validating: structured test case management, coverage tracking across pipeline runs, and an audit trail that turns a green checkmark into a statement your team can stand behind.

Ready to bridge the gap between passing tests and actual quality?

Stop guessing if your pipeline is validating the right things. Get full visibility into your coverage with TestFiesta and build an audit trail you can stand behind.

Start Your Free Trial

FAQs

What’s the difference between a CI/CD pipeline and DevOps?

DevOps is the culture: development and operations working as one team with shared ownership of delivery. CI/CD is the technical implementation of one of its core practices, automating the path from commit to production. 

Which CI/CD tools should I use?

To pick the right CI/CD tool, start with where your code lives. GitHub Actions is the lowest-friction choice on GitHub, and GitLab CI/CD is the strongest all-in-one option on GitLab. Jenkins is highly configurable but carries real maintenance overhead, while CircleCI and Buildkite suit teams that need performance at scale. 

How long should a CI/CD pipeline take?

The duration of a CI/CD pipeline depends on the stage. PR checks (build, lint, unit tests) should finish in under 10 minutes, since anything slower forces engineers to switch contexts. Merge-time checks like integration tests and security scans can run up to 30 minutes, and staging deployment plus verification should stay under 15. For most web applications, merge to production should take under an hour end to end. 

‍

Tool

Pricing

TestFiesta

Free user accounts available; $10 per active user per month for teams

TestRail

Professional: $40 per seat per month

Enterprise: $76 per seat per month (billed annually)

Xray

Free trial; Standard: $10 per month for the first 10 users (price increases after 10 users)

Advanced: $12 per month for the first 10 users (price increases after 10 users)

Zephyr

Free trial; Standard: ~$10 per month for first 10 users (price increases after 10 users)

Advanced: ~$15 per month for the first 10 users (price increases after 10 users)

qTest

14‑day free trial; pricing requires demo & quote (no transparent pricing)

Qase

Free: $0/user/month (up to 3 users)

Startup: $24/user/month

Business: $30/user/month

Enterprise: custom pricing

TestMo

Team: $99/month for 10 users

Business: $329/month for 25 users

Enterprise: $549/month for 25 users

BrowserStack Test Management

Free plan available

Team: $149/month for 5 users

Team Pro: $249/month for 5 users

Team Ultimate: Contact sales

TestFLO

Annual subscription (specific amounts per user band), e.g., Up to 50 users: $1,186/yr; Up to 100 users: $2,767/yr; etc.

QA Touch

Free: $0 (very limited)

Startup: $5/user/month

Professional: $7/user/month

TestMonitor

Starter: $13/user/month

Professional: $20/user/month

Custom: custom pricing

Azure Test Plans

Pricing tied to Azure DevOps services (no specific rate given)

QMetry

14‑day free trial; custom quote pricing

PractiTest

Team: $54/user/month (minimum 5 users)

Corporate: custom pricing

Black Box Testing

White Box Testing

Coding Knowledge

No code knowledge needed

Requires understanding of code and internal structure

Focus

QA testers, end users, domain experts

Developers, technical testers

Performed By

High-level and strategic, outlining approach and objectives.

Detailed and specific, providing step-by-step instructions for execution.

Coverage

Functional coverage based on requirements

Code coverage

Defects type found

Functional issues, usability problems, interface defects

Logic errors, code inefficiencies, security vulnerabilities

Limitations

Cannot test internal logic or code paths

Time-consuming, requires technical expertise

Aspect

Test Plan

Test Case

Purpose

Defines the overall testing strategy, scope, and approach for a project or release.

Validates that a specific feature or functionality works as expected.

Scope

Covers the entire testing effort, including what will be tested, resources, timelines, and risks.

Focuses on a single scenario or functionality in the broader scope.

Level of Detail

High-level and strategic, outlining approach and objectives.

Detailed and specific, providing step-by-step instructions for execution.

Audience

Project managers, stakeholders, QA leads, and development teams.

QA testers and engineers.

When It's Created

Early in the project, before testing begins.

After the test plan is defined and the requirements are clear.

Content

Scope, objectives, strategy, resources, schedule, environment details, and risk management.

Test case ID, title, preconditions, test steps, expected results, and test data.

Frequency of Updates

Updated periodically as project scope or strategy changes.

Updated frequently as features change or bugs are fixed.

Outcome

Provides direction and clarifies what to test and how to approach it.

Produces pass or fail results that indicate whether specific functionality works correctly.

Tool

Key Highlights

Automation Support

Team Size

Pricing

Ideal For

TestFiesta

Flexible workflows, tags, custom fields, and AI copilot

Yes (integrations + API)

Small → Large

Free solo; $10/active user/mo

Flexible QA teams, budget‑friendly

TestRail

Structured test plans, strong analytics

Yes (wide integrations)

Mid → Large

~$40–$74/user/mo)

Medium/large QA teams

Xray

Jira‑native, manual/
automated/
BDD

Yes (CI/CD + Jira)

Small → Large

Starts ~$10/mo for 10 Jira users

Jira‑centric QA teams

Zephyr

Jira test execution & tracking

Yes

Small → Large

~$10/user/mo (Squad)

Agile Jira teams

qTest

Enterprise analytics, traceability

Yes (40+ integrations)

Mid → Large

Custom pricing

Large/distributed QA

Qase

Clean UI, automation integrations

Yes

Small → Mid

Free up to 3 users; ~$24/user/mo

Small–mid QA teams

TestMo

Unified manual + automated tests

Yes

Small → Mid

~$99/mo for 10 users

Agile cross‑functional QA

BrowserStack Test Management

AI test generation + reporting

Yes

Small → Enterprise

Free tier; starts ~$149/mo/5 users

Teams with automation + real device testing

TestFLO

Jira add‑on test planning

Yes (via Jira)

Mid → Large

Annual subscription starts at $1,100

Jira & enterprise teams

QA Touch

Built‑in bug tracking

Yes

Small → Mid

~$5–$7/user/mo

Budget-conscious teams

TestMonitor

Simple test/run management

Yes

Small → Mid

~$13–$20/user/mo

Basic QA teams

Azure Test Plans

Manual & exploratory testing

Yes (Azure DevOps)

Mid → Large

Depends on the Azure DevOps plan

Microsoft ecosystem teams

QMetry

Advanced traceability & compliance

Yes

Mid → Large

Not transparent (quote)

Large regulated QA

PractiTest

End‑to‑end traceability + dashboards

Yes

Mid → Large

~$54+/user/mo

Visibility & control focused QA

Related Articles

Introduction

Most engineering teams face the same issue at least once in their testing lifecycle: A test fails, testers rerun the pipeline, and the test passes. The test is the same, but it produces different results each time it is run. This is a kind of test that we call a flaky test. 

There’s no definite answer to why a flaky test failed in the first place and passed the second time. But if that happens enough times, your test suite becomes clerical work instead of actual QA.

The usual solution is to delete the test or leave a comment, but neither of these gives you any coverage that you may need later. A better solution is to quarantine a flaky test, with some conditions attached. In this guide, we’ll learn what it means to quarantine a flaky test and how to do it.

What Are Flaky Tests

Flaky tests are the kind of tests that produce different results each time they run without any changes in the code. They may pass or fail inconsistently, which gives testers no clue about what is broken, if anything. 

Flaky tests are a problem because they result in wasted time, wasted cost, and poor trust in releases—a flaky test can indicate that other tests that are actually failing might also be flaky, potentially resulting in inaccurate defect management. 

What It Means to Quarantine a Flaky Test

Quarantining a flaky test means isolating an unreliable flaky test from your primary test suite so that its failures do not block continuous integration or deployment pipelines. Usually, a failed test blocks your deployment pipelines, which means the bug must be resolved and test must be passed before you can continue the integration. However, a flaky test is different from a failed test, so it requires quarantine. 

Instead of outright deleting the test or ignoring its output, a quarantined test is moved to a separate, non-blocking execution lane, so the test keeps running but stops blocking deployment. When the test is quarantined, it can still run and appear in reporting similar to a normal test, but it doesn’t stop the integration.

Quarantine vs. Skip vs. Delete Tests

Quarantining a test is different from skipping or deleting it. 

When you skip or delete a test, you can’t run it, its result won’t be recorded, it cannot block merges, and it provides no data for diagnosis. 

However, when you quarantine a test, you can still run it, record its results, retain its coverage, and get the full data for diagnosis while continuing to merge. You can also remove a test from quarantine after the underlying problem is identified. 

When Should You Quarantine a Test

Every quarantined test is an unresolved problem in your application, so the bar of uarantining test should be based on real issues in the test. Quarantine a test when:

The results are non-deterministic: Quarantine the test if the code remains the same, but the results are different. If it fails consistently, it is a bug report, not a quarantine case.

It has a measurable failure rate: the failure rate between 1% and 5% is a common threshold.

It has actually blocked someone: A test that actually blocks a pull request is more urgent than a test that is not actively blocking anything.

It is not covering something critical: A test that is covering something critical like payment processing, authentication, or data integrity cannot be “saved for later.” You have to fix critical tests urgently. 

If your test suite has a lot of quarantined test cases (more than 2%), there might be a problem with your test architecture.

How to Quarantine Flaky Tests: A Step-by-Step Process

Here’s a step-by-step guide on how to quarantine a flaky test:

Step 1: Detect Flakiness Automatically

Manual flakiness detection does not scale. Here are two reliable ways to catch the flakiness automatically:

1. Repeat runs: Run the same test multiple times against the same commit. Playwright supports this with --repeat-each=5. Most test automation frameworks have an equivalent. Any test that produces mixed results across those runs is flaky by definition. 

2. Historical tracking: Record pass and fail results for every test across every run, then calculate failure rate per test over a rolling window. A test failing 3 out of 100 runs on the same branch is flaky, and you now have a number to point at.

Step 2: Split Your Suite Into Blocking and Non-Blocking Stages

Your test suite and deployment pipeline need two lanes:

1. The blocking stage contains everything that must pass before a merge. This is your required check set. It should be fast, stable, and absolutely trusted. If something in here fails, work stops.

2. The non-blocking stage runs the quarantined tests. It executes on the same commits, produces the same reports, and fails in its own lane without touching merge status. Give the non-blocking stage its own dashboard. Teams that route quarantine results into the same view as everything else tend to lose track of them.

Step 3: Tag or Manifest the Quarantined Tests

You need a machine-readable record of what is quarantined and why. Two approaches are good here:

1. Tagging in code: Add an annotation to the test itself, with structured metadata in the body. See the example below.

@quarantine(

  owner: "priya.n",

  reason: "intermittent timeout on checkout step, ~6% fail rate",

  ticket: "QA-1842",

  expires: "2026-10-15"

) 

As a result, the context lives next to the test, so anyone reading the file knows immediately. 

2. A manifest file: Keep a single file, YAML or JSON, listing every quarantined test with the same fields. Your test runner reads it and routes accordingly. You get one place to look, and you can quarantine without touching test code. 

Step 4: Assign an Owner and Open a Ticket

The owner is a person who is in charge of the test case. Assign the developer who owns the code under test, or who wrote the test, or who touched it last—the rule should be consistent.

Open a real ticket in the system your team actually uses, such as GitHub or any native defect tracker in your test management platform. The ticket should carry the failure rate, a link to a failing run, the suspected cause if anyone has a guess), and the expiry date.

Step 5: Set an Expiry and Enforce It

Every quarantine test entry should have a date. Two weeks is a reasonable default. Longer than a month can lead to delays, and the date should be enforced. Before the entry expires, you should either fix the test and graduate it back or renew the entry if you need more time. Renewals should be capped by a small number so the solution is prioritized.

What Is the Graveyard Anti-Pattern and How to Avoid It

The Graveyard Anti-Pattern occurs when flaky tests are moved into quarantine and then forgotten. Instead of serving as a temporary holding area while issues are resolved, the quarantine becomes a permanent resting place for neglected tests. Over time, test coverage silently degrades, and teams lose visibility into real failure signals.

How the Graveyard Anti-Pattern Develops

Common reasons behind the graveyard anti-pattern are:

1. Quick-fix mentality: Developers quarantine failing tests to unblock builds quickly without opening follow-up tracking tickets.

2. Lack of ownership: Quarantined tests lack assigned owners or clear expiration dates, leaving no one accountable for fixing them.

3. Out of sight, out of mind: Non-blocking execution results are ignored, hiding persistent failures and regressions until major outages occur.

How to Avoid the Graveyard Anti-Pattern

Here’s how to avoid the graveyard anti-pattern:

1. Enforce mandatory metadata: Require every quarantined test to specify an owner, an issue tracker ticket, a specific reason, and an expiration date.

2. Set strict quarantine limits: Cap the total number of quarantined tests (e.g., maximum 5% of the test suite). Require resolving existing quarantined tests before adding new ones once the cap is reached.

3. Automate expiration alerts: Trigger automated notifications or build warnings when a test exceeds its scheduled time in quarantine.

4. Conduct regular triage reviews: Review quarantined tests during weekly engineering syncs to ensure active investigation, graduation, or permanent deletion.

How to Graduate a Test Back Out of Quarantine

Getting a test out of quarantine should be as clearly defined as putting it in. Otherwise, tests either linger indefinitely or get rushed back into the main suite, only to start blocking builds and frustrating the team again.

To prevent premature graduation, establish a strict stability bar. A standard benchmark requires the test to pass 50 consecutive runs in the non-blocking execution lane without a single failure. For tests that were severely flaky, increase this threshold to 100 consecutive green runs before considering them stable.

Here’s how the sequence should go:

1. Fix the root cause, not the symptoms: Avoid quick fixes like adding retry wrappers or extending arbitrary sleep timeouts. Instead, replace static waits with dynamic, event-driven assertions, isolate test data using unique identifiers per test run, ensure proper setup and teardown of environment state, and mock or stub unstable external dependencies. Band-aid fixes merely conceal underlying instability, guaranteeing the test will flake again.

2. Let the fix soak in CI: Keep the test in the non-blocking quarantined lane while it accumulates test runs across various branches and builds. For example, if your CI pipeline executes 20 times per day, completing a 50-run stability requirement will take roughly two to three days. Resist the urge to shortcut this phase by running the test locally in a loop, as local environments rarely replicate the concurrency and network conditions of CI runners.

3. Verify stability against metrics: Review actual build history logs and telemetry rather than relying on gut feeling or memory to confirm that the stability threshold has been reached without intermittent failures.

4. Promote back to the blocking suite: Remove the test from the quarantine manifest or delete its code annotation, close the tracking ticket, and restore the test to the primary blocking stage where failures halt deployment pipelines.

5. Monitor closely post-graduation: Track the test’s performance during its first week back in the blocking suite. If it fails due to flakiness again, return it immediately to quarantine and mark it for rewrite or deletion, as failing multiple graduation attempts indicates fundamental design flaws.

A pro tip: Continuously track two key performance indicators: median quarantine duration and overall graduation rate. If median duration rises, expiration policies are not being enforced effectively. If the graduation rate drops below 50%, it indicates that most quarantined tests should be deleted rather than repaired, saving valuable engineering overhead.

TestFiesta Turns Flaky Test Chaos Into a Queue You Can Actually Clear

Managing flaky tests effectively requires robust tracking and accountability. TestFiesta simplifies this workflow by serving as a centralized platform for test results, historical metrics, ownership, and quarantine statuses.

Here is how TestFiesta streamlines flaky test management from detection to graduation:

  • Automated Tracking & Flakiness Trends: Instead of parsing complex CI logs, TestFiesta automatically gathers failure rates over time and highlights flakiness trends across your runs.
  • Clear Ownership & Expiration Tracking: Quarantined tests are assigned directly to owners and linked with strict expiration deadlines, preventing them from being forgotten in config files.
  • Data-Driven Graduation: When a test is ready to return to the blocking suite, TestFiesta provides verified run history to confirm stability before graduation.

Ready to Take Control of Your Flaky Tests?

Stop letting unreliable tests slow down your deployment pipeline and drain team productivity.

Start your free trial today

FAQs

Does quarantining a test slow down my CI pipeline?

Yes, quarantining a test can slightly slow down your CI pipeline because quarantined tests still run. The delay is usually brief because the non-blocking stage runs in parallel with everything else. 

Can I automate the quarantine process entirely?

Not entirely, but you can automate the quarantine process largely. Detection, routing, and expiry reminders can all be automated. But the decision to quarantine a test and the assignment of an owner should stay manual. 

What if a quarantined test is actually catching a real bug?

Quarantine tests can sometimes actually catch a real bug, and it’s the main risk of quarantining a test. Before quarantining, check whether the failure correlates with specific code changes rather than appearing at random. If the failure rate jumps after a deploy, treat it as a regression first and investigate before routing it to quarantine.
Testing guide
Best practices

Introduction

Imagine this scenario: your web application passes every test, survives staging without a hitch, and gets deployed with complete confidence. Then, within minutes of launching, bug reports start pouring in. A core feature, like submitting a form or completing checkout, is completely broken. The culprit? An oversight as simple as not testing on Safari because your entire team uses Chrome.

This common pitfall highlights why cross-browser testing is essential. Different web browsers don’t interpret code identically, and these discrepancies often surface where they hurt most, in forms, navigation, payments, and layout structures.

Whether you’re launching a new product or maintaining a growing web application, ensuring a seamless experience across all major browsers and devices is crucial for user retention and brand credibility.

This guide covers what cross-browser testing is, how it differs from cross-device testing, how to do it manually, how to automate it, and which tools are worth your time.

What Is Cross-Browser Testing

Cross-browser testing is the practice of checking that a website or web app looks and works as intended across different browsers, browser versions, and operating systems. Cross-browser testing matters because every browser relies on an engine to turn HTML, CSS, and JavaScript into what you see on screen. There are three major engines powering browsers today: Blink, WebKit, and Gecko. Each engine implements web standards on its own schedule and with its own quirks. A CSS property that renders perfectly in Blink (that powers Chrome) can behave differently in WebKit (that powers Safari). A JavaScript API that Chrome shipped months ago might not exist yet in the Safari version your customers are running.

Cross-Browser Testing vs. Cross-Device Testing

Cross-browser testing and cross-device testing are often paired together during QA. While cross-browser testing focuses on the browser, browser versions, and browser engines that render your app, cross-device testing focuses on the hardware your app runs on. It checks how your app behaves on different phones, tablets, laptops, and desktops, each with its own screen size, resolution, input method, operating system version, and processing power. 

The overlap between cross-browser testing and cross-device testing is where most real bugs live. Safari on an iPhone and Safari on a MacBook share the same engine, yet one uses touch, a small viewport, and mobile hardware while the other uses a mouse and a large screen. That's why most teams run cross browser and cross device testing together. Your users don’t experience a browser or a device in isolation. They experience a combination of both.

What Does Cross-Browser Testing Check

Cross-browser testing checks the following areas:

  • Layout and rendering: Layout and rendering includes alignment, spacing, fonts, images, and whether elements overflow or overlap.
  • Core functionality: Core functionality includes forms, buttons, navigation, search, login, and payment flows working end to end.
  • CSS and JavaScript support: CSS and JavaScript support includes features your code depends on actually being available in each browser version. If the code features are not available, the code will not be successful. 
  • Responsive behavior: Responsive behavior ensures pages adapt correctly across viewport sizes and orientations.
  • Input handling: Input handling checks hovering on desktop, touch gestures on mobile, and keyboard navigation.
  • Media: Media verification includes video, audio, and animations playing and displaying as expected.
  • Accessibility: Accessibility includes screen reader behavior and focus handling, which can vary between browser and assistive technology pairings.

How to Do Cross-Browser Testing Manually

Cross-browser testing can and should be automated, but manual testing is the practical choice for new features where the UI is still changing week to week. Here’s how to do cross-browser testing manually:

Step 1: Build Your Browser Testing Matrix

A testing matrix defines exactly which combinations you’ll test. Without a good matrix, coverage depends on whichever browsers testers happen to have open. A B2B dashboard used mostly on company laptops will have a very different browser mix than a consumer shopping app used mostly on phones.

Each row in your matrix should specify the browser, browser version, operating system, and device or viewport. Then assign priority tiers so effort matches risk.

Whatever your analytics say, make sure the matrix covers all three mainstream engines (Blink, WebKit, and Gecko) at least once. Many teams also decide on a version policy up front, such as covering the current and previous major versions of each evergreen browser, so nobody has to debate it every sprint.

Step 2: Set Up Your Test Environments

A test environment is a controlled, isolated setup that mimics real-world conditions to run software tests safely before a product goes live to end-users. You have a few ways to get access to the browsers in your matrix:

  • Local installs: Local installs are fine for Chrome, Edge, and Firefox. Safari only runs on Apple platforms, so you’ll need a Mac for desktop Safari.
  • Virtual machines: Virtual machines are useful for testing different operating systems from one workstation.
  • Emulators and simulators: Emulators and simulators are good for quick layout checks on mobile viewports, but they don’t fully reproduce real hardware, touch behavior, or performance.
  • Real devices: Real devices are the most accurate option for mobile, and the most expensive to maintain in-house.
  • Cloud testing platforms: Cloud testing platforms give remote access to large pools of real browsers and devices without owning any of them.

Whichever mix you choose, keep the environment itself consistent. Test against a staging build that matches production, use stable test data, and clear cache and cookies between sessions so results from one browser don’t leak into the next.

Step 3: Execute Functional and Visual Checks

Run the same set of test cases in every configuration in your matrix. Start with your critical user journeys, such as signup, login, checkout, and core feature workflows, before moving to secondary pages.

For each configuration, work through three layers:

  1. Functional checks: Does every step complete? Do form validations fire? Do error messages appear? Does data save correctly?
  2. Visual checks: Is anything misaligned, clipped, or overlapping? Do fonts and icons load? Does the page look right at different window sizes?
  3. Interaction checks: Do hover menus have a touch equivalent on mobile? Can you tab through the page with a keyboard? Does rotating a device break the layout?

Browser developer tools help a lot here. The console surfaces JavaScript errors that aren’t visible on the page, and the network panel shows failed requests that might only happen in one browser.

Pro tip: Don’t write separate test cases for each browser. Write each test case once and run it against every configuration. Duplicated test cases drift apart over time, and soon you’re maintaining five slightly different versions of the same checkout test.

Step 4: Log, Debug, and Retest

A cross-browser bug report is only useful if a developer can reproduce it. Every report should include:

  • Browser name and exact version
  • Operating system and version
  • Device model or viewport size
  • Steps to reproduce
  • Expected result vs. actual result
  • Screenshots, screen recordings, and console errors

Before logging, check whether the bug appears in other browsers too. If it shows up everywhere, it’s a general defect. If it appears only in Safari, or only in browsers on one engine, that narrows the cause significantly and speeds up the fix.

After the fix ships, retest in the configuration where the bug appeared. Then run a quick regression test on the other browsers in your matrix, because a CSS fix for one engine can easily break the layout in another.

How to Automate Cross-Browser Testing

Cross-browser testing is doable manually, but twenty test cases across five browser configurations means 100 executions per release, and the matrix only grows as you add devices and versions.

Automated cross-browser testing solves the repetition problem. The same script runs against every browser in your matrix, often in parallel, and reports back in minutes. The best candidates for automation are stable, repetitive, high-value flows, including login, checkout, form submissions, and anything you retest on every release. Exploratory testing and visual judgment calls still belong to humans.

If you want to automate cross-browser testing without creating a maintenance headache, it comes down to two decisions: which framework you use and how you schedule your runs.

Step 1: Choose the Right Automation Framework

Four open-source test automation frameworks cover most automated cross-browser testing needs.

1. Selenium is the longest-standing option. It implements the W3C WebDriver standard, works with Chrome, Firefox, Safari, and Edge, and supports multiple languages including Java, Python, C#, JavaScript, and Ruby. 

2. Playwright drives Chromium, Firefox, and WebKit through a single API, and it can also run tests on branded Chrome and Edge. It supports emulated mobile and tablet devices and is available for JavaScript and TypeScript, Python, .NET, and Java. 

3. Cypress is popular with JavaScript teams for its developer experience and interactive test runner. It supports Chrome-family browsers (including Edge) and Firefox, with WebKit support still marked as experimental. 

4. Appium handles the mobile side. It automates native, hybrid, and mobile web apps, including Safari on iOS and Chrome on Android, which makes it the usual pick when your automation needs to reach real mobile browsers.

When choosing, weigh the programming languages your team already uses, the browsers your matrix requires, how the framework fits into your CI pipeline, and how much setup your team can realistically maintain.

Step 2: Run Tests in a Tiered Strategy

Running your full suite on every browser for every commit sounds thorough, but it slows feedback to a crawl. A tiered approach keeps pipelines fast while still catching browser-specific bugs before release:

  • On every pull request: Run a fast smoke suite on a single browser, typically headless Chromium. The goal is quick feedback, not full coverage.
  • On merge to main or nightly: Run the full regression suite across all three engines: Chromium, Firefox, and WebKit.
  • Before release: Run the complete matrix, including real mobile devices through a cloud platform, and pair it with a manual exploratory pass on your Tier 1 browsers.

Pro tip: First, run tests in parallel wherever your framework and infrastructure allow it, since sequential runs across many browsers get slow fast. Second, deal with flaky tests immediately. A test that fails randomly in Firefox trains the team to ignore Firefox failures, and that’s how real bugs slip through.

Cross-Browser Testing Tools Worth Knowing

Cross-browser testing tools fall into two groups that work together: Frameworks that write and run your tests, and cloud platforms that provide the browsers and devices to run them on.

Open-Source Cross-Browser Testing Tools

Selenium, Playwright, Cypress, and Appium are the core open-source options. They’re free to use, backed by large communities, and give you full control over your test code. 

Cloud Cross-Device Testing Tools

Cloud platforms remove the infrastructure burden. Instead of maintaining a device lab, you point your existing tests at a remote grid.

  • BrowserStack offers manual cross-browser testing through Live, browser automation through Automate, and real device testing through App Live and App Automate, plus Percy for visual testing. 
  • Sauce Labs combines a virtual device cloud, which it says covers more than 3,000 browser and OS combinations, with a real device cloud of physical iOS and Android devices. 
  • TestMu AI has cross-browser testing, a real device cloud, and automation capabilities, along with AI agents for test authoring and orchestration.

Manage Your Cross-Browser Test Coverage in One Place With TestFiesta

Cross-browser testing tools tell you if the test passes on a particular browser, but they don’t tell you exactly how many test cases you’ve run on Safari this cycle, whether what failed on Firefox is still open, and if anyone tested the checkout on Android.

Those answers usually live in a spreadsheet that keeps falling out of date with every new test. TestFiesta gives your test case a proper home and your team proper traceability.

Test Once, Run Across Every Configuration: TestFiesta’s Configurations let you define a test case once and execute it across multiple browsers, devices, and environments without duplicating it. When a test changes, you update it in one place, and results stay organized by environment so you can see exactly what passed where.

Reuse Instead of Rewriting: Shared steps and templates cut the repetitive work of building out a large test suite, which matters when the same login steps appear in dozens of test cases.

Track Bugs Where You Find Them: Built-in bug tracking ties every bug to the exact test and execution that found it. Attach the screenshots, logs, and browser details a developer needs, and assign defects without switching tools. If your team lives in Jira or GitHub, TestFiesta integrates with both.

See Manual and Automated Results Together: TestFiesta’s automation API lets you feed results from your automated runs into the platform, giving you a single view of manual and automated outcomes across your whole browser matrix.

Pricing That Doesn’t Punish Coverage: TestFiesta offers an Organization plan at $10/user/month with every feature included and billing based on active users. There’s a 14-day free trial with no credit card required.

Don’t let undetected browser bugs affect your user experience.

Take control of your testing matrix and keep test results unified in one powerful dashboard with TestFiesta.

Start your free trial today

FAQs

Does Cross-Browser Testing Include Mobile Browsers?

Yes, cross-browser testing also includes mobile browsers like Safari on iOS, Chrome on Android, and Samsung Internet, so they should be part of your testing matrix, especially if a large share of your traffic comes from phones. 

What’s the Difference Between Cross-Browser Testing and Compatibility Testing?

Compatibility testing is the broader practice of checking that software works across different operating systems, hardware, networks, and software environments. Cross-browser testing is one part of compatibility testing that focuses specifically on browsers, browser versions, and rendering engines. 

How Many Browsers Should I Test My Website On?

There’s no universal number of browsers that you should test your website on. Start with your own analytics and cover the browsers that make up most of your traffic. Major ones include Chrome, Safari, FireFox, and Brave.

Testing guide

Introduction

Testing as the last checkpoint is one of the most common practices in the traditional development processes. After a long sprint, testing usually takes a back seat and is pushed to the end, which results in poor, urgent testing and delayed regression cycles. 

Shift-left testing is a philosophy that focuses on improving testing and including it in the process from the get-go. In this guide, we’ll cover shift-left testing in detail, along with its four variants, how it fits into your sprint, which tools you need, and which mistakes to avoid. 

What Is Shift Left Testing

Shift-left testing refers to starting the testing activities as early as possible in the software development lifecycle rather than saving them for the end. The name “shift-left” comes from how development timelines are drawn. 

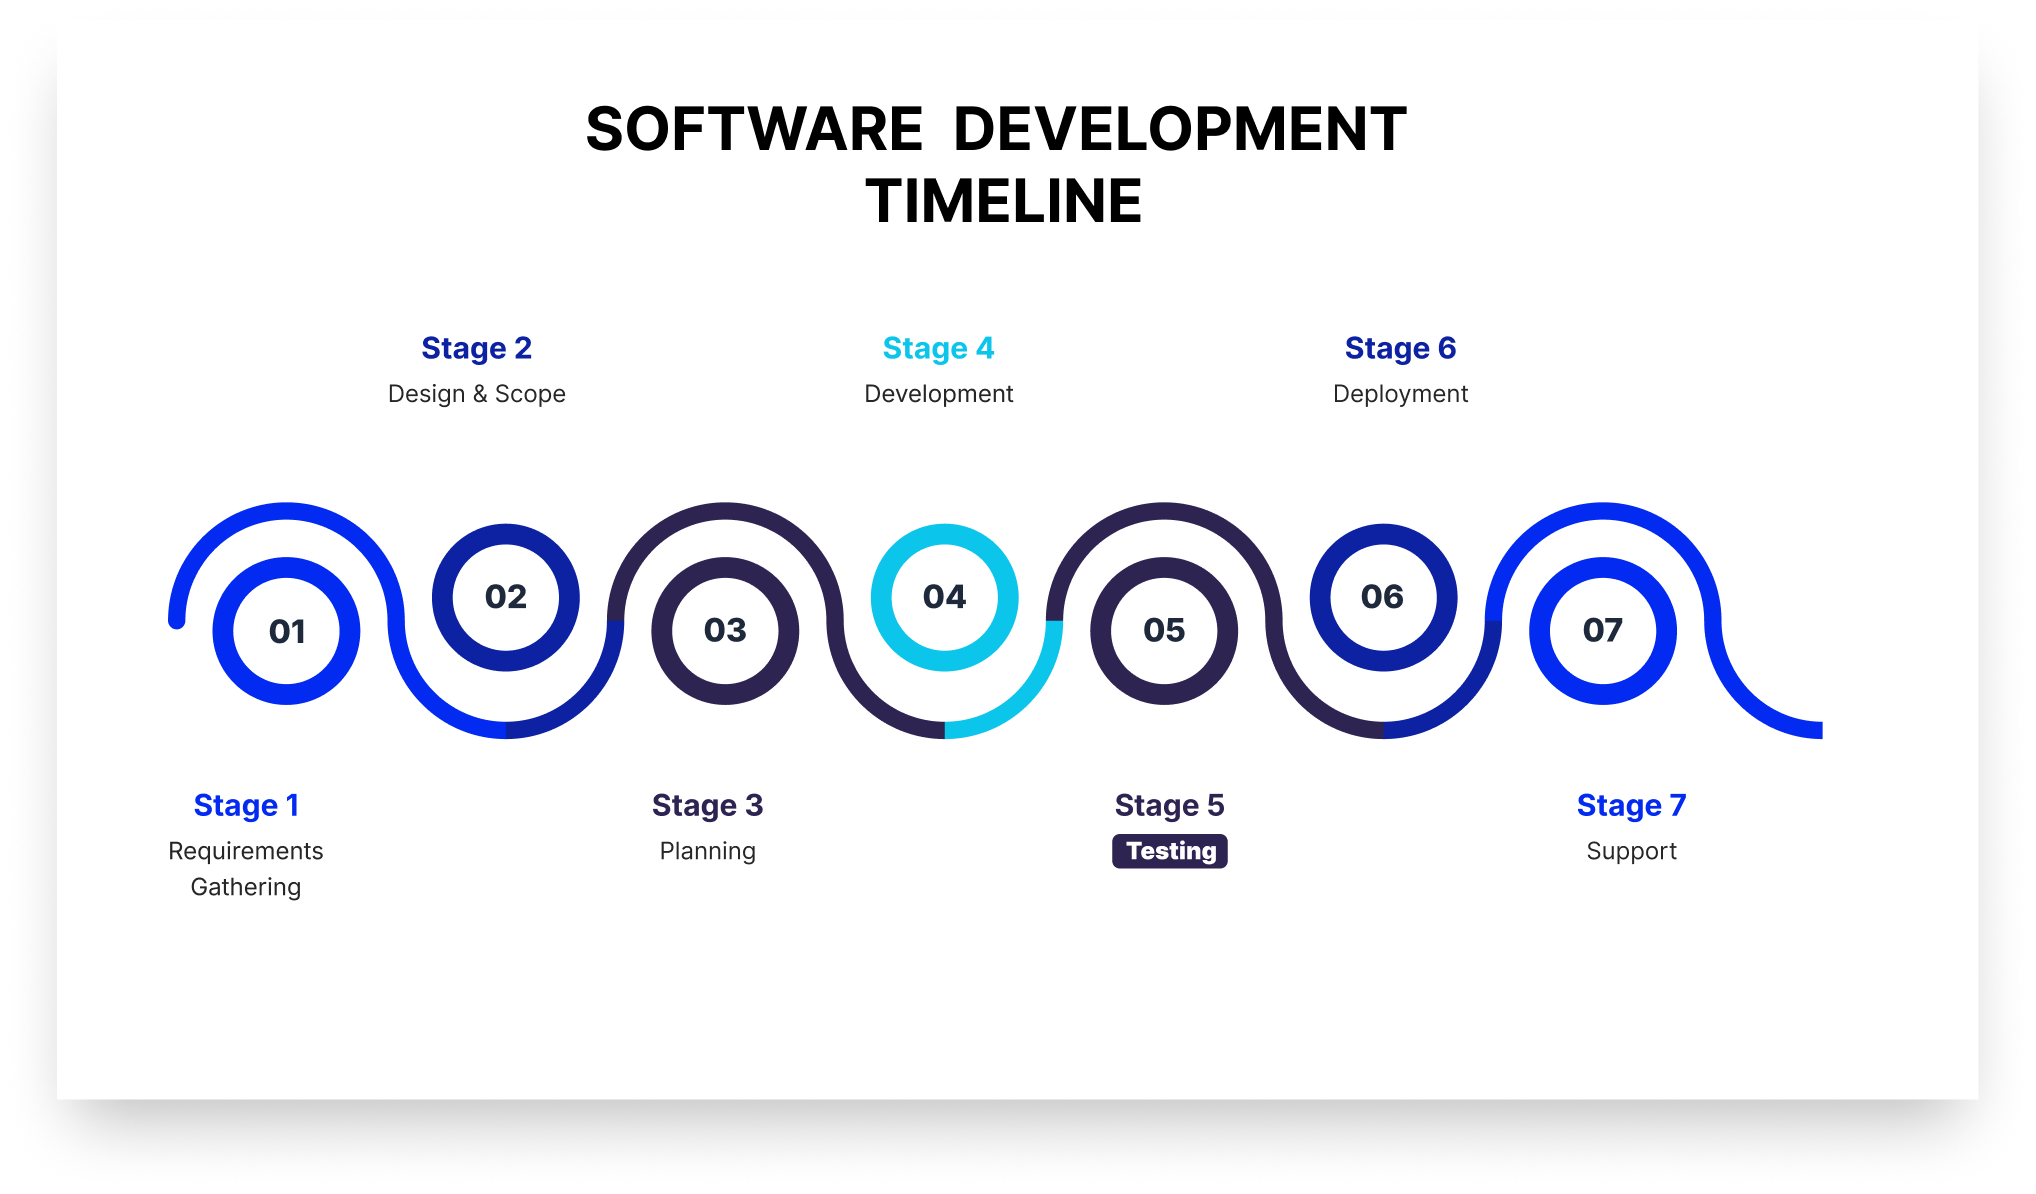
In the development chart, requirements sit on the left, production on the right, and testing has traditionally lived near the right edge (as visible in the picture below).

The software development timeline chart or the software development life cycle.

 “Shifting left” moves testing toward the beginning of that line, so it runs simultaneously with the other stages of the development process. 

A core benefit of shift-left testing is covers activities that prevent defects from being written at all. It reviews requirements for testability and defines acceptance criteria before a test is written. As a result, a defect caught in a requirements review never becomes code, saving time for developers. 

How Shift Left Testing Is Different From Traditional Testing

The difference between traditional testing and shift-left testing is not just about the tools you're using. It's more about how and when the QA will be involved in the product development. The table below shows the difference between shift-left testing and traditional testing in various aspects.

Traditional testing Shift left testing
When testing starts After development completes At requirements and design
Who owns quality The QA team Developers, QA, and security together
Feedback loop Days to weeks Minutes to hours
What triggers a test run A release candidate or handoff A commit or pull request
Defect discovery point Test phase or production Design, commit, or PR review
QA's primary role Finding defects Preventing them, plus deep exploratory work

The 4 Types of Shift Left Testing

Here are four common variants or types of shift-left testing that most agile teams follow:

1. Traditional Shift Left

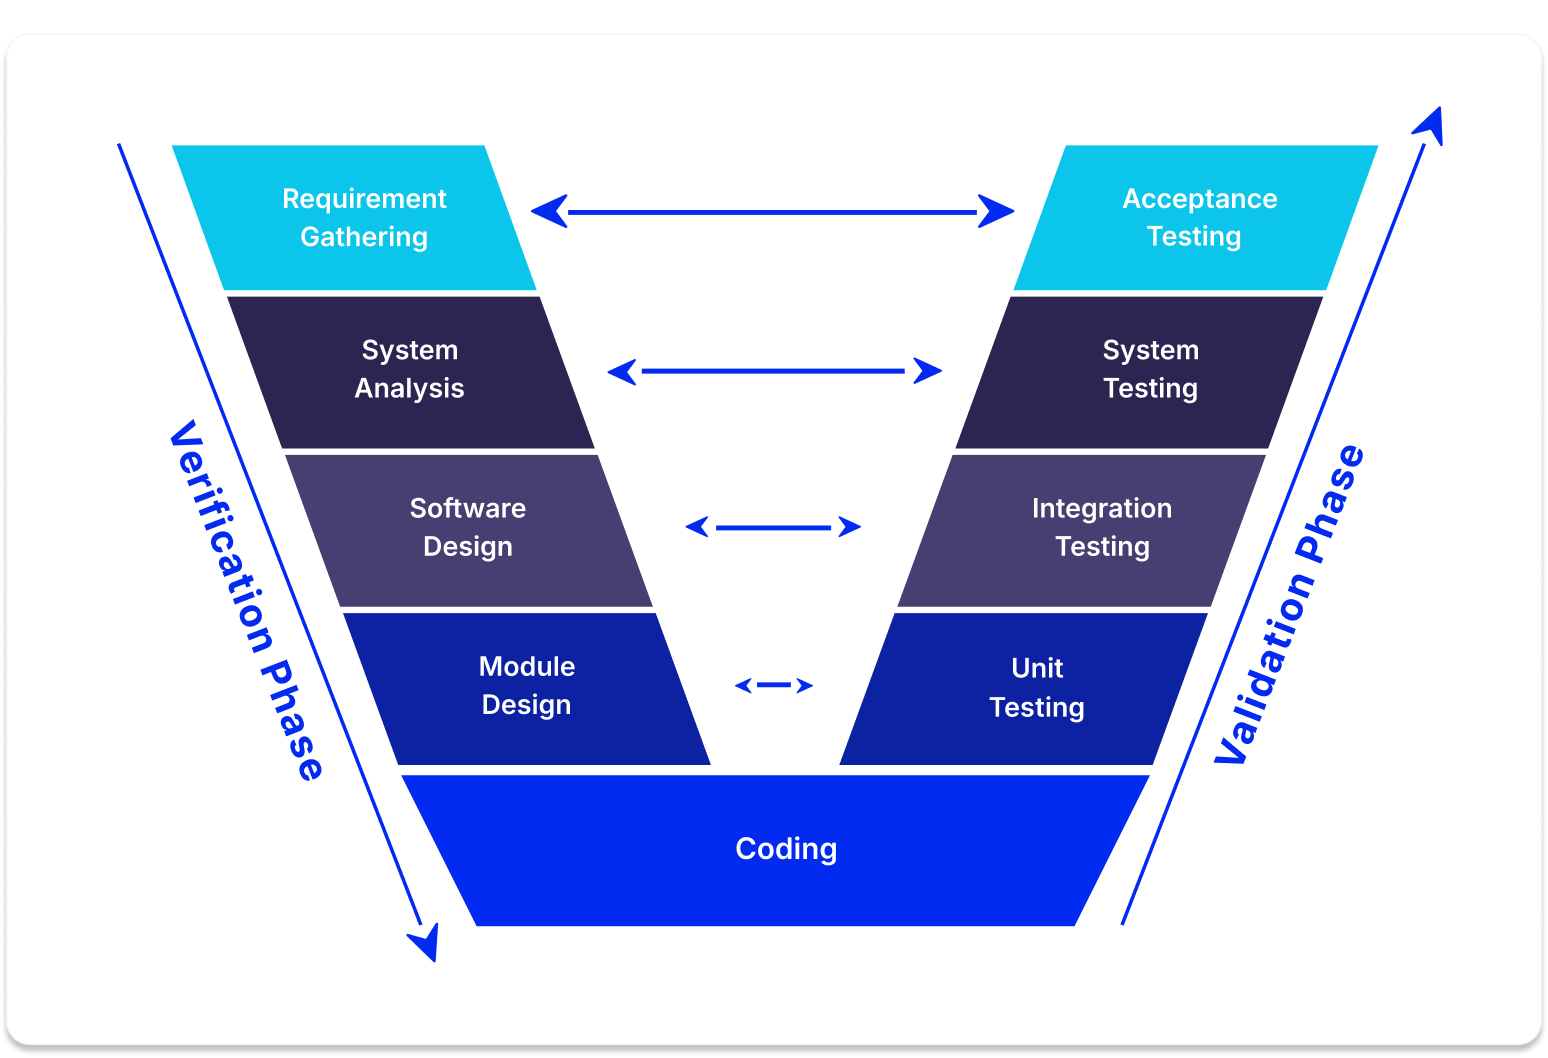
Traditional shift-left testing moves testing down and slightly left on the V model (see the image below). 

The V model in software testing

The V-Model is a step-by-step blueprint for building and testing software where every single development phase has a matching testing phase. It gets its name because the process bends upward after the coding stage, making the shape of the letter V.

It’s the type most people visualize when they talk about shift-left testing. For instance, if your team performs unit tests and integration tests early on, you’re doing traditional shift-left testing. 

2. Incremental Shift Left

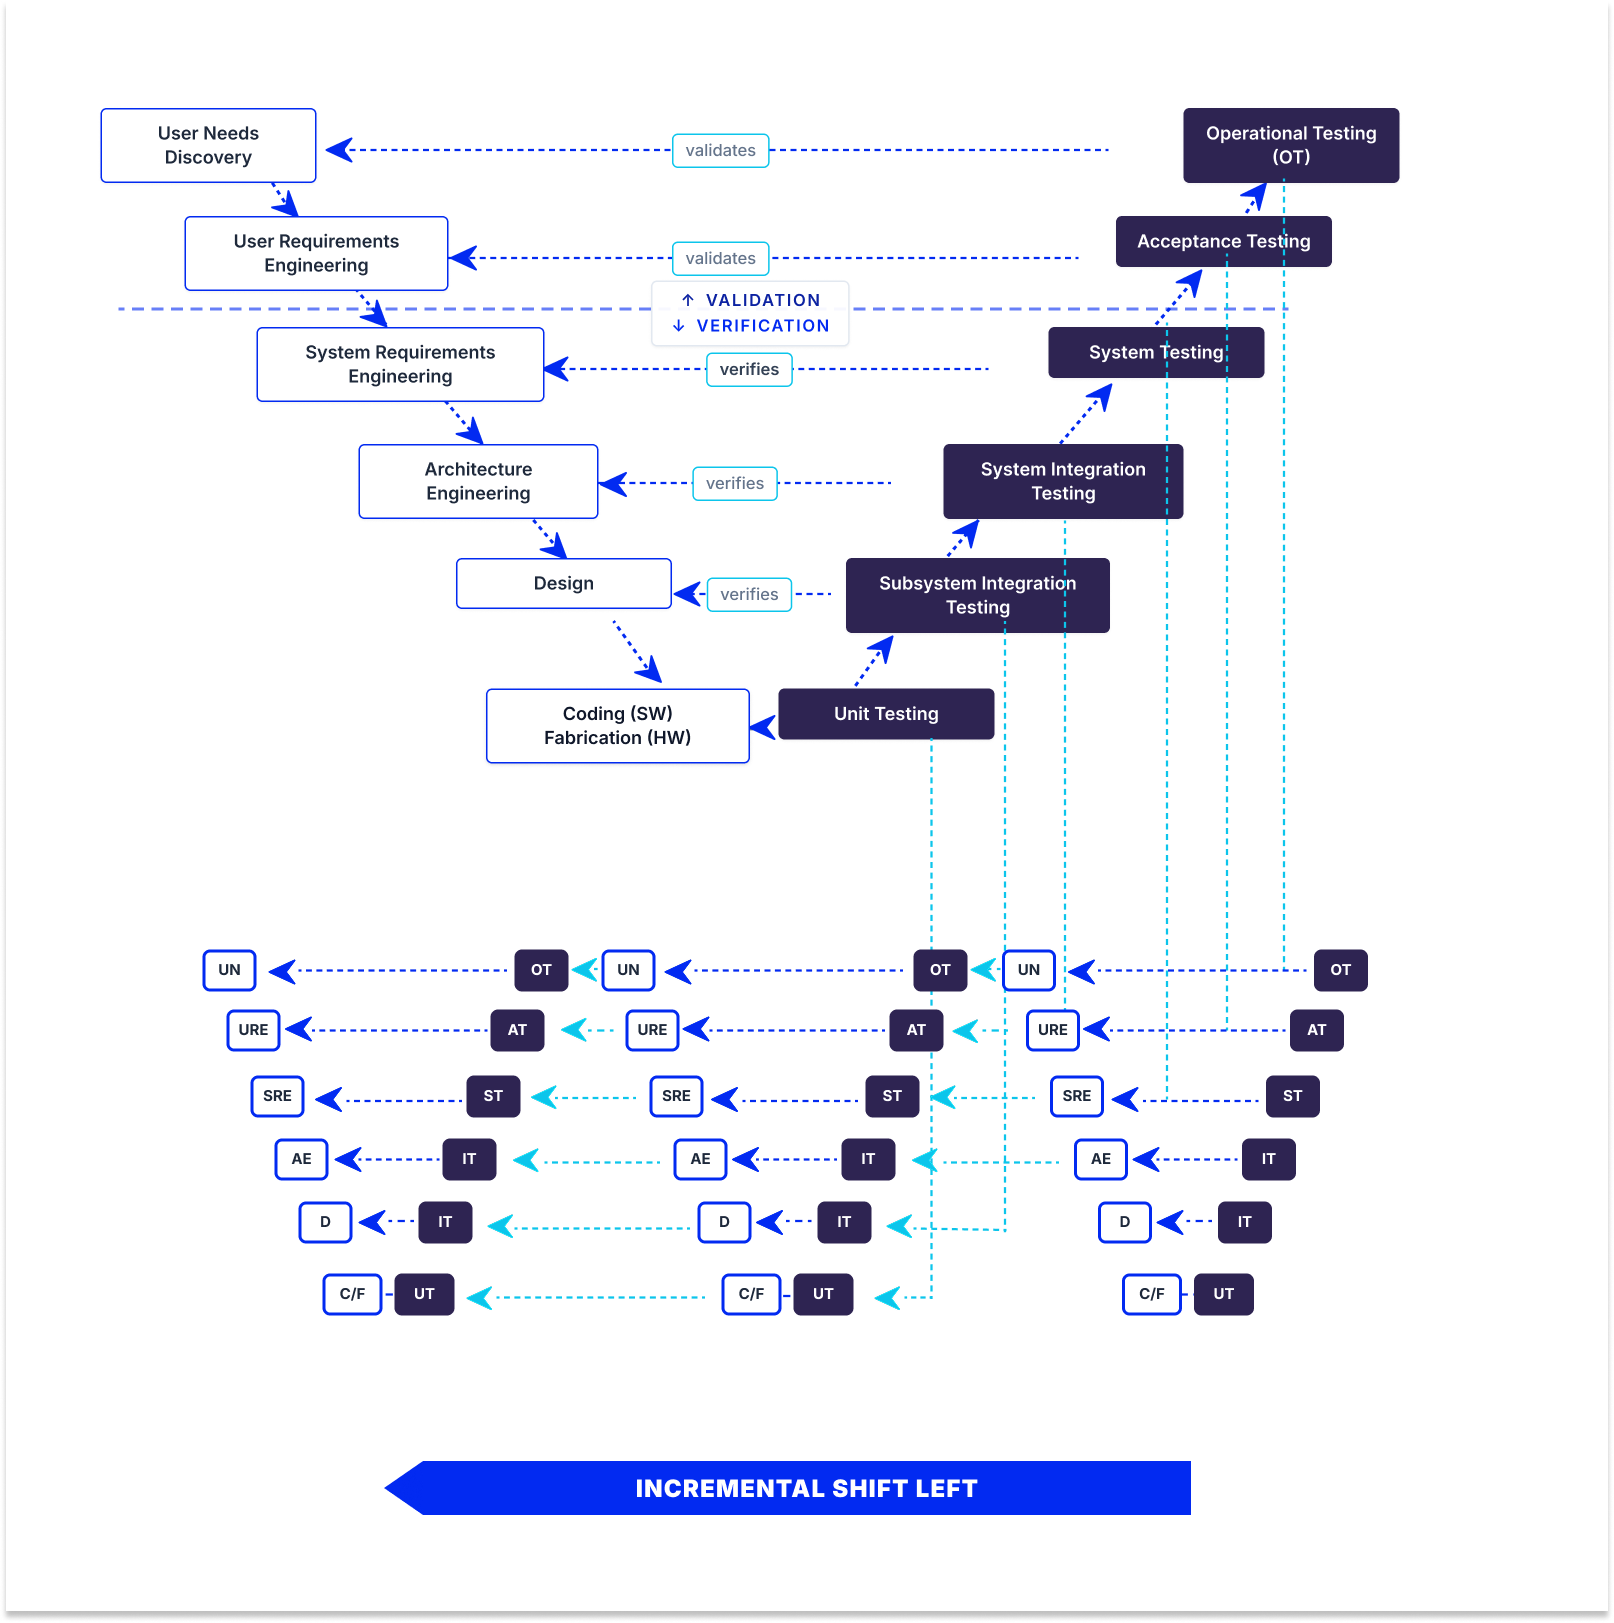
In incremental shift-left testing, the testing project breaks into smaller increments, each with its own V model (see the picture below). 

 Incremental shift-left testing where the V model breaks into smaller V models.

As a result, testing happens per increment rather than only once at the end. When each increment ships, developmental and operational testing shift left together. This is popular for large, complex systems with substantial hardware components, where you can’t test the whole system at once but can validate each subsystem as it’s built.

3. Agile/DevOps Shift Left

In Agile/DevOps shift-left testing, testing happens inside short sprints. Each sprint contains its own development and testing work. This means automated tests are triggered whenever there’s a code change in the CI/CD pipeline, so developers get the feedback the same day they change the code. 

4. Model-Based Shift Left

Model-based shift-left testing tests your model instead of code. It tests executable requirements, architecture, and design models, so testing begins almost immediately without waiting for code. The primary benefit of model-based shift-left testing is that you can catch requirements and expensive design defects. The catch is that model-based shift-left testing requires formal, executable models, which is why there is not a large adoption of this approach. 

Why DevOps Recommends Shift-Left Testing Principles

DevOps recommends shift-left testing principles for four reasons:

1. CI/CD pipelines require quality gates at every stage: A pipeline is a series of automated decisions about whether a change can proceed. If the only real check sits at the end, the pipeline isn’t deciding anything but only moving code toward one manual gate. Every stage needs its own criteria, including build, unit tests, static analysis, integration tests, and security scans.

2. Continuous deployment can’t wait for a manual QA cycle: If you deploy several times a day and your regression cycle takes three days, manual testing doesn’t work. If you stick to manual QA instead of automation, either deployment frequency drops to match testing or testing gets skipped. 

3. Shared quality ownership aligns with DevOps culture: DevOps dissolves the wall between development and operations. Leaving the “wall” of testing standing between development and QA reintroduces the same problem that DevOps tries to solve.

4. Faster feedback loops reduce context switching: A developer who gets a test failure immediately after pushing the change is still holding it fresh in their head, as opposed to someone who gets it later and has to find the context again.

How Does Automated Shift Left Testing Work

Automated shift-left testing relies on running fast and inexpensive checks early in the development process. It saves slow and expensive tests for later stages when code is more stable. 

The process starts at the pre-commit stage, where quick scans catch basic issues, such as formatting problems and leaked passwords. Next, when code is submitted for review, the system runs thorough unit tests and security checks within minutes. If anything fails at this review stage, the code cannot be merged into the main project. 

After merging, deeper integration checks and container scans run to ensure different parts of the system work together. Finally, comprehensive performance and end-to-end tests are run before the software is released to the public. Splitting tests into these distinct stages keeps the process fast so developers actually use it.

Mistakes to Avoid When Automating for Shift-Left Testing

When implementing automated shift-left testing, avoid these common pitfalls:

  • Writing tests after the fact: Tests written after code exists only confirm current behavior, including bugs, rather than validating requirements. Write tests from acceptance criteria to catch actual defects.
  • Slow test suites: Tests taking longer than 10 minutes force context switching as developers change tasks. Parallelize, stage tests, and trim low-value checks to keep runs fast.
  • Lack of ownership model: Clearly define who writes unit tests, maintains integration suites, and fixes broken pipelines. Without clear ownership, test suites decay and flaky tests get ignored.
  • Focusing on line coverage over defect escape rate: High line coverage does not guarantee meaningful assertions. Track the defect escape rate to measure true effectiveness.

Shift Left Testing Benefits

Adopting shift-left testing offers important organizational and operational benefits, including:

  • Lower defect cost: Bugs identified early in development are substantially cheaper and simpler to resolve than those discovered in production.
  • Faster release cycles: Continuous quality checks eliminate long stabilization periods prior to deployment.
  • Fewer production defects: Early checks catch architecture and requirements flaws before code reaches end users.
  • Shorter feedback loops: Developers address feedback immediately while context is still fresh.
  • Security cost reduction: Catching vulnerabilities during review avoids costly post-release incident response and patches.
  • Better collaboration: Early QA involvement fosters shared quality ownership across engineering teams.

Shift Left Testing Tools Worth Knowing in 2026

Effective shift-left testing relies on a modern toolkit tailored to every phase of the development lifecycle. Here are the top tools and frameworks essential for implementing shift-left testing in 2026:

Static Analysis and Secret Scanning

SonarQube: Analyzes source code for bugs and security vulnerabilities, enforcing quality gates directly on pull requests.

Semgrep: Lightweight static analysis using custom, code-like rules for fast feedback during development.

TruffleHog & Gitleaks: Scan repositories and commit histories via pre-commit hooks to catch secrets and API keys before they are pushed.

Unit and Integration Testing

JUnit, pytest & Jest: Essential unit testing frameworks for Java, Python, and JavaScript to build fast, automated test suites.

Testcontainers: Provides throwaway Docker instances for databases and services, removing shared-environment bottlenecks during integration tests.

API and Contract Testing

Postman & Newman: Enables teams to author API tests in a GUI and execute them automatically in CI/CD pipelines.

Pact: Facilitates consumer-driven contract testing to verify microservices independently without full deployments.

Dependency and Container Security

Snyk automatically scans third-party dependencies for vulnerabilities and opens automated pull requests for fixes.

Trivy: Fast open-source scanner for container images, filesystems, and infrastructure as code.

Trivy is an open-source scanner covering container images, filesystems, and infrastructure as code, fast enough to sit inside a build without slowing it down.

CI/CD Orchestration

GitHub Actions, GitLab CI & Jenkins: Automate and orchestrate pipeline stages, enforcing quality gates before code merges.

Shift Left vs. Shift Right Testing: What’s the Difference

Shift-left testing moves testing (left) earlier in the process, alongside or even before development. Shift-right testing moves testing (right) later into the process, into the production environment, with real data. 

The entire concept of shift-right testing is that some defects cannot be truly uncovered before real users hit real infrastructure, so it tests on actual traffic patterns, third-party behavior under load, and edge cases. 

TestFiesta Gives Your Shift Left Strategy Somewhere to Land

Shift-left testing aggregates results across multiple systems (CI unit tests, post-merge contract tests, PR security scans, and sprint exploratory sessions), often making release readiness difficult to track.

TestFiesta consolidates these sources into a single view by ingesting automated CI pipeline results alongside manual and exploratory test outcomes through its Automation API.

Reusable configurations allow test cases to execute across multiple browsers, devices, and environments without duplication, while shared steps centralize common workflows like login or checkout to streamline suite maintenance.

Built-in defect tracking connects failures directly to test executions. Integrations with Jira and GitHub automatically sync fields, update statuses, and create context-rich issues from failed runs.

Organizations use folders, tags, and custom fields to map automated run data. Pricing is a flat $10 per user per month with all features included.

Ready to Elevate Your Shift-Left Testing Strategy?

Streamline your quality workflow, centralize your test results, and empower your team to ship faster with confidence.

Start your free trial today

FAQs

Does shift-left testing mean developers replace QA engineers?

No, shift-left testing does not mean that developers replace QA engineers. It changes what QA spends time on. Repetitive testing is automated, and developers write tests alongside their code, while QA moves toward work that requires critical judgment, such as reviewing requirements for testability, designing test strategy, exploratory testing, and owning the quality signal. 

How do you measure whether shift-left testing is actually working?

To measure whether shift-left testing is actually working, you should track essential software testing metrics, including defect escape rate, the percentage of defects found in production rather than before release, mean time to detect, and pipeline duration, since a slow pipeline gets bypassed. 

What’s the difference between shift-left testing and test-driven development (TDD)?

Shift-left testing is a broad strategy that moves all quality activities, including requirements reviews, static analysis, and security scans, earlier in the development process. Test-driven development (TDD) is just one specific practice within that broader strategy, where you write a failing test before writing the code to pass it and refactor the results. Simply put, you can practice shift-left testing without using TDD, but you cannot do TDD without shifting left.

Testing guide
Best practices

Ready for a Platform that Works

The Way You Do?

Stop fighting your tools. Start shipping with confidence. TestFiesta adapts to your workflow, not the other way around.

Welcome to the fiesta!