All Articles

Ah. Nothing to see here… yet

It may be coming soon, but for now, try refining your search

Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.

Introduction

Manual and automated testing are essential for catching bugs and regressions and ensuring the core functionality of the product works as expected. But even when all tests pass, users can still run into unexpected bugs right away. That’s because both manual and automated tests are scripted, and they only check for issues that were written down ahead of time. Exploratory testing is different; it’s unscripted. 

What Is Exploratory Testing

Exploratory testing is an approach to software testing where testers simultaneously learn about the application, design test cases, and execute them. Unlike traditional scripted testing, which relies on pre-written, step-by-step test plans, exploratory testing encourages testers to rely on their intuition, domain knowledge, and critical thinking to discover defects that structured tests might miss.

Say you are testing the checkout. The scripted test adds an item, enters a valid card, and confirms the order is completed. It passes. In contrast, an exploratory tester adds the item, opens a second tab, removes it from the cart there, then returns to the first tab and pays. That test was not written because nobody thought of it until they were sitting in front of the product with two tabs open.

That said, exploratory testing can be as disciplined as any other intellectual activity, and its quality depends heavily on the tester’s skill. 

Exploratory Testing vs. Ad Hoc Testing

Both ad hoc and exploratory testing are two types of unscripted testing, but they are not the same. Ad hoc testing is informal, unplanned, and leaves no record of what was covered, making it unstructured and unaccountable. In contrast, exploratory testing is unscripted but structured and accountable, following a specific mission, a defined block of time, and detailed notes so you can track exactly what was tested and discovered.

When Should You Use Exploratory Testing

Exploratory testing pays off most where writing test cases first would be impossible or wasted, including the following cases.

  • When requirements are thin or still moving: If the requirements are thin, there is nothing to write detailed cases from. Exploring the feature is a better option in that case.
  • On brand-new features: Brand-new features should be explored after they are shipped because that allows the team to verify the functionality of what was actually shipped.
  • Around bug fixes and risky changes: Areas around risky changes and bugs should be explored because they are critical in nature.
  • Before a release, in the gaps: Automated suites cover the expected paths. A focused exploratory session covers the paths that nobody thought of.
  • On usability and real-world flows: A test case can confirm a button works. It cannot tell you that the flow takes eleven clicks, and the error sits below the fold. That’s something exploratory testing can confirm.

Types of Exploratory Testing

There are a few ways to perform exploratory testing, including:

1. Freestyle Exploratory Testing

Freestyle exploratory testing doesn’t have any rules, charter, or coverage target. It’s useful when you need to get familiar with an application quickly, verify another tester’s work, investigate a defect, or run a fast smoke check.

2. Scenario-Based Exploratory Testing

Scenario-based exploratory testing is built around realistic user scenarios. Testers mimic how people actually use the system, explore different paths within a scenario, and watch for breakdowns in the flow. It’s more structured than freestyle and well suited to new features with a clear user journey.

3. Strategy-Based Exploratory Testing

Strategy-based exploratory testing is guided by an overarching strategy, with testers applying established software testing techniques such as boundary value analysis, equivalence partitioning, risk-based testing, and error guessing. Experienced testers tend to be most effective here because the technique supplies structure while judgment decides where to aim it.

4. Session-Based Test Management (SBTM)

Session-based test management (SBTM) is a formal framework rather than a loose style. Testing is organized into time-boxed sessions with charters, reports, and debriefs. 

5. Pair Testing

Pair testing involves two people at one machine, one driving and one observing. It’s slower on raw coverage, but the observation catches what the driver misses.

6. Bug Hunts

Bug hunts refer to a focused group session, often including people from outside QA, aimed at one area for a fixed window. It’s beneficial because it gets fresh eyes on a product.

How to Do Exploratory Testing: Step by Step

The steps below follow session-based test management, the most widely used framework for running exploratory testing in a way you can report on. 

Step 1: Write a Testing Charter

A charter is a short statement of what the session is for. It sets direction without prescribing steps. Charters are created before testing starts, can be changed or updated at any time, and are often built from a specification, a test plan, or the results of earlier sessions. 

Step 2: Time-Box the Session

Set an explicit time limit before you begin, typically 60 to 90 minutes. Time-boxing prevents fatigue, keeps testing focused on the charter, and makes session results easier to schedule and compare across team members.

Step 3: Explore and Take Notes in Real Time

During the session, testers execute tests actively guided by the charter while maintaining the flexibility to follow unexpected leads, explore interesting side paths, and adapt based on real-time observations and critical judgment.

As you explore, record concise notes in real time to capture essential details without interrupting your cognitive flow. Key areas to document include coverage and paths, environment and setup, key decisions and questions, Anomalies, and observations.

Maintaining consistent, high-quality notes ensures the session is transparent and fully reproducible for the post-session debrief, striking a balance between lightweight logging and clear accountability.

Step 4: Investigate Anomalies Deeper

When you encounter unexpected behavior, edge cases, or potential defects during a session, pause to investigate and isolate the anomaly. Verify whether the behavior is consistently reproducible, determine the specific trigger conditions or environmental factors, and assess its severity. However, maintain a balance with your time box. 

If an issue requires prolonged root-cause analysis or extensive log diving, note the initial details and park it for dedicated investigation after the session so you don’t exhaust your remaining session time.

Step 5: Debrief and Document Findings

Once the time-box expires, hold a short debrief session (typically 5 to 15 minutes) with a lead, peer, or product owner. Review the session notes, charter coverage, time allocation (split across test execution, bug investigation, and setup), and key observations. 

Log all confirmed bugs into your tracking system with full reproduction steps, logs, and screenshots attached. Finally, evaluate whether any impactful exploratory paths or discoveries should be converted into automated regression test cases or future testing charters.

Advantages and Limitations of Exploratory Testing

Exploratory testing offers high flexibility and rapid bug discovery, though it requires skilled testers and disciplined documentation to maintain accountability. Here are some notable advantages and limitations of exploratory testing:

Advantages of Exploratory Testing

  • Finds unscripted defects that traditional test cases miss.
  • Requires zero upfront test preparation, ideal for rapidly changing features.
  • Adapts immediately in real-time to focus on newly uncovered risks.
  • Builds domain and product knowledge quickly to improve future scripted tests.
  • Leverages human intuition to evaluate usability and end-to-end user flows.
  • Provides high flexibility, allowing test charters to shift with daily priorities.

Limitations of Exploratory Testing

  • Lacks heavy documentation, which can reduce traceability and test reproducibility.
  • Relies heavily on individual tester skill, leading to inconsistent coverage across team members.
  • Prone to tester bias, as individuals often gravitate toward familiar product areas.
  • Difficult to quantify or prove test coverage without strict session logging.
  • Session metrics can easily skew due to reporting discrepancies or productivity variations.
  • Cognitively demanding, typically limiting testers to a few high-quality sessions per day.

Most of these limitations stem from documentation and management challenges rather than exploration itself, issues that proper tooling can easily resolve.

How TestFiesta Helps Turn Exploratory Testing Results Into Clarity

The hard part of exploratory testing is what happens after: proving what got covered, keeping findings attached to the work that produced them, and making sure good ideas from a session do not evaporate. TestFiesta can help.

Built-In Bug Tracking: TestFiesta has native bug tracking inside the platform, so a defect found mid-session is logged without leaving the test flow, with screenshots and logs attached. Every defect links to the exact test execution that found it, which keeps the context alive forever.

Organized Sessions: Flexible tagging covers cases, runs, users, milestones, and defects, so you can slice reports by feature, risk, sprint, or team without a rigid folder hierarchy. That is how a charter-per-area approach stays readable even after many sessions.

Permanent Coverage: When a session uncovers a path worth checking every release, AI test case creation generates structured cases with steps, expected results, and tags from your requirements or a prompt, and shared steps let you define reusable flows like login or checkout once and reference them everywhere. The discovery becomes a regression test instead of a note someone loses.

Manual and Automated Results Live Together: The automation API feeds automated results into the same platform, so exploratory findings and automated coverage appear in one view. Jira and GitHub integrations auto-map fields and keep requirements, bugs, and coverage aligned, so a bug found during exploration reaches the developer with full context attached.

Every feature is included at one flat price of $10 per user per month, with no tiers and no feature gates.

Streamline your QA workflow and stop letting valuable testing insights slip through the cracks.

With TestFiesta, you get an all-in-one platform built for modern testing teams.

Start your free trial today

FAQs

Is exploratory testing the same as manual testing?

No, exploratory testing is not the same as manual testing. Manual testing is often scripted and describes how a test is run by a person rather than a machine. Exploratory testing describes how a test is designed in the moment rather than in advance. Exploratory testing is a form of manual testing, but not all manual tests are exploratory.

Can exploratory testing be automated?

No, exploratory testing cannot be automated since it depends on a person deciding what to try next instead of relying on automation frameworks and scripts. However, certain tools can make exploratory testing easier. 

How do you measure the effectiveness of exploratory testing?

You can measure the effectiveness of exploratory testing through detailed session reports, which can include sessions per testing area, time spent on test design, bug investigation, and setup. 
Testing guide

Introduction

Security is often treated as the final gatekeeper in the development lifecycle, but waiting until the end is a recipe for disaster. From broken access control to supply chain vulnerabilities, modern applications face constant threats. 

If you’re wondering which tools actually move the needle, you’re in the right place. We’ll explore security testing in detail, including the seven main types of security testing, actionable strategies for CI/CD integration, and the tools that matter most for today’s engineering teams.

What Is Security Testing in Software

Security testing is the practice of checking an application for weaknesses that an attacker could exploit to steal data, gain access they should not have, disrupt service, or abuse functionality. It covers the code, the running application, the third-party components it depends on, and the infrastructure it runs on.

Unlike functional testing, where you verify expected behavior against a spec, security testing spends most of its time on unexpected behavior. The tester’s job is to send inputs the developer never planned for and see what breaks.

What Security Testing Actually Tests For

The specifics vary by application, but most security testing targets the same core categories of weakness:

  • Unauthorized access to data or functionality. Broken access control is the most common serious flaw in web applications. It shows up when a regular user can view another user’s records by changing an ID in the URL or calling an admin endpoint that the UI never exposed.
  • Injection flaws. SQL injection, command injection, and cross-site scripting (XSS) all happen when untrusted user input reaches a sensitive operation without proper handling. A search box that passes its value straight into a database query is a textbook example.
  • Authentication and session weaknesses. Weak password policies, missing rate limiting on login, session tokens that never expire, and predictable password reset links all give attackers a way in through the front door.
  • Vulnerable open-source dependencies. Modern applications pull in hundreds of third-party packages. If one of them has a known CVE and you are running the affected version, the vulnerability is yours regardless of how clean your own code is.
  • Sensitive data exposure. Weak or missing encryption, secrets committed to source control, and misconfigured storage buckets left readable by the public all fall here.
  • Logic flaws. These are the hardest to catch with tools because nothing is technically broken. A checkout flow that lets a user edit the discount field in the request and set it to 100 percent works exactly as coded. It’s just coded wrong.

The 7 Types of Security Testing and What Each One Catches

No single testing type covers all bugs. Here are seven types of security testing, along with what each one catches.

1. SAST: Static Application Security Testing

SAST tools analyze source code, bytecode, or binaries without running the application. They trace how data flows through the code and flag patterns that match known vulnerability classes, such as user input reaching a SQL query without sanitization.

What SAST catches: Injection flaws, hardcoded secrets, insecure cryptographic calls, and unsafe function use, all before the code is ever deployed.

Where SAST falls short: SAST cannot see runtime configuration, environment issues, or how components behave when connected. It also tends to produce false positives because it reasons about what code might do rather than observing what it actually does.

When to run SAST: In the Integrated Development Environment (IDE) and on every pull request (PR). This is the earliest possible point to catch a problem, which makes it the cheapest.

2. DAST: Dynamic Application Security Testing

DAST tools test the running application from the outside, the same way an attacker would. They crawl the app, send crafted requests, and analyze responses for signs of vulnerability. They have no access to source code.

What DAST catches: Server misconfigurations, missing security headers, authentication problems, and injection flaws that only appear when the full stack is running.

Where DAST falls short: DAST cannot tell you which line of code caused the problem, only that the problem exists. It also struggles with single-page apps and complex authentication flows unless configured carefully.

When to run DAST: Against a staging environment on a schedule or before release. It needs a deployed application to work.

3. IAST: Interactive Application Security Testing

IAST places an agent inside the running application and watches how code behaves as tests exercise it. It combines SAST’s visibility into code with DAST’s view of real runtime behavior.

What IAST catches: Vulnerabilities in code paths that your existing functional or integration tests actually reach, with precise line-level detail and far fewer false positives than SAST alone.

Where IAST falls short: IAST only sees the code that gets executed. If your test suite never touches a feature, IAST never looks at it. It also requires language-specific agents, so coverage depends on your stack.

When to run IAST: During QA and integration testing, where automated test suites already drive the application.

4. SCA: Software Composition Analysis

SCA scans your dependency manifest and lock files, identifies every third-party package and its version, and checks them against vulnerability databases. Many tools also flag license issues.

What SCA catches: Known CVEs in open-source libraries, outdated packages, and transitive dependencies you did not know you were pulling in.

Where SCA falls short: SCA only knows about disclosed vulnerabilities. A zero-day in a package you use will not show up until it is published. It also cannot tell you whether your application actually calls the vulnerable function.

When to run SCA: On every build. Dependency vulnerabilities are disclosed daily, so a clean scan last week means nothing today.

5. Penetration Testing

Penetration testing is a human-led attack simulation. A skilled tester, either internal or from a specialist firm, is given a scope and a time window and tries to compromise the application using the same techniques a real attacker would.

What penetration testing catches: Business logic flaws, chained vulnerabilities where several low-severity issues combine into a serious one, and anything that requires understanding what the application is for rather than just how it is built.

Where penetration testing falls short: It is expensive, point-in-time, and limited by the tester’s skill and the scope they were given. A pen test in March says nothing about code shipped in April.

When to run penetration testing: Before major releases, after significant architecture changes, and on a regular cadence (often annually) for compliance requirements.

6. API Security Testing

APIs are now the primary attack surface for most applications, and they fail differently from web UIs. There is no client-side validation to rely on, and object-level authorization flaws are easy to introduce and hard to spot in a UI walkthrough.

What API testing catches: Broken object-level authorization (one user accessing another user's resources by ID), excessive data exposure where endpoints return more fields than the client needs, missing rate limiting, and mass assignment flaws.

Where API testing falls short: Most API testing depends on having an accurate API specification. Undocumented or shadow endpoints are missed entirely.

When to run API testing: Alongside DAST and as part of API contract testing in the pipeline.

7. Vulnerability Scanning

Vulnerability scanning is the broadest and shallowest layer. Scanners check servers, containers, networks, and cloud configurations against databases of known weaknesses: unpatched software, open ports, default credentials, and insecure settings.

What vulnerability scanning catches: Infrastructure and configuration issues that sit underneath the application.

Where vulnerability scanning falls short: Scanners are signature-based. They find known issues and miss novel ones, and they do not understand your application logic at all.

When to run vulnerability scanning: Continuously against production infrastructure and on every container image before it ships.

The OWASP Top 10: Your Security Testing Starting Point

The Open Worldwide Application Security Project (OWASP) Top 10 is the most widely referenced list of web application security risks. It maps each category to specific Common Weakness Enumerations (CWEs), which makes it directly usable as a test planning checklist.

Here’s the OWASP Top 10 checklist:

  1. A01 Broken Access Control. A01 signals users accessing data or performing actions they should not. OWASP’s data shows an average of 3.73 percent of tested applications had at least one weakness in this category.
  2. A02 Security Misconfiguration. A02 refers to default settings, debug mode left on, open storage buckets, and missing security headers. 
  3. A03 Software Supply Chain Failures. A03 covers dependency confusion, malicious packages, and tampered build pipelines, not just outdated libraries. OWASP notes that it had the fewest occurrences in test data but the highest average exploit and impact scores.
  4. A04 Cryptographic Failures. A04 includes weak or missing encryption of sensitive data, both at rest and in transit.
  5. A05 Injection. A05 refers to SQL injection, command injection, and XSS. 
  6. A06 Insecure Design. A06 includes flaws baked into the architecture before a line of code is written. No amount of secure coding fixes a design that never considered threat modeling.
  7. A07 Authentication Failures. A07 refers to weak login, session handling, and identity management.
  8. A08 Software and Data Integrity Failures. A08 includes unverified updates, insecure deserialization, and CI/CD pipelines that trust code without verifying it.
  9. A09 Security Logging and Alerting Failures. A09 refers to problems where you were breached and never knew. Insufficient logging means incidents go undetected for months.
  10. A10 Mishandling of Exceptional Conditions. A10 refers to applications that fail open, leak stack traces, or behave unpredictably when they hit an edge case.

For a team starting security testing from scratch, the practical move is to map each category to the testing type that catches it. 

SAST and SCA cover A03, A04, A05, and A08. DAST and vulnerability scanning cover A02 and A07. API testing and penetration testing are your best bet for A01 and A06. A09 and A10 mostly come down to reviewing how the application logs and handles failure, which is closer to a design review than a scan.

Automated Security Testing: Shifting Left Without Slowing Down

Shifting left means running security checks as early in development as possible, when fixes are cheapest. In practice, that means wiring automated security testing into the pipeline so it runs without anyone having to remember to trigger it.

A workable pipeline in security testing QA automation layout looks like this:

Pre-commit and IDE: This happens on the developer’s local machine before they share their work. By running lightweight security checks here, developers can fix issues immediately, similar to how a spell-checker catches a typo while you are typing a sentence. This prevents bad code from ever leaving the developer’s laptop.

Pull Request (PR): A PR is the process of submitting code to be merged into the main project branch. At this stage, the team performs a deeper analysis. Because the code is about to become part of the shared application, running full security scans here acts as a gatekeeper, ensuring no new vulnerabilities are introduced into the core codebase.

Build: This is the automated assembly process where the code is compiled, packaged, and turned into a runnable application. Since this stage creates the actual artifacts (like container images) that will be deployed, it is the right time to check that those packages themselves and the infrastructure code defining how they run are secure.

Staging: This is an environment that mirrors the real, live environment as closely as possible. Since the application is actually running here, it allows for more sophisticated security testing that requires a live, functional stack, such as testing how the app behaves when an attacker sends it unexpected requests.

Production: This is the live, user-facing environment. Because this is the “real world,” security testing here focuses on continuous monitoring, constantly scanning the live infrastructure for new threats or configuration issues that might have appeared since the last deployment.

Security Testing Tools Worth Knowing in 2026

This list includes some of the most recommended tools for security testing in 2026, grouped by what they do.

SAST: Static Application Security Testing

Best tools for SAST are:

  • Semgrep: Fast, open-source, and ideal for custom pattern-based checks.
  • CodeQL: GitHub’s powerful semantic analysis engine; treats code as a database.
  • Checkmarx / Veracode: Established enterprise platforms offering broad coverage and reporting.

DAST (Dynamic Application Security Testing)

Best tools for DAST include:

  • ZAP: Highly popular, open-source scanner with strong automation capabilities.
  • Burp Suite: Industry standard for manual penetration testing, with automated scanning in the Professional version.

SCA (Software Composition Analysis)

Most recommended tools for SCA include:

  • Snyk: Developer-centric tool that integrates into workflows and can automate dependency fix requests.
  • Trivy: All-in-one scanner for containers, filesystems, and infrastructure-as-code.

IAST (Interactive Application Security Testing)

Expert-recommended tools for IAST include:

  • Contrast Security / Checkmarx IAST: These require installing a runtime agent within the application to monitor code behavior.

TestFiesta Brings Your Security Testing Evidence Into a Consolidated Room

The most common problem with security testing is not finding vulnerabilities. It is proving, at release time, that the ones that mattered got fixed and retested. 

Security findings tend to live in five different places: a SAST dashboard, a DAST report PDF, a pen test spreadsheet from the vendor, and retest evidence somewhere in Slack. When a stakeholder asks whether the release is safe to ship, nobody can answer from one screen.

TestFiesta gives security testing the same structure as every other test type, so the evidence lives alongside your functional and regression results instead of in a separate silo.

  • Security test cases live next to functional ones. Write test cases for each OWASP category, tag them by risk area, and group them into the same test runs and milestones your team already uses. Custom tags mean you can filter a run down to just the A01 access control checks or just the API authorization tests when someone asks.
  • Automated results feed in through the API. TestFiesta’s automation API accepts results from your pipeline, so automated and manual test outcomes sit in one consolidated view. Custom fields are built for mapping data from automated tests, so you can capture the details you need alongside each result.
  • Findings become tracked defects with full traceability. A failed security check becomes a defect linked to the exact test and execution that found it. Attach screenshots, logs, and files. Assign it to a developer, and when they push a fix, reassign it to QA for verification. The defect record shows the whole chain from discovery to retest.
  • Jira and GitHub stay in sync. For teams that track engineering work elsewhere, defects sync to Jira or GitHub issues with the test context attached, so developers see what failed and how to reproduce it without leaving their tracker.
  • Reporting covers security tests like everything else. Because security tests are tagged and tracked alongside functional ones, they appear in the same reports, without stitching together exports from five tools.

‍

Don’t let critical security insights get lost across fragmented tools and separate dashboards.

Break down testing silos by bringing your results into a single, cohesive view.

Sign up for a free trial today

FAQs

Can automated security testing replace penetration testing?

No, automated security testing catches known vulnerability patterns quickly and repeatedly, which is exactly what you want in a pipeline. It does not catch business logic flaws, chained vulnerabilities, or anything that requires understanding what the application is for. Penetration testing covers that gap. 

How often should security testing be performed?

It depends on the testing type. SAST and SCA should run on every pull request or build, since new code and new CVEs arrive daily. DAST should run against staging on every deploy or at least weekly. Penetration testing is typically done before major releases and on an annual cadence for compliance, though high-risk applications warrant more frequent testing.

What’s the difference between SAST and DAST, and which one should I start with?

SAST analyzes source code without running it and finds issues early, with line-level detail but more false positives. DAST tests the running application from the outside and finds runtime and configuration issues, but cannot point to the line of code responsible. If you are starting from scratch, start with SAST plus SCA on pull requests. They are the cheapest to set up, run earliest, and cover the widest range of OWASP categories. Add DAST once you have a stable staging environment to point it at.

Testing guide
Best practices

Introduction

In software development, your code can pass every unit test, yet still fail the moment a customer tries to complete a purchase. This disconnect between “passing tests” and “working products” is why end-to-end (E2E) testing is the most critical safety net in your CI/CD pipeline. This guide explores how to build a robust E2E strategy in 2026, from choosing the right frameworks to mastering the workflows that actually catch bugs before your users do.

What Is End-to-End Testing

End-to-end testing (E2E testing) validates a complete user journey through an application, from the first interaction to the final outcome, across every layer of the system. Instead of checking whether one function returns the right value, an E2E test asks a bigger question: can a user actually accomplish the thing they came to do?

A typical E2E test for an ecommerce app might sign up a new user, search for a product, add it to the cart, apply a discount code, pay with a test card, and confirm that the order appears in the account history and the confirmation email fires. If any layer fails along the way, whether that is the frontend, an API, the database, or a third-party payment gateway, the test fails.

That is the defining trait of E2E testing. It exercises the system the way a user experiences it, in a test environment as close to production as possible. It is the slowest and most expensive type of test to run and maintain, which is why it sits at the top of the testing pyramid. You write fewer E2E tests than any other kind, and you reserve them for the journeys that matter most.

What Does an E2E Test Cover

A single well-designed E2E test touches more of your system than any other test type. In one run, it can cover:

  • The full UI flow from first click to final confirmation. Every page load, form submission, button click, and redirect that a user passes through is verified in a real browser.
  • API calls and backend responses are triggered by user actions. The test does not call APIs directly. It triggers them the way a user would and verifies that the results surface correctly in the interface.
  • Database reads and writes across the entire transaction. An order placed in the UI should exist in the database with the right status, quantity, and user association. E2E tests confirm data persists correctly, not just that a success message appeared.
  • Third-party integrations. Payment gateways, email services, auth providers, and shipping APIs are where many production failures originate because teams do not control that code. E2E tests are often the only tests that exercise these boundaries realistically.
  • State that accumulates across multiple screens or requests. Session data, cart contents, multi-step form progress, and permissions all carry state between steps. Unit tests cannot catch a cart that empties itself between the shipping page and the payment page. An E2E test catches it immediately.

End-to-End Testing vs Unit Testing vs Integration Testing

These three test types answer different questions, and a healthy suite needs all of them.

Unit tests verify a single function, method, or component in isolation, with all dependencies mocked. They answer: Does this piece of code do what it should? They run in milliseconds, pinpoint failures precisely, and make up the bulk of a healthy test suite.

Integration tests verify that two or more modules work together correctly, such as a service and its database, or two internal APIs exchanging data. They answer: Do these pieces communicate correctly? They use real connections between the components under test but do not simulate a full user journey.

End-to-end tests verify the entire system through the user’s interface. They answer: Does the whole product work for a real user? They mock nothing, or as little as possible, and run against a deployed environment.

Unit tests are fast, cheap, and precise but blind to interaction bugs. Integration tests catch contract mismatches and data-flow issues between modules but still miss UI-level and cross-system failures. E2E tests catch the failures users actually hit but are slow, environment-dependent, and harder to debug because a failure could originate anywhere in the stack.

Types of End-to-End Testing

E2E testing can be classified into two broad categories:

Horizontal E2E: Tests a complete business workflow across multiple features or systems, usually at the same level of the application. Login → Search product → Add to cart → Checkout → Payment → Order confirmation

Vertical E2E: Tests a single feature or business capability through all the technical layers involved. UI → Frontend → API → Payment Service → Database → Response → UI

In addition to horizontal and vertical, E2E tests can also be grouped by what and how they test. These types include:

1. UI-Driven E2E Testing

UI-driven E2E testing is a framework that drives a real browser, clicks through the interface, and asserts on what the user would see. It provides the highest-fidelity validation of the actual user experience, and it is also the slowest and most brittle form, since every UI change can affect the test. Use it for journeys where visual and interactive correctness is the point, such as sign-up, checkout, and onboarding.

2. API-Assisted E2E Testing

API-assisted E2E testing is a hybrid approach that keeps the E2E scope but moves setup and verification out of the UI. Instead of clicking through login and product creation to test checkout, the test seeds state through API calls, performs only the journey under test in the browser, and then verifies outcomes through the API or database. This cuts run time and flakiness dramatically without sacrificing coverage of the flow that matters. Most mature teams shift toward this model as suites grow.

3. Cross-Browser and Cross-Device E2E Testing

Cross-browser and cross-device E2E testing follows the same journeys, verified across Chromium, Firefox, and WebKit engines, and across viewport sizes and mobile devices. Rendering engines and mobile browsers still behave differently enough that a flow passing in Chrome can break in Safari. Teams usually run their full suite on one primary browser and a smaller smoke set across the rest, expanding coverage where analytics show real user traffic.

4. Business-Critical Regression E2E Testing

Business-critical regression E2E testing is a curated subset of E2E tests protecting the flows the business cannot afford to break, such as payments, authentication, and data export. They run on every release regardless of what changed. This set is intentionally small, aggressively maintained, and treated as a release gate. If a test in this tier fails, the release stops.

How to Write and Run E2E Tests: A Step-by-Step Workflow

Here’s a step-by-step guide to writing and running E2E tests:

1. Map your critical user journeys

Start from revenue and risk, not from feature lists. List the journeys where failure costs money, data, or trust: signup, login, checkout, subscription changes, or core workflow completion. Rank them. Your first E2E tests cover the top of that list, and nothing else, until those are stable.

2. Define pass conditions in user terms

Write each test’s success criteria before writing code, phrased as outcomes a user or the business would recognize: “the order appears in order history with status Confirmed,” not “the POST returns 201.” This keeps tests honest about what they actually verify and makes failures readable to non-engineers.

3. Choose your tool based on your stack

Match the tool to your team’s languages, your app’s platforms, and your CI constraints rather than picking whatever is available. A JavaScript team testing a web app has different needs than a Java shop maintaining a legacy grid or a mobile team covering native iOS and Android. 

4. Write tests with the Arrange-Act-Assert-Teardown pattern

Arrange the preconditions (seed a user, load a product), act out the journey, assert the outcomes, then tear down so the next run starts clean. Tests that depend on leftover state from previous runs are the single most common source of E2E flakiness. Each test should be able to run alone, in any order, and pass.

5. Use stable, intent-based selectors

Target elements by role, accessible name, or dedicated test IDs instead of CSS classes or DOM position. A selector like getByRole('button', { name: 'Place order' }) survives a redesign. One tied to .btn-primary:nth-child(3) does not. This one habit eliminates a large share of maintenance work over a suite's lifetime.

6. Integrate into CI/CD in two tiers

Run a fast smoke tier, roughly five to fifteen of your most critical journeys, on every pull request, keeping feedback under ten minutes. Run the full suite on merges to main and on a schedule. Gating every PR on the full suite slows the team and trains developers to ignore red builds. Gating nothing means E2E failures pile up unnoticed.

7. Track and triage flakiness

Treat a flaky test as a defect with an owner and a deadline, not background noise. Quarantine tests that fail intermittently so they stop blocking builds, then fix or delete them within a sprint. Track pass rates per test over time. A suite the team does not trust is worse than a smaller suite it does, because people start merging past failures.

What Is Automated End-to-End Testing

Automated end-to-end (E2E) testing replaces manual, human-driven user journey verification with scripts that execute actions against a real browser or device on demand or on a schedule. By performing the same tasks as a manual tester, but repeatably and in parallel, automation enables teams to scale regression of core application flows, which is not feasible with manual effort alone. While manual testing remains valuable for exploratory sessions to catch unexpected usability issues, automated E2E testing is essential for efficiently verifying stable, business-critical journeys across multiple browsers simultaneously.

A good rule is to automate journeys that are stable, repeated every release, and business-critical. Keep manual effort for new features still in flux, edge cases hit once, and exploratory work. Automating a flow whose UI changes weekly buys you a maintenance burden, not coverage.

End-to-End Testing Tools and Frameworks in 2026

Here’s a brief guide to the most useful tools and frameworks for end-to-end testing in 2026:

  • Playwright. Playwright is the top recommendation for new web E2E suites. It supports Chromium, Firefox, and WebKit through a single API, featuring auto-waiting, parallel execution, and built-in debugging. With support for JavaScript, TypeScript, Python, Java, and .NET, it is the ideal choice for new projects without legacy constraints.
  • Cypress. Cypress is a JavaScript framework that executes tests directly within the browser, offering a superior interactive developer experience with time-travel debugging and auto-waiting. Version 15 introduced AI-assisted test authoring. While it lacks native mobile support and broad cross-browser coverage compared to Playwright, it remains an excellent choice for frontend-focused JavaScript teams working primarily in Chromium.
  • Selenium. Selenium is the veteran enterprise standard. It implements the W3C WebDriver protocol, offering the broadest language and browser support available. Recent updates include WebDriver BiDi support and native Kubernetes provisioning for Selenium Grid. While slower and requiring more setup than modern alternatives, it remains the optimal choice for polyglot organizations with significant existing investment.
  • Appium. The industry standard for mobile E2E testing, Appium automates native, hybrid, and mobile web apps across Android and iOS using the WebDriver protocol. While it requires significant setup and maintenance due to platform-specific quirks, it remains the most comprehensive open-source option for cross-platform native app coverage.
  • AI-Native E2E Platforms. Tools like testRigor, Katalon, and mabl use natural language and self-healing locators to minimize test maintenance. While these platforms reduce the need for deep automation engineering expertise, they often involve vendor lock-in and provide less granular control than code-based frameworks. They are best used as a supplement to code-based suites.

Why TestFiesta Exists at the Exact Layer Where E2E Testing Gets Hard

None of the frameworks above solve the problem that actually kills E2E programs, not writing tests, but managing them. Once a suite runs across two frameworks, three browsers, and every pull request, the questions shift. Which journeys are covered and which are not, why did this test pass on main but fail on the release branch, and which failures are real defects as opposed to flaky infrastructure?

TestFiesta sits at that layer. Its automation API ingests results directly from your automation framework, so automated and manual test outcomes land in one consolidated view instead of scattered CI logs. Custom fields carry your automation metadata, such as browser, environment, and build number, into every result.

For the manual side of E2E coverage, shared steps let you define a flow like login or checkout once and reuse it across test cases, and configurations let one test case run against dozens of browser and environment combinations without duplication. AI test case generation cuts authoring time for structured E2E scenarios, pulling steps and expected results from requirements docs or a prompt.

When an E2E run surfaces a real defect, built-in bug tracking ties it to the exact test and execution that found it, and the Jira and GitHub integrations turn failed tests into issues with full context attached. Every feature ships in one plan at $10 per user per month, with no feature gating between tiers.

Stop digging through fragmented CI logs and start managing your E2E strategy with clarity.

Start your free trial today

FAQs

How many E2E tests should a healthy test suite have?

A healthy test suite does not need a lot of E2E tests. Most teams land between 20 and 100 E2E tests covering critical journeys, with unit and integration tests handling everything else. 

Should E2E tests run on every pull request or only before release?

E2E tests run on pull requests as well as before release. Most teams run a small smoke test of their product’s most critical journeys on every pull request, and then run a full suite before the release.

Testing guide

Introduction

Even if all your unit tests pass and your software is deployed, a user can still face problems with your service or payment gateways due to errors in the API response. Technically, there was nothing wrong with your product, but the failure was in the space between components. That space is what integration testing covers.

This ultimate integration testing guide walks through what integration testing is, how it works, and its main approaches, and gives you a practical integration testing workflow you can run in CI.

What Is Integration Testing

Integration testing is a form of software testing that checks that two or more components work correctly when combined. A component can be a class, a module, a service, a database, or a third-party API. The point is to test the handoff between each component in order to make sure that the connection works correctly.

Think of an online store where a unit test verifies that your “calculate total” function correctly adds up the prices of items in a cart. An integration test goes a step further. It verifies that once the total is calculated, your checkout service successfully passes that order information to the payment gateway and receives a “success” confirmation back. 

This test case ensures that your system components aren’t just working individually but are actually communicating and completing the transaction as expected.

What Does Integration Testing Actually Verify

Most integration bugs cluster around a small set of boundaries. A useful integration suite targets these directly:

  • Database connections and transaction boundaries. Integration testing verifies database connections and transaction boundaries, such as the ORM mapping matching the schema, rollbacks happening when a write fails halfway through, and migrations running cleanly against a fresh database.
  • REST and gRPC API request/response contracts. Integration testing for REST and gRPC API request/response contracts verifies that consumers send data that matches provider expectations, ensures that clients robustly handle empty nullable fields, and confirms that status codes and error bodies are properly managed.
  • Message broker event publishing and consumption. Integration testing at this boundary verifies that the producer serializes events in a format the consumer can deserialize and confirms how the system handles scenarios such as redelivery, ordering changes, or poison messages.
  • File system read/write operations. Integration testing for file system read/write operations verifies that path handling, encoding, permissions, and cleanup behave consistently across environments, ensuring that tests interacting with the actual disk catch issues that stub-based tests might miss.
  • External SaaS and third-party service adapters. Integration testing for external SaaS and third-party service adapters tests the APIs and services of payment providers, email, and auth providers. You rarely call the live service in a test, but you do need to verify your adapter handles its real response shapes, rate limits, and failure modes.

Types of Integration Testing

The classic integration testing strategies come from an era of monolithic systems with strict module hierarchies. They still apply, especially when you’re integrating a large codebase or replacing a legacy system piece by piece.

Big Bang Integration Testing

In big bang integration testing, all components are built, then integrated and tested at once. It’s simple to plan and requires no stubs or drivers. The drawback is obvious: when something fails, isolating the cause across dozens of simultaneously connected modules is slow. Big bang integration testing works for small systems with few components, but it’s not scalable.

Top-Down Integration Testing

In top-down integration testing, testing starts at the highest-level module and works downward. Lower-level modules that aren’t ready yet are replaced with stubs that return canned responses. This approach validates the main control flow early and lets you demo working features before the whole system exists. The cost is writing and maintaining stubs, and the lowest-level modules (often the ones handling data and I/O) get tested last.

Bottom-Up Integration Testing

Bottom-up integration testing is the reverse of top-down. Testing starts with the lowest-level modules and moves up. Higher-level modules that don’t exist yet are simulated with drivers that call the modules under test. Bottom-up integration testing surfaces problems in foundational components early, which is useful when the data layer is the riskiest part. The trade-off is that the top-level flow, the thing users actually see, is validated last.

Sandwich (Hybrid) Integration Testing

In sandwich or hybrid integration testing, top-down and bottom-up run in parallel and meet in the middle. Large teams use this to work on both ends simultaneously. It’s the most flexible approach and the most demanding. You need both stubs and drivers, and the middle layer where the two efforts converge is often the hardest to test properly.

In modern microservice environments, these categories often blur. You’re more likely to think in terms of which service boundary you’re testing than which direction you’re integrating. 

Where Integration Testing Fits in the Software Testing Pyramid

The testing pyramid puts many fast unit tests at the base, fewer integration tests in the middle, and a small number of end-to-end tests at the top. The shape reflects cost. Higher-level tests are slower to run, harder to maintain, and more likely to fail for reasons unrelated to the code under test.

Integration tests sit in the middle because they’re the best compromise. They catch real wiring bugs without the fragility of a full browser-driven flow.

Integration Testing vs Unit Testing

Unit testing focuses on isolated functions or classes using mocked or stubbed dependencies, typically running in milliseconds to catch specific logic errors that suggest the code itself is incorrect. In contrast, integration testing examines how two or more components interact by utilizing real dependencies like databases, APIs, or message brokers. This process is slower, taking seconds to minutes to run, and is specifically designed to identify contract and configuration errors, highlighting instances where individual components fail to fit together correctly.

Integration Testing vs End-to-End Testing

End-to-end (E2E) tests exercise a complete user journey through the real system: browser, frontend, backend, database, and everything in between. They’re the closest thing to a real user and the most expensive tests you’ll write. Integration tests are narrower. They test a specific seam, not the whole journey. A checkout E2E test would log in, add an item, enter payment details, and confirm the order. The equivalent integration tests would separately verify that the cart service talks to inventory, that the order service talks to payment, and that the confirmation event reaches the email service.

What Is System Integration Testing (SIT)

System integration testing is integration testing at the level of whole systems rather than modules. Instead of checking that two classes work together, SIT checks that your application works with the other systems it depends on: an ERP, a payment processor, a partner’s API, and a data warehouse. 

SIT typically happens after each system has passed its own internal testing and before user acceptance testing. It’s common in enterprise environments where multiple vendors or teams own different pieces, and none of them can see the full picture alone.

How to Run Integration Tests: Workflow and Best Practices

A repeatable workflow keeps integration tests focused and maintainable. Here’s one that works:

1. Identify the boundary under test

The first step is to identify the boundary under test. Be specific. “Test the order service” is too broad. “Test that the order service correctly persists an order and publishes an OrderCreated event” is a valid boundary. Every integration test should be able to name the seam it’s covering.

2. Define your scenarios

For each boundary, list the happy path and the failure modes that matter. What happens when the database is unavailable, when the API returns a 500, or when the event payload is missing a required field? Failure scenarios are where integration tests earn their keep. Skipping them turns the suite into a smoke test.

3. Choose your test doubles

Decide what’s real and what’s faked. A common pattern is:

  • Real: your own database (in a container), your own services
  • Faked: third-party APIs, payment providers, anything with rate limits or cost

The rule of thumb is to keep real anything you own and control, and fake anything you don’t. Fakes for external services should be based on recorded real responses, not guesses.

3. Implement using Arrange-Act-Assert-Teardown

To implement, arrange the state (seed the database, start the container, configure the mock), act by calling the code under test, assert on the outcome, including side effects like database rows or published events, and tear down so the next test starts clean. Teardown is the step teams skip, and it’s the source of most flaky integration suites. If test A leaves a row behind and test B assumes an empty table, you get failures that depend on execution order.

4. Run in CI

Integration tests belong in the pipeline, not on someone’s laptop. Run them on every pull request if they’re fast enough, or on merge to main if they’re not. Spin up fresh infrastructure for each run rather than sharing a long-lived test database.

5. Triage and report

An integration failure needs to answer three questions fast: which boundary, which scenario, and what changed. Structured test names and clear assertion messages help. So does tracking results over time, so you can distinguish a new regression from a flaky test that's been flaky for weeks and nobody has fixed.

What Is Automated Integration Testing

Automated integration testing means the tests run without human intervention as part of your build. The code, the infrastructure setup, the execution, and the reporting are all scripted. The alternative, manual integration testing, still has a place for exploratory work and for one-off SIT cycles. But for anything that needs to run repeatedly, automation is the only option that scales.

Automated integration testing, while necessary for repetitive runs, fails in predictable ways, sich as:

  • Overly broad test scope. A test that exercises five services at once is an E2E test in disguise. When it fails, you’re back to guessing.
  • Shared mutable state between tests. Tests that read or write the same rows, files, or queues without isolation will pass alone and fail together.
  • Hard-coded timeouts that pass locally and fail in CI. Your laptop starts a container in two seconds. The CI runner takes eight. Poll for readiness instead of sleeping for a fixed duration.
  • Brittle assertions on non-deterministic data. Timestamps, auto-generated IDs, and ordering of unordered collections will vary. Assert on what matters, not on exact output.

Integration Testing Tools Worth Knowing in 2026

Integration testing doesn’t have a single dominant tool. Here’s what your stack needs to contain: You assemble a stack: a test harness to run tests, infrastructure tooling to provide real dependencies, mocking tools for external services, contract testing for API boundaries, and a test management layer to keep track of it all.

Test Harnesses

A test harness is necessary to run tests. Good tool options are:

  • JUnit 5. The default for JVM projects. Its extension model supports lifecycle hooks for starting and stopping infrastructure around test classes.
  • pytest. The standard for Python. Fixtures with configurable scope make it straightforward to share a database connection across a test module and tear it down afterward.
  • Jest. Widely used for JavaScript and TypeScript. Works for integration tests against Node services, though you’ll typically pair it with a separate tool for infrastructure.

Infrastructure & Mocking

Infrastructure and mocking help provide real dependencies.

  • Testcontainers. Spins up real databases, message brokers, and other services in Docker containers from within your test code, then tears them down. Available for Java, Go, .NET, Python, Node, and others. It’s become the standard answer to “how do I test against a real Postgres without a shared test database?”
  • WireMock / Hoverfly. Both simulate HTTP APIs. WireMock lets you define stubbed endpoints with request matching and response templating. Hoverfly can capture real traffic and replay it, which is useful for building fakes of third-party APIs from actual responses.
  • Postman / Newman. Postman collections define API requests and assertions. Newman runs those collections from the command line, so the same checks you built interactively can run in CI.

Contract Testing

Contract testing is a specialized form of integration testing where the consumer and provider each verify against a shared contract rather than testing against each other directly. It’s particularly useful for microservices owned by different teams.

  • Pact. Good for consumer-driven contract testing. The consumer defines what it expects, generates a contract file, and the provider verifies it can meet that contract. Supports multiple languages through a shared core.
  • Spring Cloud Contract. Good for contract testing for JVM services in the Spring ecosystem. Contracts are written in Groovy or YAML and generate both provider-side tests and consumer-side stubs.

Test Management

A test management layer is necessary to keep track of everything you will do in the steps above.

TestFiesta. TestFiesta is a test management platform that helps track which integration scenarios exist, which boundaries are covered, what’s passing over time, and which failures have already been filed as bugs. In addition to supporting your integration testing, it can cover all the test cases in your entire testing pyramid, helping you build reliable, scalable products.

Managing integration tests shouldn’t be a hurdle.

With TestFiesta, you can track your test scenarios, monitor boundary coverage, and surface regression risks in one place.

Start a free trial today

FAQs

Is integration testing the same as API testing?

No, integration testing is not the same as API testing, though they overlap. API testing verifies that an API behaves according to its specification. Integration testing verifies that components work together, and one of those components might be an API. 

Can integration tests replace end-to-end tests entirely?

Not entirely. Integration tests verify that each boundary works. E2E tests verify that the whole journey works, including the frontend and things like session handling that integration tests don’t touch. A good suite has many integration tests and a small number of E2E tests covering the critical paths. Eliminating E2E completely means something important will remain untested.

How many integration tests should a healthy test suite have?

There’s no fixed number for integration tests in a suite. The testing pyramid suggests that integration tests should be fewer than unit tests and more than E2E tests, but the right count depends on how many boundaries your system has and how risky each one is. 

What’s the difference between integration testing and UAT?

Integration testing checks that the system’s components work together technically. User acceptance testing (UAT) checks that the system does what the business needs, usually performed by end users or business stakeholders against realistic scenarios. 

Best practices
Testing guide

Introduction

Manual testing and automated testing are the two ways a QA team verifies that software works. In manual testing, a person runs the application and checks the results. In automated QA testing, scripts do the running, and a tester reads the results. 

This guide covers what manual and automated testing are designed for, where each one fits and fails, and how to decide the ideal testing approach split for your own team based on what you’re building.

What Is Manual Testing

Manual testing is a type of software testing where a human runs the software the way a user would, without automated scripts executing the steps for them. The tester opens the app, follows a test case or their own line of thinking, watches what happens, and records what they find. That’s a simple way to describe it. 

Following a written test case step by step is the least interesting part of the job. What separates a good manual tester from someone clicking buttons is judgment and the ability to notice small details, such as a form accepting information that it shouldn’t, a loading spinner hanging a beat too long, or a vague error message that’s not any help to the users. None of these issues could formally be a part of any test case, but a manual tester would still catch them, as opposed to an automated script that would pass them.

Since manual testing involves human judgment, it’s slow. But in the long run, it uncovers issues during testing that could otherwise appear in production, which is its primary benefit.

Where Manual Testing Works

A good tester recognizes that automation cannot do everything. Manual testing is the right call for a lot of scenarios, including:

  • Exploratory testing: In exploratory testing, a tester works without a script or a written test case. They manually form and test hypotheses about where the software breaks. This is where the bugs nobody wrote a test case for get found.
  • Usability and UX evaluation: A script can confirm a button exists and is clickable, but it can’t tell you if the button is in the wrong place, the label is confusing, or the flow takes two steps more than it should. That’s where testers utilize usability testing and UX evaluation.
  • Accessibility testing: Automated scanners are useful, but they catch a fraction of the problems. In many cases, automated accessibility testing tools only find half the issues that a manual tester can find simply by navigating through the screens.
  • Early-stage features: When the UI is being redesigned every few days, automation written previously would be broken after the changes. Manual testing absorbs the change without maintenance cost.
  • One-off tests: Automation works well when you’re doing it at scale. For one-off tests like data migrations, configuration changes, and a release-specific check, manual testing is more efficient. 

What Is Automated Testing

Automated testing uses scripts and tools to execute test cases programmatically. Someone writes the test once, and from then on, it runs automatically, on demand or on a schedule, as many times as needed, at whatever hour the pipeline triggers.

The standard way to think about the layers is the testing pyramid. At the base of the pyramid are unit tests, which are fast and isolated and check individual functions. Above the base are integration tests, which verify that components work together. At the top are end-to-end tests that drive the full application through the UI. The pyramid shape is the point. You want many cheap and quick tests at the bottom and few expensive, slow, and fragile ones at the top.

Automation exists to take repetitive verification off people’s plates so they can do more strategic work. A team with a focus on automation doesn’t need fewer testers. It needs its testers to do exploratory and usability testing instead of re-running last quarter’s regression suite by hand.

Where Automated Testing Works

Automation pays off when the same check needs to run many times, or when the check is physically impossible for a human to perform, such as:

  • Regression testing: Regression testing verifies that the new code didn’t break existing functionality. This is the single highest-return automation target because the suite runs on every change and the cost of writing it is amortized across hundreds of executions.
  • Smoke tests: Smoke tests are a small set of checks on critical paths (login, checkout, the core workflow) that run after every deployment. They take minutes and catch the failures that would otherwise reach users first.
  • API testing: APIs change less often than UIs and don’t have layouts to break. API testing is fast, stable, and cheap to maintain, and API tests catch broken changes before a frontend ever hits them.
  • Performance and load testing: Making sure that your software works as well on 5000 users as it does on 500 is not something you can do manually. That’s why performance testing exists, and it’s done through automation.
  • Cross-browser and cross-device testing: Cross-browser and cross-device testing runs the same test suite across browsers, such as Chrome, Firefox, and Safari, and a range of screen sizes, such as desktop, mobile, and tablet, in parallel. Doing this manually means multiplying every test case by every test environment, which is why these tests are automated.
  • Data-driven tests: Data-driven tests are executed on specific data, such as a form with 50 valid and invalid input combinations, which is tedious to test by hand and trivially parameterized in code.

The Difference Between Manual and Automated Testing

Choosing between manual and automated testing is not a one-off decision. And QA teams should stop thinking in terms of which approach is better. The right question to ask is which approach is the right one for your product. 

Manual vs Automated Testing

Here’s a table that will make things easier to understand:

Manual testing Automated testing
Best at Finding unknown problems Confirming known behavior still works
Speed per run Slow Fast once written
Upfront cost Low High (tooling, scripting, setup)
Ongoing cost Scales with every run Maintenance when the app changes
Repeatability Varies by tester and day Identical every time
Handles UI change Adapts immediately Breaks, needs updating
Catches Usability, accessibility, edge cases nobody scripted Regressions, performance, high-volume data cases
Misses Anything too repetitive or high-volume to do thoroughly Anything requiring judgment about whether the result is good, not just correct

Most mature teams utilize both manual and automated testing, with around 70 percent of test execution automated and 30 percent manual. That said, there’s no hard-and-fast rule about the ideal split. A backend-heavy platform with stable APIs can push well past 70 percent, and a consumer app in active redesign should sit closer to 50 percent. The split matters less than what goes on each side: repetition to the machines, judgment to the people.

Manual vs Automated Testing: Pros and Cons

Here are some pros and cons of manual and automated testing.

Manual Testing

Manual testing’s pros include:

  • No setup, tooling, or scripting cost to get started
  • Finds bugs that weren’t anticipated
  • The only option for usability, accessibility, and exploratory work
  • Adapts to UI changes instantly
  • Testers build product knowledge that feeds back into design and requirements

Manual testing’s common cons are:

  • Slow, and cost grows linearly with every run
  • Results vary by tester and their attention to detail
  • Can’t cover load, performance, or large data sets
  • Regression cycles get longer as the product grows
  • Prone to human error

Automated Testing

Automated testing pros are:

  • Runs in minutes, at any hour, on every commit
  • Identical execution every time
  • Handles volume no human can: thousands of users, hundreds of inputs, dozens of browsers
  • Cost per run approaches zero over time
  • Frees testers for higher-value work

Automated testing’s common cons include:

  • Significant upfront investment in tools, infrastructure, and skills
  • Maintenance burden every time the application changes
  • Flaky tests erode trust in the whole suite
  • Only checks what it was told to check; a passing suite proves nothing about what wasn't scripted
  • Poorly chosen automation (usually too much at the UI layer) costs more than it saves

TestFiesta Gives Your QA Team a Home for Both

The gap on most teams isn’t a shortage of testers or a shortage of scripts. It’s that the results of both manual and automated testing don’t often live in the same place. Automated runs report into CI dashboards, whereas manual test cases live in a spreadsheet, a wiki, or a tool the automation engineers never open. 

When a release manager is about shipping, someone has to go collect answers from three different places and stitch them together, and the stitching is where things get missed.

TestFiesta puts manual and automated testing under one roof. Manual test cases, exploratory sessions, and automated results feed into the same test runs, so coverage is visible in one view instead of being inferred from several. 

In TestFiesta, you can see which requirements are covered by automation, which are covered manually, and which aren’t covered at all. When a regression suite passes but a tester flags a usability problem in the same feature, both show up together against the same release.

Bring your manual and automated testing under TestFiesta, centralize your test cases, and release with total confidence.

Start your free trial today

FAQs

Will automated testing eventually replace manual testing entirely?

No, automation replaces repetition, not judgment. A script only checks what it was told to check, so usability, accessibility, and exploratory work still need a person and human judgment. 

What’s the best tool to start with for automated testing?

The best tools for automated testing depend on your needs. For web UI, Playwright is the strongest current option. For mobile testing, use Appium. Begin with five to ten smoke tests on your most critical paths, get them running in CI, and expand from there.

How much of our QA budget should go toward automation?

To decide the budget to go toward automation, look carefully at your regression suites because that’s the first thing you need to automate. From then on, look at other forms of testing that can be automated, such as smoke testing, API testing, and cross-browser and cross-device testing. Building and scaling these test suites often takes more time and cost than it would take to automate them. A good rule of thumb is to start with a 70 percent automation and 30 percent manual split, and then change the split based on your needs.

Testing guide

Introduction

Most problems that occur during development aren’t related to development at all. They’re mostly about the process around it. The software development life cycle is a process that deals with and prevents the failures associated with shifting requirements, late testing, or post-launch workload. 

In this guide, we’ll talk about the seven phases of the software development life cycle, compare the different life cycle models, discuss what a real agile sprint looks like in development, and give you a practical framework for picking the right approach for your project.

What Is the Software Development Life Cycle (SDLC)

Every piece of software you use, from your banking app to the platform you’re reading this on, went through some version of the same journey: someone planned it, designed it, built it, tested it, shipped it, and now keeps it running. The software development life cycle (SDLC) is the name for that journey.

More formally, the SDLC is a structured process that takes software from an initial idea to a live, maintained product. It breaks development into distinct phases, each with its own goals and deliverables, so teams know what they’re doing, why they’re doing it, and what “done” looks like at every step.

Why the Software Development Life Cycle Is Important

Software projects fail far more often from process problems than from technical ones, such as requirements that were never pinned down, testing squeezed into the last two weeks, or no after-launch plan. The SDLC exists to prevent exactly these kinds of failures. It gives teams a shared map, and a shared map means fewer surprises, less rework, and software that actually does what it was supposed to do.

A key thing to remember here is that the SDLC is not paperwork for its own sake. A three-person startup and a 300-person enterprise team both follow a life cycle, whether they formally name it or not. The only question is whether they follow it deliberately or by accident, and a deliberate approach is cheaper and more effective every single time.

The software development life cycle is different from the software testing life cycle, which mostly deals with the testing process.

The Phases of the Software Development Life Cycle (SDLC)

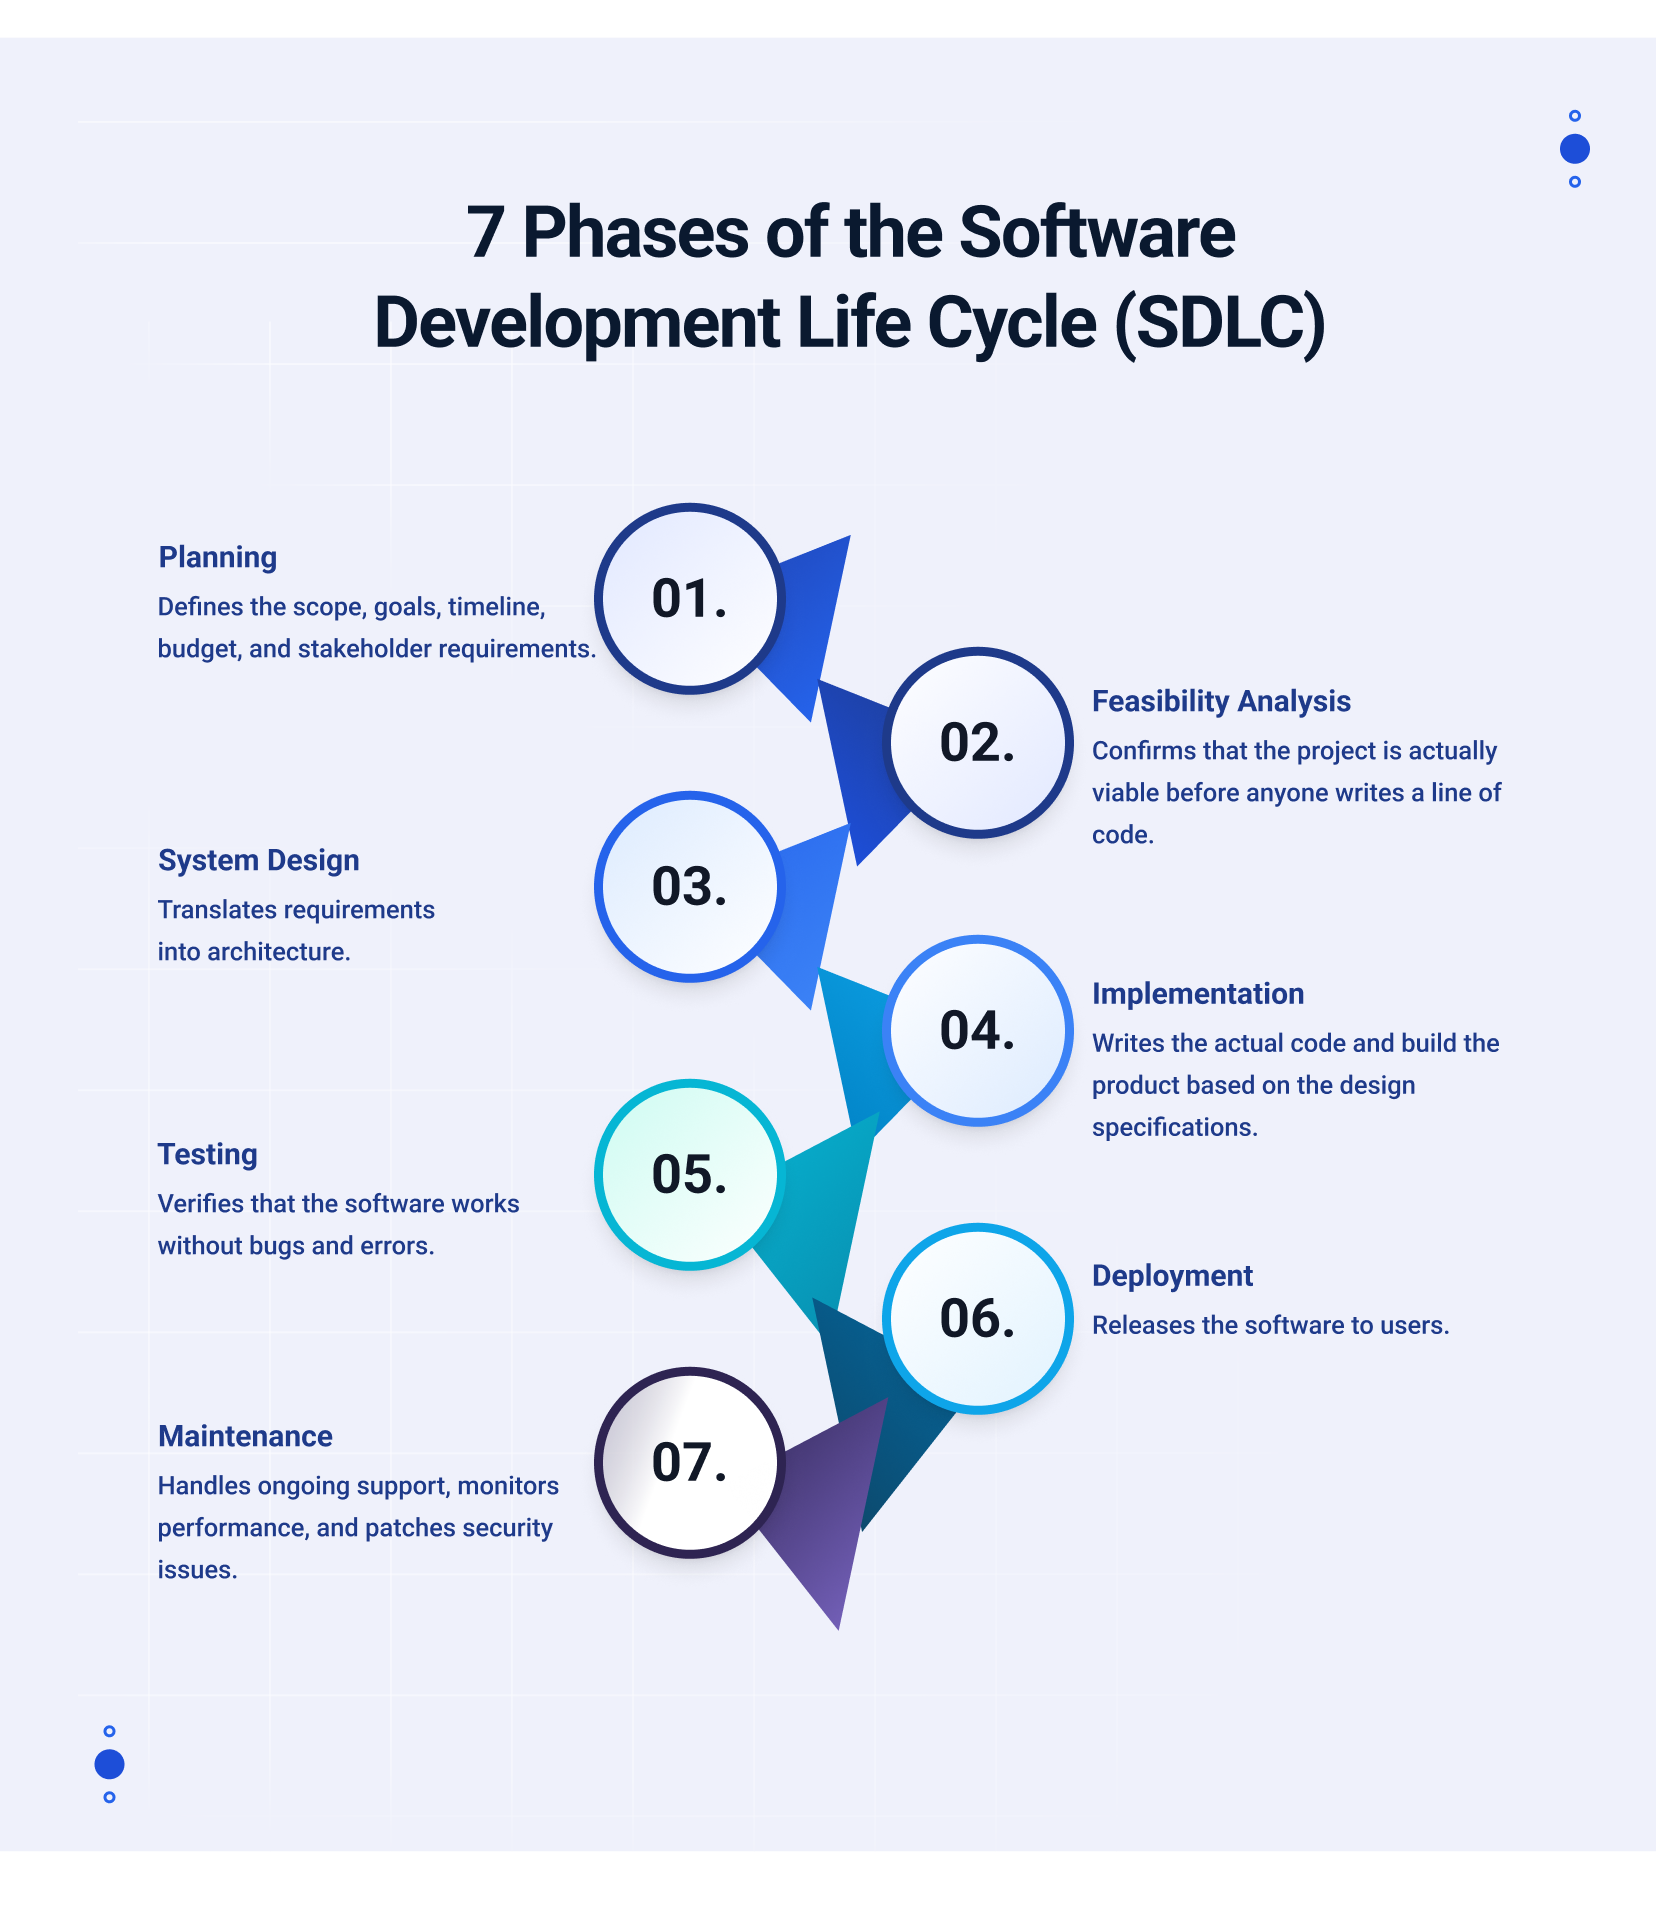
SDLC usually has seven phases that help development teams plan the entire development and post-launch steps for their product. These phases are

The seven phases of the software development life cycle (SDLC)

1. Planning

Planning includes defining the scope, goals, timeline, budget, and stakeholder requirements. This is the foundation everything else is built on, and weak planning shows up as problems in every phase that follows.

2. Feasibility Analysis

Feasibility analysis helps teams confirm that the project is actually viable and has practical benefit before anyone writes a line of code. A couple of key questions to ask are: Can the product be built with the technology and team you have, and does the budget hold up? If the answer is no, it’s time to redo your project foundation.

3. System Design

System design helps translate requirements into architecture. This is where you choose the tech stack, map out the database schema, design the UI/UX, and define how APIs will talk to each other.

4. Implementation (Coding)

Developers write the actual code based on the design specs. This is typically the longest phase because it involves building the entire product. It’s the phase most people picture when they think of software development. 

5. Testing

Testing is the process of verifying and validating that the software works. It catches bugs in the software and confirms that everything meets the requirements. Unit tests check individual components, integration tests check how they work together, and system tests check the product as a whole. Together, these tests make a testing pyramid that most testing teams follow.

6. Deployment

Deployment involves releasing the software to users. Most teams do this in stages: a beta for early adopters, a limited rollout, then a full launch once things look stable. But there’s no hard-and-fast rule for deployment. 

7. Maintenance

Deployment is not the end of the process. Ongoing support is necessary to fix bugs that show up in production, monitor performance and conduct regular performance testing, patch security issues, and develop new features. Healthy software spends most of its life in this phase.

The Most Common SDLC Models and When to Use Each

Nearly every team goes through the same SLDC phases, but not every team goes through them the same way. Some move in a straight line, phase by phase. Others loop through all of them every two weeks. How teams move through the phases is defined by the model they’re using to build software. Choosing the right model for your project matters just as much as following the process itself. Here are the most common models teams follow:

1. Waterfall: Structure-Oriented 

Waterfall is the original SDLC model, and it works exactly like it sounds. You complete one phase fully, sign it off, and move to the next. Requirements first, then design, then coding, then testing, then release. No going back upstream.

That rigidity gets Waterfall a bad reputation, but it’s genuinely the right choice for some projects. If your scope is fixed, your requirements are stable, and your stakeholders know exactly what they want (think government contracts, regulated industries, or hardware-adjacent software), the phase-by-phase discipline is a strength. Everything is documented, everyone knows the plan, and there’s a clear audit trail.

The limitation is just as clear. If requirements change mid-project, Waterfall has no good answer. Changes discovered during testing mean going back to designs that were signed off months ago, and that gets expensive fast.

2. Agile: Iterative Approach 

Agile flips the Waterfall logic. Instead of running each phase once over many months, Agile teams run all of them in short, repeated cycles called sprints. Plan a small slice of the product, design it, build it, test it, show it to stakeholders, gather feedback, then start the next cycle with that feedback baked in.

A common misconception is that Agile replaces the SDLC phases. That’s not true. Agile doesn’t replace SDLC. It compresses and repeats them. You still plan, design, build, and test. You just do it iteratively instead of once per project.

The two most popular Agile frameworks are Scrum, which organizes work into fixed-length sprints with defined roles and ceremonies, and Kanban, which focuses on continuous flow and limiting work in progress. Both are built on the same principle: short feedback loops that beat long-range guesses.

Agile is the best fit for large, complex, or evolving projects where requirements will shift and where clients or end users are available to give regular feedback.

3. DevOps: Development Meets Operations

DevOps often gets listed alongside Waterfall and Agile as if it were another SDLC model. It isn’t, really. DevOps is a set of practices and a culture that layers on top of your existing model, usually Agile. 

The core idea is breaking down the wall between the people who build software and the people who run it in production. In traditional setups, developers throw code over that wall and operations catch whatever lands. DevOps merges the two through automation: continuous integration (CI) automatically builds and tests every code change, and continuous delivery (CD) gets those changes into production quickly and safely.

If your team needs fast, frequent releases and can invest in automated pipelines, DevOps practices are close to non-negotiable. Teams shipping weekly or daily simply cannot rely on manual builds and manual deployments.

How to Pick the Right SDLC Model for Your Project

The right approach to picking the right SDLC model for your project is to ask a few questions before committing. These questions are:

  1. Are your requirements fixed, or likely to evolve? Fixed requirements tolerate a linear model. Evolving requirements demand iteration.
  2. How involved will the client or end users be during development? Agile only works if someone is actually available to give feedback every sprint.
  3. How experienced is your team with iterative vs. structured approaches? A team that’s never run a sprint will stumble through its first few. That’s fine, but plan for it.
  4. What’s your risk tolerance? In other words, how costly would a late-stage change be? The more expensive a late surprise, the more you should invest in upfront analysis or frequent checkpoints.
  5. Do you need continuous deployment, or is a single release acceptable? A one-and-done launch and a ship-every-week product need very different pipelines.

The answers will give you a clear hint about what model you should choose. If you’re genuinely torn between two models, start with the one that gives you feedback sooner. You can always add structure to an iterative process. 

How TestFiesta Fits Into Every Phase of Your SDLC

Most teams handle planning and implementation just fine. It’s testing where structure quietly falls apart: cases scattered across spreadsheets, test runs nobody can trace, and results that never make it back to the people planning the next release. TestFiesta gives your QA process the same structure the rest of your SDLC already has, with organized test cases, clear runs, and results your whole team can actually act on.

Ready to bring order to your testing workflow?

Try TestFiesta today and turn scattered spreadsheets into structured test cases, traceable runs, and actionable insights for your team.

Start your free trial today

FAQs

What’s the difference between SDLC and Agile?

SDLC is a process that manages your entire software development project, and agile is one of the models you can follow to manage that process. They’re not competing concepts, even though it’s a common misconception. The SDLC is the overall process: the phases every software project moves through, from planning to maintenance. Agile is one model for moving through those phases. Agile doesn’t replace SDLC. It runs the phases in short, repeated cycles rather than a single long sequence. 

How long does each phase of the SDLC take?

There’s no universal timeline for how long each SDLC phase will take. The time depends on project size, team, and model. In rough proportions, implementation takes the most time, followed by testing and then planning and design, whereas maintenance is an outlier that takes the most time after the product is deployed. In Agile, these proportions play out inside every sprint rather than across the whole project.

Can a team use more than one SDLC model on the same project?

Yes, teams do use more than one SDLC model on the same project, and it’s more common than most SDLC experts admit. Hybrid approaches work well when different parts of a project have different needs. A team might use Waterfall-style upfront planning for a component with fixed regulatory requirements, then run Agile sprints for the user-facing features that need iteration and feedback. Some organizations informally call this approach “Wagile” or “Water-Scrum-Fall.”

Best practices

Ready for a Platform that Works

The Way You Do?

Stop fighting your tools. Start shipping with confidence. TestFiesta adapts to your workflow, not the other way around.

Welcome to the fiesta!